# Vivgrid — Full Documentation
> Complete Markdown export of Vivgrid's documentation and articles for LLMs and AI agents.
# Alchemist - Agent Evaluation Tool
> Source: https://vivgrid.com/docs/agent-evaluation
Alchemist is Vivgrid's agent evaluation tool that enables developers to run recursive and regression evaluations to validate AI agent behavior before release.
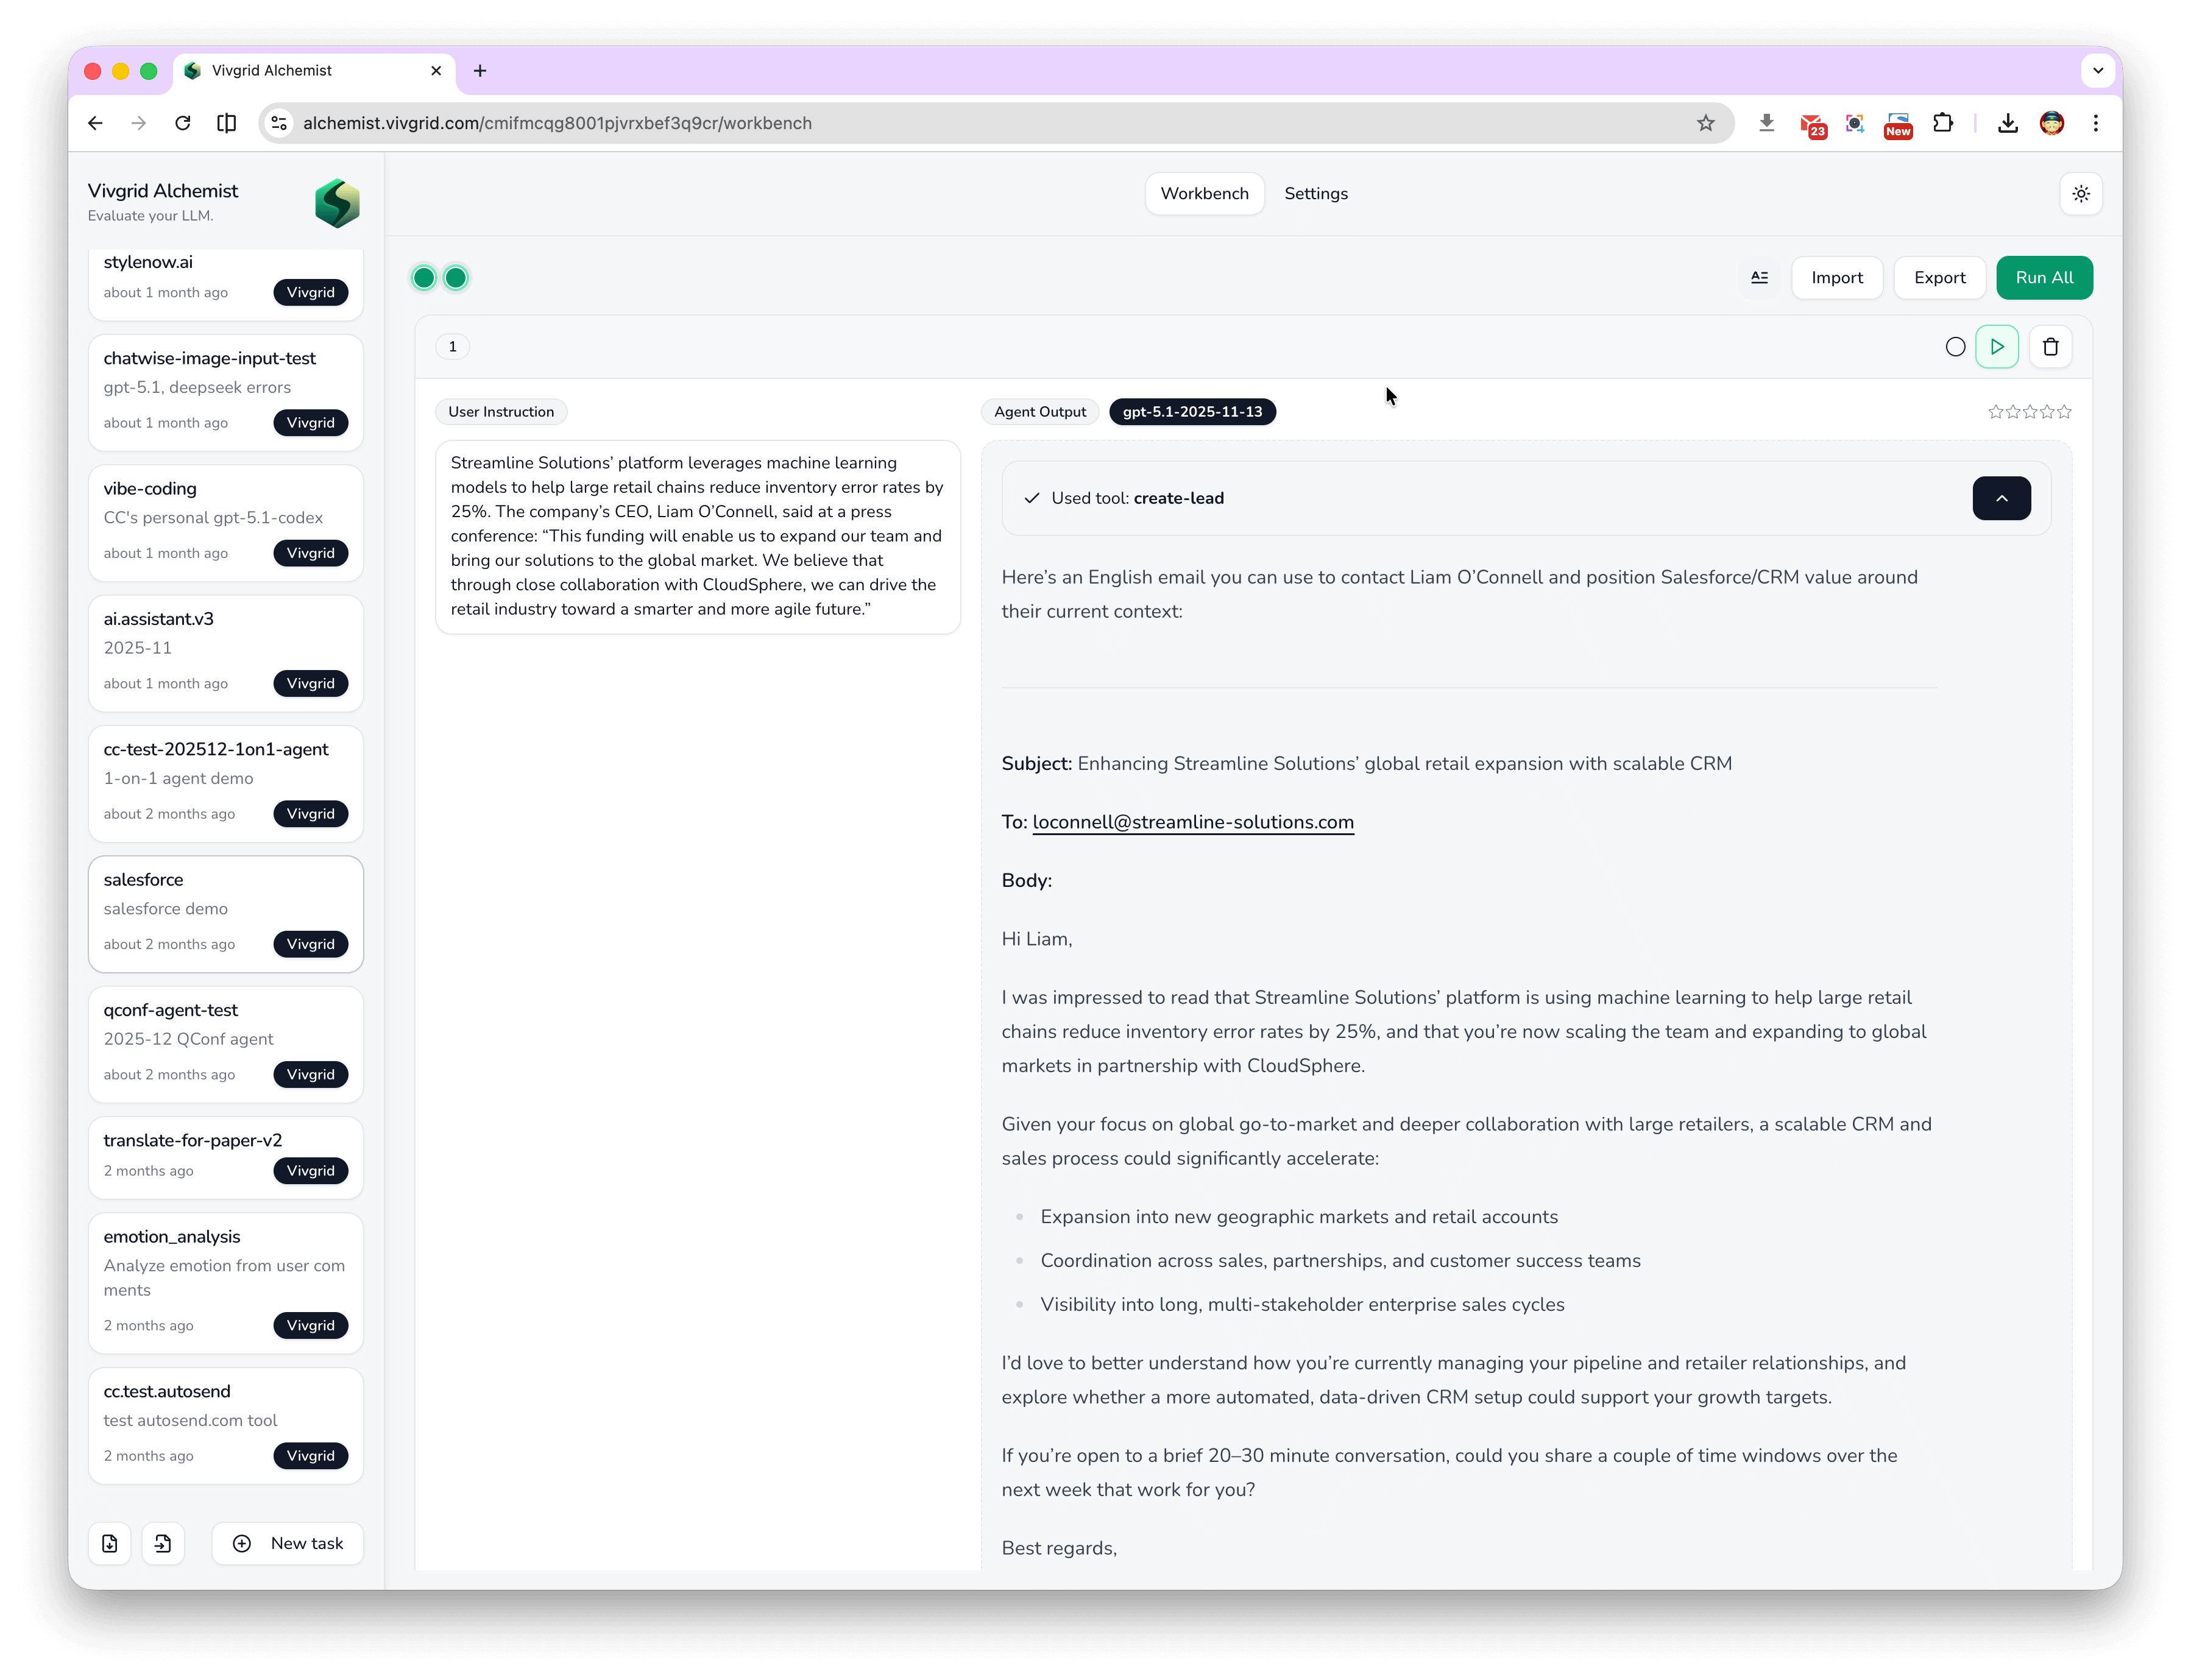
Open [Alchemist](https://alchemist.vivgrid.com)
---
# Introduction
> Source: https://vivgrid.com/docs/introduction
Vivgrid is the Managed Skills platform — cloud-hosted LLM function calling for enterprise AI agents, with built-in observability and evaluation.
Vivgrid is the Managed Skills platform: cloud-hosted LLM function calling that lets enterprise AI agents run their tools in the cloud — with observability, evaluation, and globally distributed inference built in.
## Build AI Agents
AI Agents are rapidly gaining adoption as large language models become more capable of executing complex tasks through reliable tool calling and reasoning. High-quality AI Agents require continuous optimization across three core dimensions:
- Accuracy
- Latency
- Cost efficiency
Sustained improvement across these dimensions is essential for production-grade agent systems.
Vivgrid follows a decoupled architecture: agent logic is separated from client applications. This significantly reduces iteration friction, allowing teams to evolve agent capabilities independently while maintaining stable integrations.
Vivgrid provides the following capabilities to help developers build, deploy, and operate AI Agents at scale:
} href="/docs/managed-skills">
Build strongly typed AI tools and run them as Managed Skills with minimal operational overhead.
{/* } href="/docs/system-prompt">
Update system prompts in real time from the dashboard without redeploying agents.
*/}
} href="/docs/models">
Access SOTA models through a unified, production-ready endpoint.
} href="/docs/agent-evaluation">
Run recursive and regression evaluations to validate agent behavior before release.
} href="/docs/observability">
Analyze agent performance with detailed request logs, latency breakdowns, and cost metrics.
## Model API
Vivgrid also provides a unified LLM Model API, enabling direct access to commonly used models for coding, text, speech, and multimodal workloads. The API can be seamlessly integrated into third-party tools such as Claude Code, Cursor, OpenCode, n8n, and Dify.
Vibe Coding Models
Supported coding models include:
- [`gpt-6-astra`](/docs/models/gpt-6-astra)
- [`claude-fable-5-1`](/docs/models/claude-fable-5-1)
- [`gemini-3.8-flash`](/docs/models/gemini-3.8-flash)
- [`deepseek-v4-pro-0813`](/docs/models/deepseek-v4-pro-0813)
These models are optimized for code generation, completion, refactoring, and interactive development workflows.
Additional Models
Vivgrid supports a broad range of model capabilities, including:
- Text-to-Speech (TTS)
- Speech-to-Text (Whisper)
- OCR
- Reranking
For the complete and up-to-date model specification, refer to [models](/docs/models), and checkout the [API reference](/model-api) documentation for detailed usage instructions.
---
# Managed Skills
> Source: https://vivgrid.com/docs/managed-skills
Build a strongly typed AI skill (Function Tool or MCP Tool) and deploy it to Vivgrid's global network in minutes with Yomo and the viv CLI.
**Managed Skills** are the tools your AI agent can call to act on the real world. On Vivgrid, a skill can be a **Function Tool** (via the function calling API) or an **MCP Tool** (via the Model Context Protocol). This guide walks you through building and deploying your first skill.
## Set Up Your Development Environment
Start by writing your first skill.
### Prepare
Log in to the [Vivgrid Console](https://console.vivgrid.com) and create a new `Project`.
You will receive an `APP_KEY` and `APP_SECRET`. Keep them safe—you will need them later for local debugging or deployment.
`curl -fsSL https://get.yomo.run | sh`
## Write Your First Skill
First run `yomo init -l node ./llm-tool` to initialize your skill project.
A skill is a Node.js project with three exports in `src/app.ts`: a `description`, an `Argument` type, and a `handler`. The Yomo CLI turns these exports into a discoverable, LLM-callable function—no server boilerplate required.
```ts src/app.ts
export const description = `Get current weather for a given city. If no city is provided, you
should ask to clarify the city. If the city name is given, you should
convert the city name to Latitude and Longitude geo coordinates, keeping
Latitude and Longitude in decimal format.`
export type Argument = {
city: string
latitude: number
longitude: number
}
async function getWeather(args: Argument) {
console.log('->city: ', args.city, 'latitude: ', args.latitude, 'longitude: ', args.longitude)
try {
const response = await fetch(`https://api.openweathermap.org/data/2.5/weather?lat=${args.latitude}&lon=${args.longitude}&appid=${process.env.OPENWEATHERMAP_API_KEY}&units=metric`)
if (!response.ok) {
return 'can not get the weather information at the moment'
}
const data = await response.json()
return JSON.stringify({ city: args.city, ...data })
} catch (error) {
console.error(error)
return 'can not get the weather information at the moment'
}
}
/**
*
* Handler orchestrates the core processing logic of this function.
* @param args - LLM Function Calling Arguments(optional).
* @returns The result of the retrieval is returned to the LLM for processing.
*/
export async function handler(args: Argument) {
const result = await getWeather(args)
return result
}
```
## Run Locally or on a Self‑Managed Server
Create a `.env` file to supply the API keys your skill needs:
```sh .env
OPENWEATHERMAP_API_KEY=
```
Then install dependencies and run the skill, connecting it to Vivgrid with your `APP_KEY`:
```sh
yomo run \
--name tool_get_weather \
--zipper zipper.vivgrid.com:9000 \
--credential
```
## Deploy Globally as Managed Skills
We provide the `viv` cli to ease the provisioning stage, install it:
`curl "https://bina.egoist.dev/vivgrid/cli?file=viv&name=viv" | sh`
Create a `vivgrid.yml` file in the root of your project directory, then run:
`viv deploy . --env OPENWEATHERMAP_API_KEY=`.
An example `vivgrid.yml` file:
```yaml vivgrid.yml
secret:
tool: tool_get_weather
```
## Test Your Skill
```sh
curl -v -i https://api.vivgrid.com/v1/chat/completions \
-H "Content-Type: application/json" \
-H "Authorization: Bearer " \
-d '{
"messages": [{
"role": "user",
"content": "how is the weather today in Paris and Tokyo?"
}],
"stream": true
}'
```
---
# Models
> Source: https://vivgrid.com/docs/models
All AI models supported by Vivgrid — including GPT-5, Claude Opus/Sonnet, Gemini, and DeepSeek variants for coding, text, speech, and multimodal workloads.
Vivgrid provides access to a range of powerful AI models for building enterprise-grade AI agents. We select models based on their performance, cost-effectiveness, and suitability for various tasks. Pricing is transparent and matches the rates of the original providers.
## Supported Models
### Coding Models
- [`gpt-6-astra`](/docs/models/gpt-6-astra)
- [`claude-fable-5-1`](/docs/models/claude-fable-5-1)
- [`gemini-3.8-flash`](/docs/models/gemini-3.8-flash)
- [`claude-fable-5`](/docs/models/claude-fable-5)
- [`deepseek-v4-pro-0813`](/docs/models/deepseek-v4-pro-0813)
- [`glm-5.3-flash`](/docs/models/glm-5.3-flash)
- [`deepseek-v4-flash-vision-exp`](/docs/models/deepseek-v4-flash-vision-exp)
- [`deepseek-v4-flash (0731)`](/docs/models/deepseek-v4-flash)
- [`gemini-3.7-flash`](/docs/models/gemini-3.7-flash)
- [`glm-5.3`](/docs/models/glm-5.3)
- [`gemini-3.6-flash`](/docs/models/gemini-3.6-flash)
- [`claude-opus-5`](/docs/models/claude-opus-5)
- [`kimi-k3`](/docs/models/kimi-k3)
- [`gpt-5.6-sol`](/docs/models/gpt-5.6-sol)
- [`gpt-5.6-terra`](/docs/models/gpt-5.6-terra)
- [`claude-opus-4.8`](/docs/models/claude-opus-4-8)
- [`claude-sonnet-5`](/docs/models/claude-sonnet-5)
- [`gpt-5.5`](/docs/models/gpt-5.5)
- [`glm-5.2`](/docs/models/glm-5.2)
- [`claude-opus-4.7`](/docs/models/claude-opus-4-7)
- [`claude-opus-4.6`](/docs/models/claude-opus-4-6)
- [`claude-sonnet-4.6`](/docs/models/claude-sonnet-4-6)
- [`claude-haiku-4.5`](/docs/models/claude-haiku-4-5)
- [`gemini-3.1-pro-preview`](/docs/models/gemini-3.1-pro-preview)
- [`gpt-5.4`](/docs/models/gpt-5.4)
- [`gpt-5.3-codex`](/docs/models/gpt-5.3-codex)
- [`gpt-5.2-codex`](/docs/models/gpt-5.2-codex)
- [`gpt-5.1-codex-max`](/docs/models/gpt-5.1-codex-max)
- [`gpt-5.1-codex`](/docs/models/gpt-5.1-codex)
- [`glm-5.1`](/docs/models/glm-5.1)
- [`kimi-k2.6`](/docs/models/kimi-k2.6)
- [`minimax-m2.7`](/docs/models/minimax-m2.7)
- [`minimax-m3`](/docs/models/minimax-m3)
### Agent Models
- [`gpt-6-astra`](/docs/models/gpt-6-astra)
- [`claude-fable-5-1`](/docs/models/claude-fable-5-1)
- [`gemini-3.8-flash`](/docs/models/gemini-3.8-flash)
- [`claude-fable-5`](/docs/models/claude-fable-5)
- [`deepseek-v4-pro-0813`](/docs/models/deepseek-v4-pro-0813)
- [`deepseek-v4-flash-vision-exp`](/docs/models/deepseek-v4-flash-vision-exp)
- [`deepseek-v4-flash (0731)`](/docs/models/deepseek-v4-flash)
- [`gemini-3.7-flash`](/docs/models/gemini-3.7-flash)
- [`gemini-3.6-flash`](/docs/models/gemini-3.6-flash)
- [`claude-opus-5`](/docs/models/claude-opus-5)
- [`kimi-k3`](/docs/models/kimi-k3)
- [`gpt-5.6-sol`](/docs/models/gpt-5.6-sol)
- [`gpt-5.6-terra`](/docs/models/gpt-5.6-terra)
- [`gpt-5.6-luna`](/docs/models/gpt-5.6-luna)
- [`gemini-3.5-flash`](/docs/models/gemini-3.5-flash)
- [`gpt-5.5`](/docs/models/gpt-5.5)
- [`deepseek-v4-pro`](/docs/models/deepseek-v4-pro)
- [`gpt-5.4`](/docs/models/gpt-5.4)
- [`gpt-5.4-mini`](/docs/models/gpt-5.4-mini)
- [`gpt-5.4-nano`](/docs/models/gpt-5.4-nano)
- [`gemini-3.1-pro-preview`](/docs/models/gemini-3.1-pro-preview)
- [`gemini-3.1-flash-lite-preview`](/docs/models/gemini-3.1-flash-lite-preview)
- [`gpt-5.2`](/docs/models/gpt-5.2)
- [`gpt-5.1`](/docs/models/gpt-5.1)
- [`gpt-5`](/docs/models/gpt-5)
- [`gpt-5-mini`](/docs/models/gpt-5-mini)
- [`gemini-3-pro-preview`](/docs/models/gemini-3-pro-preview)
- [`gemini-3-flash-preview`](/docs/models/gemini-3-flash-preview)
- [`glm-5.1`](/docs/models/glm-5.1)
- [`kimi-k2.6`](/docs/models/kimi-k2.6)
- [`minimax-m3`](/docs/models/minimax-m3)
### Image Models
- [`gemini-3-pro-image`](/docs/models/gemini-3-pro-image)
- [`gemini-3.1-flash-image`](/docs/models/gemini-3.1-flash-image)
## How to Set Models for your Agent Project
You don't need to specify a `model-name` in your API calls. The model for your agent is managed on the backend, so switching models won't require any code changes.
To change the model for your agent, go to the **Agent Settings** page in the Vivgrid Console.
## Pricing
Pricing is calculated in USD per 1 million tokens. The table below details the cost for input, cached, and output tokens for each model.
Image generation models bill generated images as output tokens at their own rate — see [gemini-3-pro-image](/docs/models/gemini-3-pro-image) and [gemini-3.1-flash-image](/docs/models/gemini-3.1-flash-image) for the per-image token conversion at each resolution.
| Model | Input Token | Cached Token | Output Token |
| --------------------- | ----------- | ------------ | ------------ |
| **[gpt-6-astra](/docs/models/gpt-6-astra)** | \$10.00 (\<= 272k tokens)
\$20.00 (> 272k tokens) | \$1.00 (\<= 272k tokens)
\$2.00 (> 272k tokens) | \$50.00 (\<= 272k tokens)
\$75.00 (> 272k tokens) |
| **[claude-fable-5-1](/docs/models/claude-fable-5-1)** | \$10.00 | \$0.50 | \$50.00 |
| **[gemini-3.8-flash](/docs/models/gemini-3.8-flash)** | \$0.75 | \$0.15 | \$3.75 |
| **[claude-fable-5](/docs/models/claude-fable-5)** | \$10.00 | \$1.25 | \$50.00 |
| **[glm-5.3-flash](/docs/models/glm-5.3-flash)** | \$0.15 | \$0.04 | \$0.50 |
| **[deepseek-v4-pro-0813](/docs/models/deepseek-v4-pro-0813)** | \$1.35 | \$0.05 | \$3.00 |
| **[deepseek-v4-flash-vision-exp](/docs/models/deepseek-v4-flash-vision-exp)** | \$0.44 | \$0.044 | \$1.32 |
| **[deepseek-v4-flash (0731)](/docs/models/deepseek-v4-flash)** | \$0.44 | \$0.044 | \$1.32 |
| **[gemini-3.7-flash](/docs/models/gemini-3.7-flash)** | \$0.75 | \$0.075 | \$3.75 |
| **[glm-5.3](/docs/models/glm-5.3)** | \$1.20 | \$0.30 | \$4.20 |
| **[gemini-3.6-flash](/docs/models/gemini-3.6-flash)** | \$0.75 | \$0.075 | \$3.75 |
| **[gemini-3-pro-image](/docs/models/gemini-3-pro-image)** | \$2.00 | \$0.20 | \$12.00 (text)
\$120.00 (image) |
| **[gemini-3.1-flash-image](/docs/models/gemini-3.1-flash-image)** | \$0.50 | \$0.05 | \$3.00 (text)
\$60.00 (image) |
| **[claude-opus-5](/docs/models/claude-opus-5)** | \$5.00 | \$0.50 | \$25.00 |
| **[kimi-k3](/docs/models/kimi-k3)** | \$3.00 | \$0.30 | \$15.00 |
| **[gpt-5.6-sol](/docs/models/gpt-5.6-sol)** | \$5.00 (\<= 272k tokens)
\$10.00 (> 272k tokens) | \$0.50 (\<= 272k tokens)
\$1.00 (> 272k tokens) | \$30.00 (\<= 272k tokens)
\$45.00 (> 272k tokens) |
| **[gpt-5.6-terra](/docs/models/gpt-5.6-terra)** | \$2.50 (\<= 272k tokens)
\$5.00 (> 272k tokens) | \$0.25 (\<= 272k tokens)
\$0.50 (> 272k tokens) | \$15.00 (\<= 272k tokens)
\$22.50 (> 272k tokens) |
| **[gpt-5.6-luna](/docs/models/gpt-5.6-luna)** | \$1.00 (\<= 272k tokens)
\$2.00 (> 272k tokens) | \$0.10 (\<= 272k tokens)
\$0.20 (> 272k tokens) | \$6.00 (\<= 272k tokens)
\$9.00 (> 272k tokens) |
| **[claude-sonnet-5](/docs/models/claude-sonnet-5)** | \$2.00 | \$0.20 | \$10.00 |
| **[claude-opus-4.8](/docs/models/claude-opus-4-8)** | \$5.00 | \$0.50 | \$25.00 |
| **[glm-5.2](/docs/models/glm-5.2)** | \$1.20 | \$0.30 | \$4.20 |
| **[minimax-m3](/docs/models/minimax-m3)** | \$0.32 (\<= 512k tokens)
\$0.67 (> 512k tokens) | \$0.07 (\<= 512k tokens)
\$0.13 (> 512k tokens) | \$1.28 (\<= 512k tokens)
\$2.55 (> 512k tokens) |
| **[gemini-3.5-flash](/docs/models/gemini-3.5-flash)** | \$1.50 | \$0.15 | \$9.00 |
| **[kimi-k2.6](/docs/models/kimi-k2.6)** | \$1.00 | \$0.20 | \$4.10 |
| **[glm-5.1](/docs/models/glm-5.1)** | \$0.91 (\<= 32k tokens)
\$1.22 (> 32k tokens) | \$0.20 (\<= 32k tokens)
\$0.31 (> 32k tokens) | \$3.64 (\<= 32k tokens)
\$4.25 (> 32k tokens) |
| **[minimax-m2.7](/docs/models/minimax-m2.7)** | \$0.32 | \$0.07 | \$1.28 |
| **[deepseek-v4-pro](/docs/models/deepseek-v4-pro)** | \$1.80 | \$0.30 | \$3.50 |
| **[gpt-5.5](/docs/models/gpt-5.5)** | \$5.00 (\<= 272k tokens)
\$10.00 (> 272k tokens) | \$0.50 (\<= 272k tokens)
\$1.00 (> 272k tokens) | \$30.00 (\<= 272k tokens)
\$45.00 (> 272k tokens) |
| **[gpt-5.4](/docs/models/gpt-5.4)** | \$2.50 (\<= 272k tokens)
\$5.00 (> 272k tokens) | \$0.25 (\<= 272k tokens)
\$0.50 (> 272k tokens) | \$15.00 (\<= 272k tokens)
\$22.50 (> 272k tokens) |
| **[gpt-5.4-mini](/docs/models/gpt-5.4-mini)** | \$0.75 | \$0.075 | \$4.50 |
| **[gpt-5.4-nano](/docs/models/gpt-5.4-nano)** | \$0.20 | \$0.02 | \$1.25 |
| **[gemini-3.1-flash-lite-preview](/docs/models/gemini-3.1-flash-lite-preview)** | \$0.25 | \$0.025 | \$1.50 |
| **[gemini-3.1-pro-preview](/docs/models/gemini-3.1-pro-preview)** | \$2.00 (\<= 200k tokens)
\$4.00 (> 200k tokens) | \$0.20 (\<= 200k tokens)
\$0.40 (> 200k tokens) | \$12.00 (\<= 200k tokens)
\$18.00 (> 200k tokens) |
| **[claude-opus-4.7](/docs/models/claude-opus-4-7)** | \$5.00 | \$0.50 | \$25.00 |
| **[claude-opus-4.6](/docs/models/claude-opus-4-6)** | \$5.00 | \$0.50 | \$25.00 |
| **[claude-sonnet-4.6](/docs/models/claude-sonnet-4-6)** | \$3.00 | \$0.30 | \$15.00 |
| **[claude-haiku-4.5](/docs/models/claude-haiku-4-5)** | \$1.00 | \$0.10 | \$5.00 |
| **[gpt-5.3-codex](/docs/models/gpt-5.3-codex)** | \$1.75 | \$0.18 | \$14.00 |
| **[gpt-5.2-codex](/docs/models/gpt-5.2-codex)** | \$1.75 | \$0.18 | \$14.00 |
| **[gpt-5.1-codex-max](/docs/models/gpt-5.1-codex-max)** | \$1.25 | \$0.13 | \$10.00 |
| **[gpt-5.1-codex](/docs/models/gpt-5.1-codex)** | \$1.25 | \$0.13 | \$10.00 |
| **[gpt-5.2](/docs/models/gpt-5.2)** | \$1.75 | \$0.18 | \$14.00 |
| **[gpt-5.1](/docs/models/gpt-5.1)** | \$1.25 | \$0.125 | \$10.00 |
| **[gpt-5](/docs/models/gpt-5)** | \$1.25 | \$0.125 | \$10.00 |
| **[gpt-5-mini](/docs/models/gpt-5-mini)** | \$0.25 | \$0.03 | \$2.00 |
| **[gpt-5.1](/docs/models/gpt-5.1)** | \$1.25 | \$0.125 | \$10.00 |
| **[gemini-3-pro-preview](/docs/models/gemini-3-pro-preview)** | \$2.00 | \$0.40 | \$12.00 |
| **[gemini-3-flash-preview](/docs/models/gemini-3-flash-preview)** | \$0.50 | \$0.05 | \$3.00 |
| **[gemini-2.5-pro](/docs/models/gemini-2.5-pro)** | \$1.25 (\<= 200k tokens)
\$2.50 (> 200k tokens) | \$0.125 (\<= 200k tokens)
\$0.25 (> 200k tokens) | \$10.00 (\<= 200k tokens)
\$15.00 (> 200k tokens) |
| **[gemini-2.5-flash](/docs/models/gemini-2.5-flash)** | \$0.30 | \$0.03 | \$2.50 |
| **[deepseek-v3.2](/docs/models/deepseek-v3.2)** | \$0.30 | \$0.06 | \$0.45 |
| **kimi-k2.5** | \$1.25 | \$0.125 | \$10.00 |
| **glm-5** | \$1.00 | \$0.10 | \$3.20 |
| **[gpt-4.1](/docs/models/gpt-4.1)** | \$2.00 | \$0.50 | \$8.00 |
| **[gpt-4o](/docs/models/gpt-4o)** | \$2.50 | \$1.25 | \$10.00 |
| **[deepseek-r1](/docs/models/deepseek-r1-0528)** | \$1.35 | - | \$5.40 |
| **[deepseek-v3.1](/docs/models/deepseek-v3.1)** | \$1.14 | - | \$4.56 |
## Capabilities
| Model | Context Window | Max Output Tokens | Tool Call |
| --------------------- | -------------- | ----------------- | --------- |
| **[gpt-6-astra](/docs/models/gpt-6-astra)** | 1,050,000 | 128,000 | Yes |
| **[claude-fable-5-1](/docs/models/claude-fable-5-1)** | 1,000,000 | 128,000 | Yes |
| **[gemini-3.8-flash](/docs/models/gemini-3.8-flash)** | 1,000,000 | 128,000 | Yes |
| **[claude-fable-5](/docs/models/claude-fable-5)** | 1,000,000 | 128,000 | Yes |
| **[glm-5.3-flash](/docs/models/glm-5.3-flash)** | 1,000,000 | 384,000 | Yes |
| **[deepseek-v4-pro-0813](/docs/models/deepseek-v4-pro-0813)** | 1,000,000 | 384,000 | Yes |
| **[deepseek-v4-flash-vision-exp](/docs/models/deepseek-v4-flash-vision-exp)** | 1,000,000 | 384,000 | Yes |
| **[deepseek-v4-flash (0731)](/docs/models/deepseek-v4-flash)** | 1,000,000 | 384,000 | Yes |
| **[gemini-3.7-flash](/docs/models/gemini-3.7-flash)** | 1,000,000 | 64,000 | Yes |
| **[glm-5.3](/docs/models/glm-5.3)** | 1,000,000 | 128,000 | Yes |
| **[gemini-3.6-flash](/docs/models/gemini-3.6-flash)** | 1,000,000 | 64,000 | Yes |
| **[gemini-3-pro-image](/docs/models/gemini-3-pro-image)** | 65,536 | 32,768 | No |
| **[gemini-3.1-flash-image](/docs/models/gemini-3.1-flash-image)** | 131,072 | 32,768 | No |
| **[claude-opus-5](/docs/models/claude-opus-5)** | 1,000,000 | 128,000 | Yes |
| **[kimi-k3](/docs/models/kimi-k3)** | 1,000,000 | 128,000 | Yes |
| **[gpt-5.6-sol](/docs/models/gpt-5.6-sol)** | 1,050,000 | 128,000 | Yes |
| **[gpt-5.6-terra](/docs/models/gpt-5.6-terra)** | 1,050,000 | 128,000 | Yes |
| **[gpt-5.6-luna](/docs/models/gpt-5.6-luna)** | 1,050,000 | 128,000 | Yes |
| **[claude-sonnet-5](/docs/models/claude-sonnet-5)** | 1,000,000 | 128,000 | Yes |
| **[claude-opus-4.8](/docs/models/claude-opus-4-8)** | 1,000,000 | 128,000 | Yes |
| **[glm-5.2](/docs/models/glm-5.2)** | 1,000,000 | 128,000 | Yes |
| **[minimax-m3](/docs/models/minimax-m3)** | 512,000 | 128,000 | Yes |
| **[gemini-3.5-flash](/docs/models/gemini-3.5-flash)** | 1,000,000 | 65,536 | Yes |
| **[kimi-k2.6](/docs/models/kimi-k2.6)** | 256,000 | 256,000 | Yes |
| **[glm-5.1](/docs/models/glm-5.1)** | 200,000 | 128,000 | Yes |
| **[minimax-m2.7](/docs/models/minimax-m2.7)** | 204,800 | 131,072 | Yes |
| **[deepseek-v4-pro](/docs/models/deepseek-v4-pro)** | 1,000,000 | 384,000 | Yes |
| **[gpt-5.5](/docs/models/gpt-5.5)** | 1,050,000 | 128,000 | Yes |
| **[gpt-5.4](/docs/models/gpt-5.4)** | 1,050,000 | 128,000 | Yes |
| **[gpt-5.4-mini](/docs/models/gpt-5.4-mini)** | 400,000 | 128,000 | Yes |
| **[gpt-5.4-nano](/docs/models/gpt-5.4-nano)** | 400,000 | 128,000 | Yes |
| **[gemini-3.1-flash-lite-preview](/docs/models/gemini-3.1-flash-lite-preview)** | 1,048,576 | 65,536 | Yes |
| **[gemini-3.1-pro-preview](/docs/models/gemini-3.1-pro-preview)** | 1,048,576 | 65,536 | Yes |
| **[claude-opus-4.7](/docs/models/claude-opus-4-7)** | 1,000,000 | 128,000 | Yes |
| **[claude-opus-4.6](/docs/models/claude-opus-4-6)** | 200,000 | 128,000 | Yes |
| **[claude-sonnet-4.6](/docs/models/claude-sonnet-4-6)** | 200,000 | 128,000 | Yes |
| **[gpt-5.3-codex](/docs/models/gpt-5.3-codex)** | 400,000 | 128,000 | Yes |
| **[gpt-5.2-codex](/docs/models/gpt-5.2-codex)** | 400,000 | 128,000 | Yes |
| **[gpt-5.1-codex-max](/docs/models/gpt-5.1-codex-max)** | 400,000 | 128,000 | Yes |
| **[gpt-5.1-codex](/docs/models/gpt-5.1-codex)** | 400,000 | 128,000 | Yes |
| **[gpt-5.2](/docs/models/gpt-5.2)** | 400,000 | 128,000 | Yes |
| **[gpt-5.1](/docs/models/gpt-5.1)** | 400,000 | 128,000 | Yes |
| **[gpt-5](/docs/models/gpt-5)** | 400,000 | 128,000 | Yes |
| **[gpt-5-mini](/docs/models/gpt-5-mini)** | 272,000 | 128,000 | Yes |
| **[deepseek-v3.2](/docs/models/deepseek-v3.2)** | 128,000 | 128,000 | Yes |
| **[gemini-3-pro-preview](/docs/models/gemini-3-pro-preview)** | 1,000,000 | 64,000 | Yes |
| **[gemini-3-flash-preview](/docs/models/gemini-3-flash-preview)** | 1,000,000 | 64,000 | Yes |
## Service Regions & Geo-Distributed Acceleration
Vivgrid intelligently accelerates model inference by **automatically routing API requests to the nearest available compute region**, minimizing latency and maximizing throughput — all while maintaining **data-residency compliance** for enterprise workloads.
Unlike conventional _Global_ deployments on public clouds (which rely on single centralized endpoints), **Vivgrid’s geo-distributed architecture** continuously synchronizes [**AI Skills**](/docs/managed-skills) and model states across multiple data zones, ensuring each region delivers **optimized, low-latency performance**.
| Model | Acceleration Mode | Accelerated Regions |
| :------------- | :---------------- | :------------------ |
| **[gpt-6-astra](/docs/models/gpt-6-astra)** | ⚡ Geo-Distributed | Accelerated in **AMER**, **EMEA**, **APAC** |
| **[claude-fable-5-1](/docs/models/claude-fable-5-1)** | ⚡ Geo-Distributed | Accelerated in **AMER**, **EMEA**, **APAC** |
| **[gemini-3.8-flash](/docs/models/gemini-3.8-flash)** | 🌐 Global (Centralized) | — |
| **[claude-fable-5](/docs/models/claude-fable-5)** | ⚡ Geo-Distributed | Accelerated in **AMER**, **EMEA**, **APAC** |
| **[glm-5.3-flash](/docs/models/glm-5.3-flash)** | 🌐 Global (Centralized) | Accelerated in **APAC** |
| **[deepseek-v4-pro-0813](/docs/models/deepseek-v4-pro-0813)** | 🌐 Global (Centralized) | Accelerated in **APAC** |
| **[deepseek-v4-flash-vision-exp](/docs/models/deepseek-v4-flash-vision-exp)** | 🌐 Global (Centralized) | Accelerated in **APAC** |
| **[deepseek-v4-flash (0731)](/docs/models/deepseek-v4-flash)** | 🌐 Global (Centralized) | Accelerated in **APAC** |
| **[gemini-3.7-flash](/docs/models/gemini-3.7-flash)** | 🌐 Global (Centralized) | — |
| **[glm-5.3](/docs/models/glm-5.3)** | 🌐 Global (Centralized) | Accelerated in **APAC** |
| **[gemini-3.6-flash](/docs/models/gemini-3.6-flash)** | 🌐 Global (Centralized) | — |
| **[gemini-3-pro-image](/docs/models/gemini-3-pro-image)** | 🌐 Global (Centralized) | — |
| **[gemini-3.1-flash-image](/docs/models/gemini-3.1-flash-image)** | 🌐 Global (Centralized) | — |
| **[claude-opus-5](/docs/models/claude-opus-5)** | ⚡ Geo-Distributed | Accelerated in **AMER**, **EMEA**, **APAC** |
| **[kimi-k3](/docs/models/kimi-k3)** | 🌐 Global (Centralized) | Accelerated in **APAC** |
| **[gpt-5.6-sol](/docs/models/gpt-5.6-sol)** | ⚡ Geo-Distributed | Accelerated in **AMER**, **EMEA** |
| **[gpt-5.6-terra](/docs/models/gpt-5.6-terra)** | ⚡ Geo-Distributed | Accelerated in **AMER**, **EMEA** |
| **[gpt-5.6-luna](/docs/models/gpt-5.6-luna)** | ⚡ Geo-Distributed | Accelerated in **AMER**, **EMEA** |
| **[claude-sonnet-5](/docs/models/claude-sonnet-5)** | ⚡ Geo-Distributed | Accelerated in **AMER**, **EMEA**, **APAC** |
| **[claude-opus-4.8](/docs/models/claude-opus-4-8)** | ⚡ Geo-Distributed | Accelerated in **AMER**, **EMEA**, **APAC** |
| **[glm-5.2](/docs/models/glm-5.2)** | 🌐 Global (Centralized) | Accelerated in **APAC** |
| **[minimax-m3](/docs/models/minimax-m3)** | 🌐 Global (Centralized) | Accelerated in **APAC** |
| **[gemini-3.5-flash](/docs/models/gemini-3.5-flash)** | 🌐 Global (Centralized) | - |
| **[kimi-k2.6](/docs/models/kimi-k2.6)** | 🌐 Global (Centralized) | Accelerated in **APAC** |
| **[glm-5.1](/docs/models/glm-5.1)** | 🌐 Global (Centralized) | Accelerated in **APAC** |
| **[minimax-m2.7](/docs/models/minimax-m2.7)** | 🌐 Global (Centralized) | Accelerated in **APAC** |
| **[deepseek-v4-pro](/docs/models/deepseek-v4-pro)** | 🌐 Global (Centralized) | Accelerated in **APAC** |
| **[gpt-5.5](/docs/models/gpt-5.5)** | ⚡ Geo-Distributed | Accelerated in **AMER**, **EMEA** |
| **[gpt-5.4](/docs/models/gpt-5.4)** | ⚡ Geo-Distributed | Accelerated in **AMER**, **EMEA**, **APAC** |
| **[gpt-5.4-mini](/docs/models/gpt-5.4-mini)** | ⚡ Geo-Distributed | Accelerated in **AMER**, **EMEA**, **APAC** |
| **[gpt-5.4-nano](/docs/models/gpt-5.4-nano)** | ⚡ Geo-Distributed | Accelerated in **AMER**, **EMEA** |
| **[gemini-3.1-flash-lite-preview](/docs/models/gemini-3.1-flash-lite-preview)** | 🌐 Global (Centralized) | - |
| **[gemini-3.1-pro-preview](/docs/models/gemini-3.1-pro-preview)** | 🌐 Global (Centralized) | — |
| **[claude-opus-4.7](/docs/models/claude-opus-4-7)** | ⚡ Geo-Distributed | Accelerated in **AMER**, **EMEA**, **APAC** |
| **[claude-opus-4.6](/docs/models/claude-opus-4-6)** | ⚡ Geo-Distributed | Accelerated in **AMER**, **EMEA** |
| **[claude-sonnet-4.6](/docs/models/claude-sonnet-4-6)** | ⚡ Geo-Distributed | Accelerated in **AMER**, **EMEA** |
| **claude-opus-4.5** | ⚡ Geo-Distributed | Accelerated in **AMER**, **EMEA** |
| **[gpt-5.3-codex](/docs/models/gpt-5.3-codex)** | ⚡ Geo-Distributed | Accelerated in **AMER**, **EMEA** |
| **[gpt-5.2-codex](/docs/models/gpt-5.2-codex)** | ⚡ Geo-Distributed | Accelerated in **AMER**, **EMEA** |
| **[gpt-5.1-codex-max](/docs/models/gpt-5.1-codex-max)** | ⚡ Geo-Distributed | Accelerated in **AMER**, **EMEA** |
| **[gpt-5.1-codex](/docs/models/gpt-5.1-codex)** | ⚡ Geo-Distributed | Accelerated in **AMER**, **EMEA**, **APAC** |
| **[gpt-5.2](/docs/models/gpt-5.2)** | ⚡ Geo-Distributed | Accelerated in **AMER**, **EMEA** |
| **[gpt-5.1](/docs/models/gpt-5.1)** | ⚡ Geo-Distributed | Accelerated in **AMER**, **EMEA** |
| **[gpt-5](/docs/models/gpt-5)** | ⚡ Geo-Distributed | Accelerated in **AMER**, **EMEA**, **APAC** |
| **[gpt-5-mini](/docs/models/gpt-5-mini)** | ⚡ Geo-Distributed | Accelerated in **AMER**, **EMEA**, **APAC** |
| **[gemini-2.5-pro](/docs/models/gemini-2.5-pro)** | 🌐 Global (Centralized) | — |
| **[gemini-2.5-flash](/docs/models/gemini-2.5-flash)** | 🌐 Global (Centralized) | — |
### Key Highlights
- **Dynamic Routing** — Vivgrid automatically detects the user’s region and routes requests to the **nearest accelerated node**, minimizing cross-continent latency.
- **Tool Synchronization** — AI tools and context caches are replicated across all accelerated regions for consistent behavior.
- **Adaptive Caching** — Frequently accessed prompts and embeddings are regionally cached to reduce cold-start delays.
- **Seamless Fallback** — Traffic automatically re-routes to neighboring accelerated zones during high load or outages.
### Notes on Global Models
For **Global-only** models (e.g., `gemini-3.1-pro-preview`), the model host remains centralized under the provider’s _Global Standard endpoint_, limiting VivGrid’s ability to perform regional acceleration.\
In contrast, **Geo-Distributed** models (e.g., `gpt-5.6-sol`,`claude-opus-5`) leverage Vivgrid’s orchestration layer — delivering **sub-50 ms latency worldwide** through intelligent regional acceleration.
---
# Observability & Insights
> Source: https://vivgrid.com/docs/observability
Vivgrid's observability features provide deep insights into AI agent performance, enabling developers to monitor, analyze, and optimize their agents effectively.
## Access Logs in Realtime
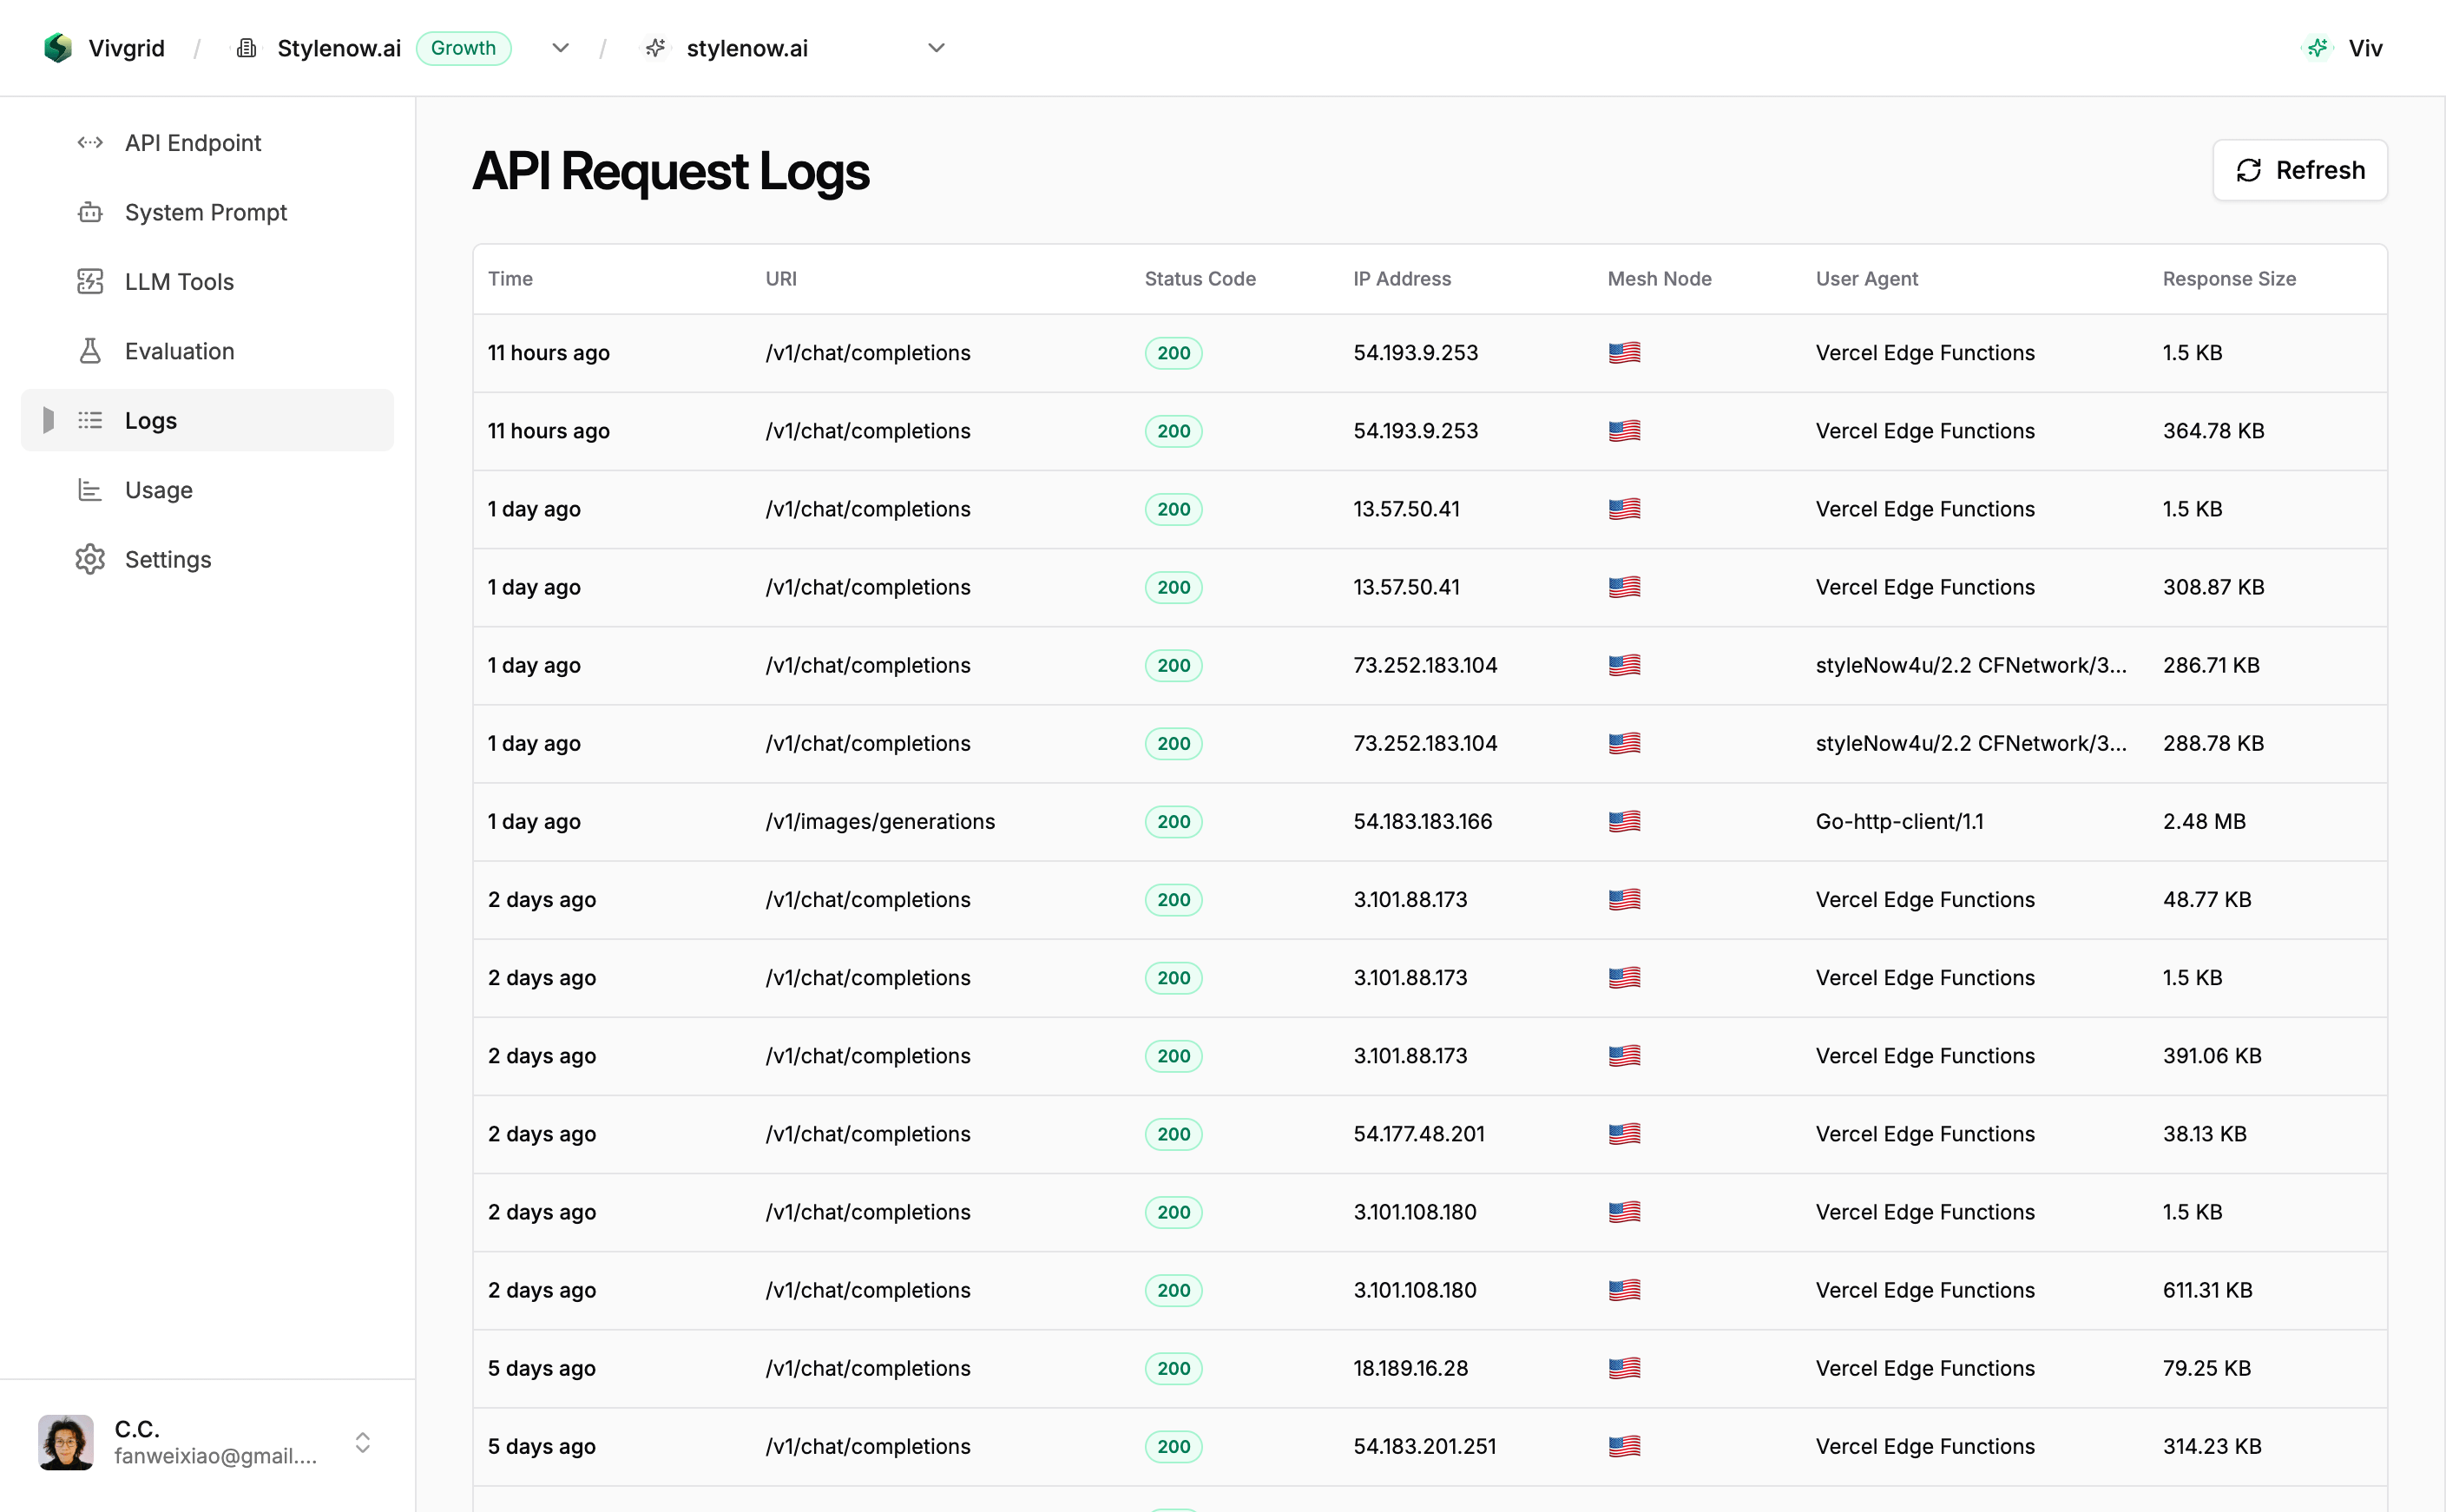
## Latency Breakdown
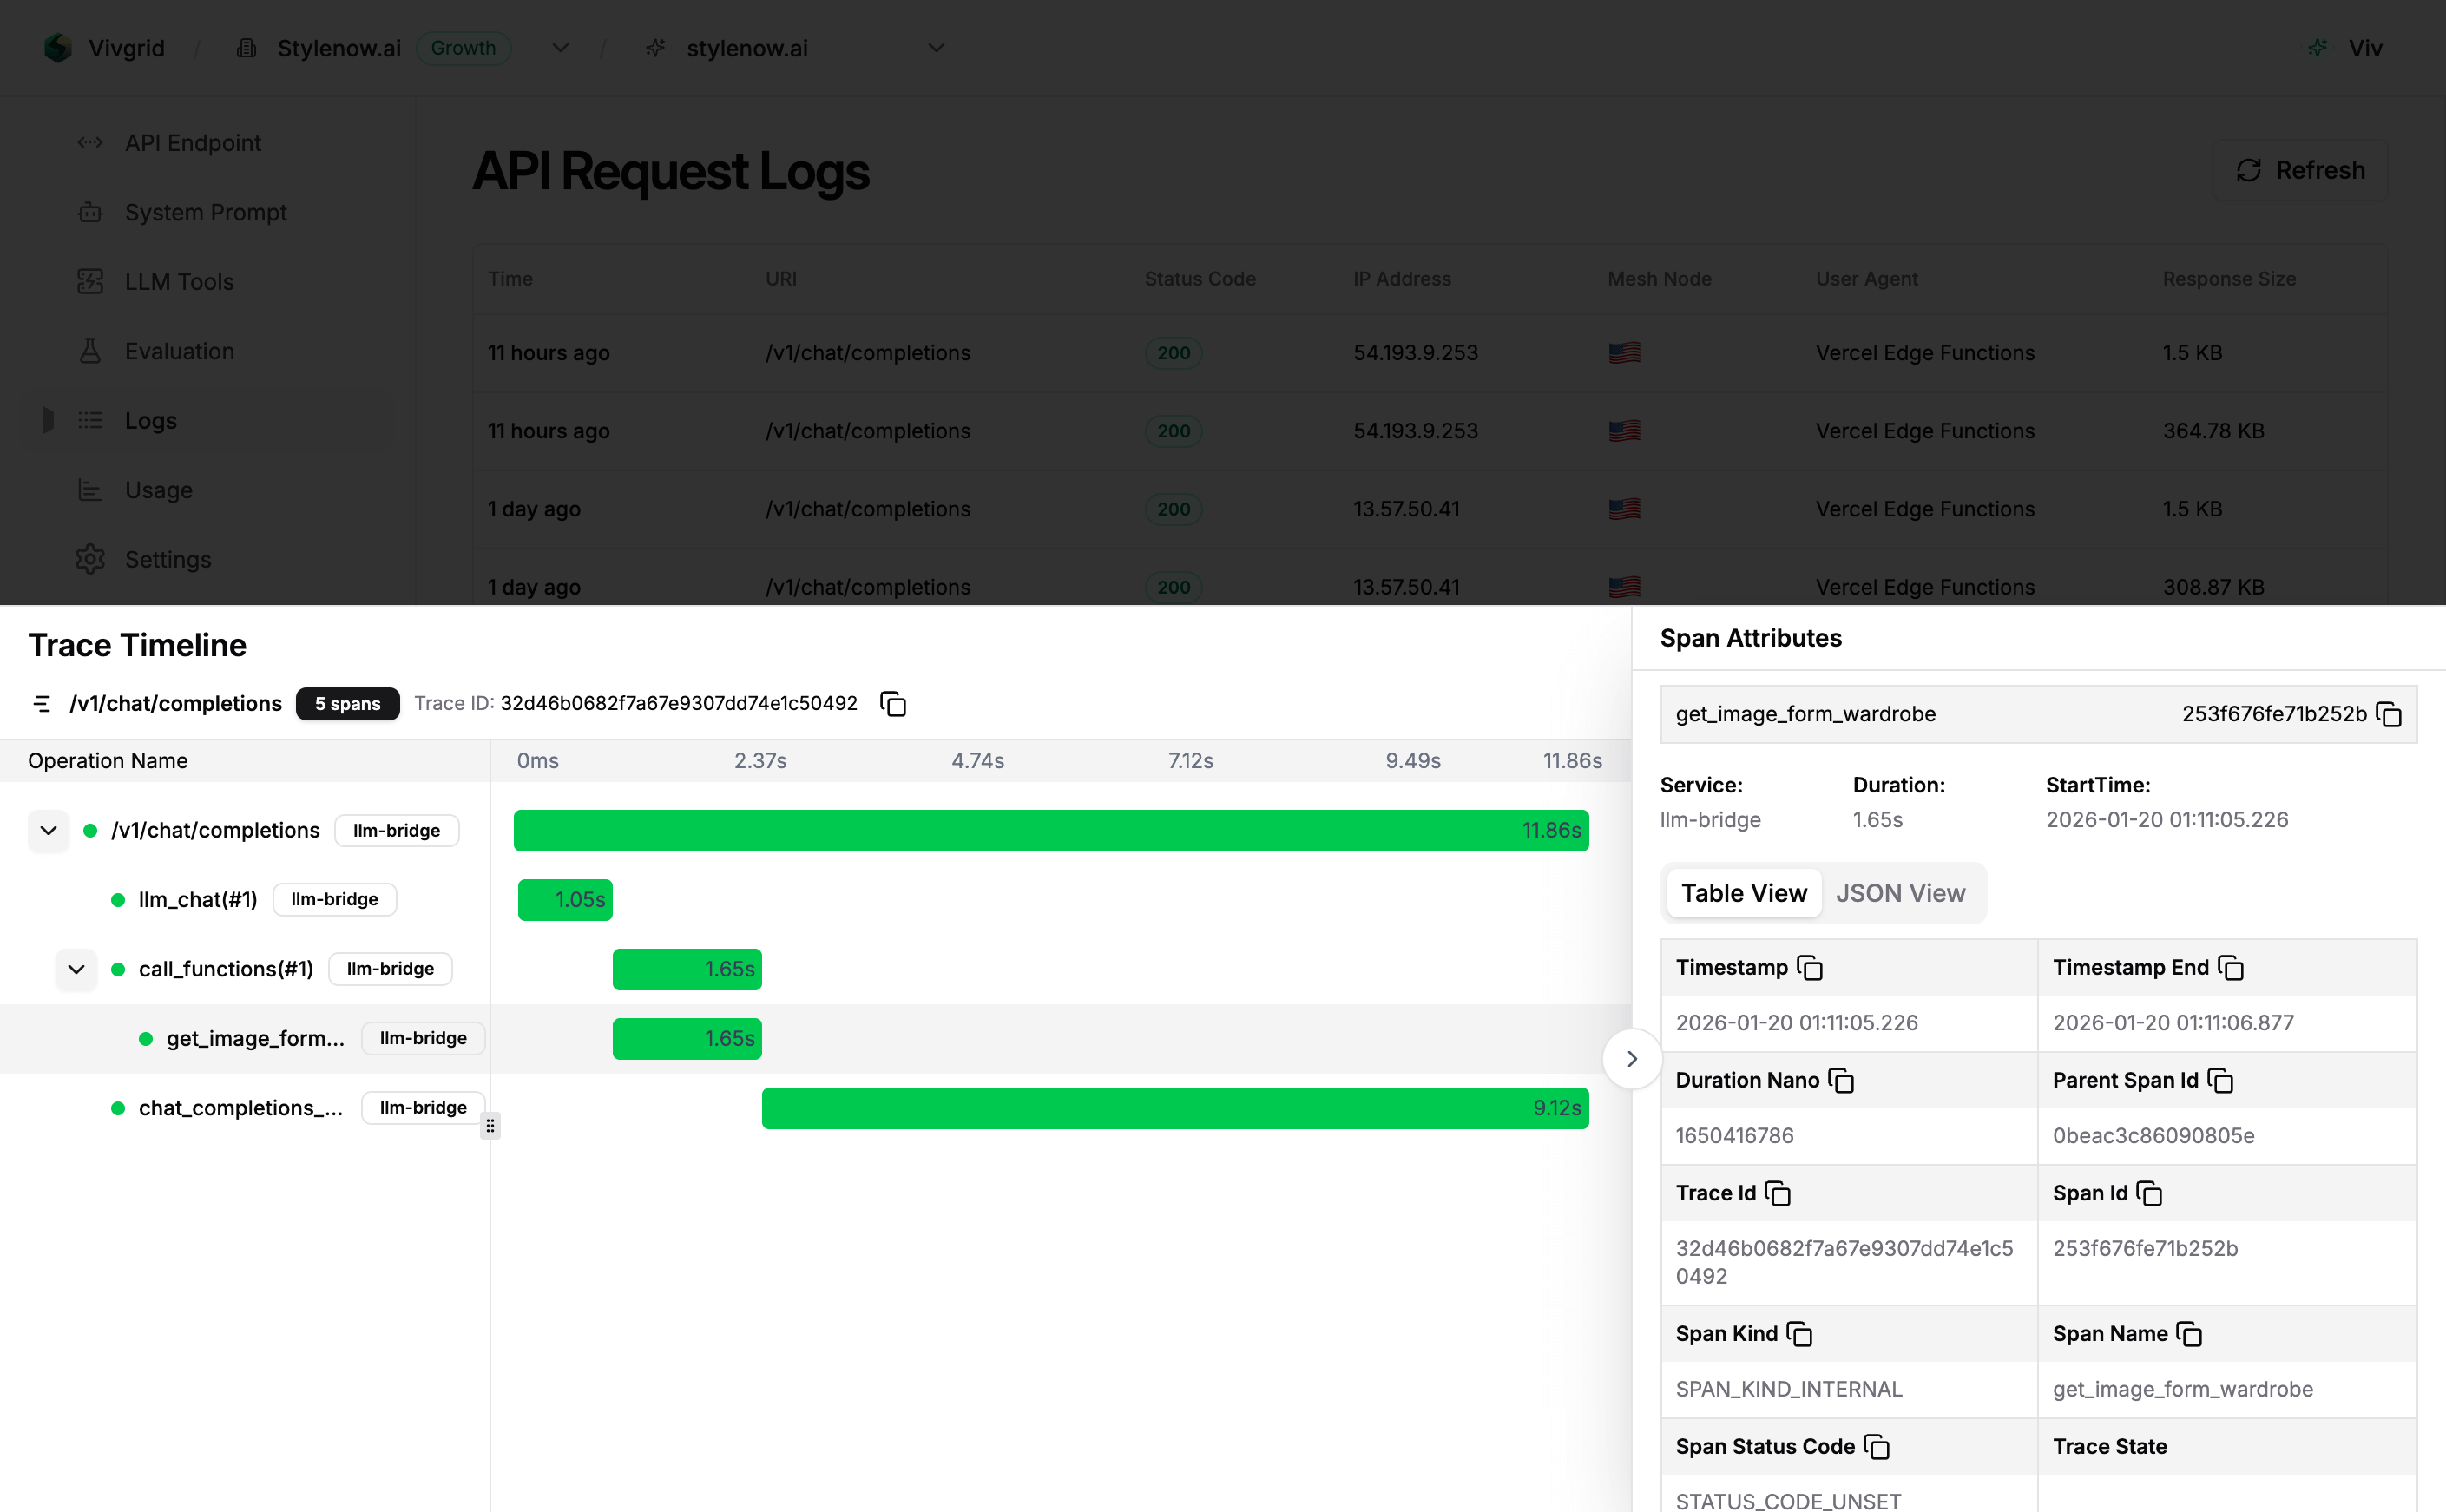
---
# Quick Start
> Source: https://vivgrid.com/docs/quick-start
Go from your first API request to a custom AI skill running on Vivgrid's global network — in minutes.
In this guide you'll make your first request to the Vivgrid Model API, then
extend your agent with a custom [Managed Skill](/docs/managed-skills) (LLM
Function Calling) and deploy it worldwide.
### Get your API key
Log in to the [Vivgrid Console](https://console.vivgrid.com) and create a new `Project`. You'll receive:
- An **API key** for calling the Model API.
- An `APP_KEY` and `APP_SECRET` for building and deploying skills.
Keep them safe — you'll need them in the steps below.
```bash
export VIVGRID_API_KEY=""
```
### Make your first request
Vivgrid speaks the OpenAI API. Point any OpenAI-compatible client at `https://api.vivgrid.com/v1` and you're done. Let's ask a question that a plain LLM can't answer on its own:
```bash
curl https://api.vivgrid.com/v1/chat/completions \
-H "Content-Type: application/json" \
-H "Authorization: Bearer $VIVGRID_API_KEY" \
-d '{
"messages": [
{ "role": "user", "content": "Compare amazon and shopify network performance" }
]
}'
```
The model replies that it has no real-time network access and can't measure latency — it simply doesn't have the data:
```json
{
"choices": [
{
"message": {
"role": "assistant",
"content": "I don't have the ability to measure live network latency for amazon.com or shopify.com..."
}
}
]
}
```
You don't pass a `model` field — the model for your agent is configured in the
Console and managed on the backend, so you can switch models without touching
your code. See [Models](/docs/models) for the full list, or wire Vivgrid into
[Codex](/docs/tutorials/codex), [Claude Code](/docs/tutorials/claude-code),
and other tools.
We'll fix the missing capability by giving the agent a **skill**.
### Extend your agent with a skill in Node.js
Skills are LLM Function Calling tools that Vivgrid hosts and orchestrates for you. Install the [Yomo Framework](https://yomo.run):
```bash
curl -fsSL https://get.yomo.run | sh
```
Initialize a new Node.js skill project:
```bash
yomo init -l node ./llm-tool
```
A skill is a Node.js project with three exports in `src/app.ts`: a `description`, an `Argument` type, and a `handler`. Let's build them up.
First, a function that measures network performance for a given domain:
```ts src/app.ts
import { promises as dns } from 'node:dns'
import ping from 'ping'
async function measure(domain: string) {
// get all ip addresses
const ips = await dns.resolve4(domain)
// get the first ip address and measure latency by ping
const res = await ping.promise.probe(ips[0], { timeout: 3, min_reply: 3 })
// log the result
console.log('[sfn] get ping latency', 'domain:', domain, 'ip:', ips[0], 'latency:', `${res.avg}ms`, 'PacketLoss:', `${res.packetLoss}%`)
// return result to the LLM
return `domain ${domain} has ip ${ips[0]} with average latency ${res.avg}ms, make sure answer with the IP address and Latency`
}
```
Next, wrap it to meet the Function Calling spec. Export a `description` so the model knows when to call your skill — this is critical for accuracy:
```ts src/app.ts
export const description = `if user asks ip or network latency of a domain,
you should return the result of the given domain.
try your best to dissect user expressions to infer the right domain names`
```
`measure()` needs a domain name. The model infers it from the user input and passes it through `Arguments` in the tool call. Export an `Argument` type to describe it:
```ts src/app.ts
// Argument defines the arguments data type for the tool call
export type Argument = {
// Domain of the website, e.g. example.com
domain: string
}
```
Finally, export a `handler` to turn it into a skill:
```ts src/app.ts
/**
* handler will be triggered when the LLM tool call occurs.
* @param args - LLM Function Calling Arguments.
* @returns The result is returned to the LLM for the next round of chat completions.
*/
export async function handler(args: Argument) {
// parse the arguments from the tool call
console.log('triggered', 'domain:', args.domain)
// execute linux ping command to get result
return await measure(args.domain)
}
```
Browse more ready-to-run examples here: https://github.com/yomorun/llm-function-calling-examples
### Run it locally
For testing, or to host on your own infrastructure, install dependencies and run the skill, connecting it to Vivgrid with your `APP_KEY`:
```bash
yomo run \
--name ai_skill_get_ip_lantency \
--zipper zipper.vivgrid.com:9000 \
--credential
ℹ️ Yomo Stream Function file: /Users/fanweixiao/_wrk/llm-tool/sfn.yomo
⌛ Create Yomo Stream Function instance...
ℹ️ Starting Yomo Stream Function instance with zipper: zipper.vivgrid.com:9000
ℹ️ Stream Function is running...
ℹ️ Run: /Users/fanweixiao/_wrk/llm-tool/sfn.yomo
time=2026-05-06T22:50:44.883+07:00 level=INFO msg="connected to zipper" component=StreamFunction sfn_id= sfn_name=ai_skill_get_ip_lantency zipper_addr=zipper.vivgrid.com:9000
```
Now send the same request from Step 2 again — your agent calls the skill and answers with real latency numbers.
### Deploy to Vivgrid's global network
Next, deploy the skill to the Vivgrid Geo-distributed Network so it runs in multiple regions, with requests routed to the nearest one automatically.
Create a `vivgrid.yml` file:
```yaml vivgrid.yml
secret:
tool: ai_skill_get_ip_lantency
```
Then run:
```bash
viv deploy .
```
**Important** Make sure you have the `viv` CLI installed. If not, [install it
here](/docs/viv).
Once deployed, monitor real-time logs and ask "Compare amazon and shopify network performance" again:
```bash
$ viv logs
[sgp.1] OK: {"log":"INFO triggered domain=amazon.com"}
[sgp.1] OK: {"log":"INFO triggered domain=shopify.com"}
[sgp.1] OK: {"log":"INFO [sfn] get ip domain=amazon.com ip=205.251.242.103"}
[sgp.1] OK: {"log":"INFO [sfn] get ip domain=amazon.com ip=54.239.28.85"}
[sgp.1] OK: {"log":"INFO [sfn] start ping domain=amazon.com ip=205.251.242.103"}
[sgp.1] OK: {"log":"INFO [sfn] get ip domain=amazon.com ip=52.94.236.248"}
[sgp.1] OK: {"log":"INFO [sfn] get ip domain=shopify.com ip=23.227.38.33"}
[sgp.1] OK: {"log":"INFO [sfn] start ping domain=shopify.com ip=23.227.38.33"}
[sgp.1] OK: {"log":"INFO [sfn] get ping latency domain=shopify.com ip=23.227.38.33 latency=2.182382ms PacketLoss=0.000000%"}
[sgp.1] OK: {"log":"INFO [sfn] get ping latency domain=amazon.com ip=205.251.242.103 latency=232.835894ms PacketLoss=0.000000%"}
```
Your agent now answers the question with a real network performance comparison.
**Did you know?** Your skill is deployed to multiple regions automatically,
bringing computing closer to your users — lowering latency and improving the
experience. Free Plan users get 7 regions.
---
# Vivgrid Open Source & Startup Sponsorship
> Source: https://vivgrid.com/docs/sponsorship
Build, test, and scale with Vivgrid’s platform plus sponsored access to gpt-5, gemini-3, and DeepSeek-v3.
At **Vivgrid**, we’re building a **dynamic development platform for AI agent creators** — a place where developers can **prototype faster, scale with confidence, and unlock new forms of collaboration between agents.**
To support the next wave of startups shaping the future of AI, we’re thrilled to launch the **Vivgrid Startup Sponsorship**.
## 🎁 What Startups Receive
Every selected startup gets access to **exclusive benefits for 12 months**:
- ✅ **Free Team Account** for up to 12 months (unlocks full collaboration features)
- ✅ **\$200 in free credits every month — \$2,400 total for the year**
- ✅ Priority access to Vivgrid’s product roadmap, updates, and community events
## 💡 Why Vivgrid?
Vivgrid is designed to empower AI builders at every stage:
- **Build robust multi-agent systems** with ready-to-use tools
- **Seamlessly connect** to the world’s leading LLM APIs ([GPT-5.2](/docs/models#gpt-5.2), [Gemini-3-Pro](/docs/models#gemini-3-pro-preview), [DeepSeek-V3](/docs/models#deepseek-v3), and more)
- **Unify agent development, observability, and evaluation** in one platform
- **Collaborate smarter** and bring ideas to market faster with scalable, production-ready infrastructure
Our mission is simple: **make it easier for developers to build smarter, observe deeper, and evaluate better.**
## 🌱 Who Should Apply?
The program is open to:
- Open source projects focused on AI agents like [LangChain](https://www.langchain.com/), [AutoGPT](https://agpt.co/) and more
- Early-stage startups building with or around AI agents
- Teams exploring **multi-agent systems**, **LLM applications**, or **next-gen AI infrastructure**
- Founders who want to **prototype, validate, and scale faster** without infrastructure headaches
## 📩 How to Apply
1. 1️⃣ **Sign up** for a free Vivgrid account at [vivgrid.com](http://vivgrid.com).
2. 2️⃣ Complete the application form https://forms.gle/2PEDR1K7WdUkYodv8.
3. 3️⃣ Once your application is submitted, we’ll review it and notify you by email with the results.
---
# viv CLI — Deploy AI Skills to Vivgrid
> Source: https://vivgrid.com/docs/viv
Deploy AI skills to Vivgrid's global network with the viv CLI: commands for deploy, upload, create, status, logs, and vivgrid.yml configuration.
`viv` is the command-line interface (CLI) tool for deploying your Managed Skills on Vivgrid.
It provides a convenient way to manage your deployments and skill instances globally.
## Installation
To install `viv`, you can use the following command:
```bash
curl "https://bina.egoist.dev/vivgrid/cli?file=viv&name=viv" | sh
```
## Usage
`viv --help` to see all sub-commands.
General Options:
- `--secret`: The application secret of your Vivgrid project.
- `--tool`: The name of your skill.
- `--api`: The URL of the Vivgrid Zipper Service endpoint, the default value is `https://hosting.vivgrid.com`.
- `--env`: The environment variables for your skill. you can pass multiple `--env` options like `viv deploy . --env OPENWEATHERMAP_API_KEY=token --env GITHUB_API_KEY=token`.
You can create a `vivgrid.yml` file in the root of your project to configure the deployment settings instead of passing the options every time.
### viv deploy [FILE]...
This command will deploy your skill to Vivgrid hosting.
```bash
viv deploy . --env KEY=VALUE
```
### Manage skill deployment
Your skill code will be uploaded to Vivgrid and compiled by `viv upload` command, after that, you can create the deployments by `viv create` command.
#### viv upload
This command will compile your skill after uploading to Vivgrid hosting.
```bash
viv upload .
```
#### viv create
This command will create the deployments.
```bash
viv create
```
#### viv remove
This command will delete the deployments.
```bash
viv remove
```
### Manage skill state
Once the deployment is created, you can manage its state. Requests will be automatically routed to the nearest region through the Vivgrid Geo-distributed Network.
#### viv status
This command will show the status of the deployments.
```bash
viv status
```
#### viv help
This command displays all available sub-commands and their usage.
```bash
viv help
```
### Observability
#### viv logs
This command will show the real-time logs of skill instances across all regions.
```bash
viv logs
```
Terminate the logs by pressing `Ctrl + C`.
## `vivgrid.yml` Configuration File
You can create a `vivgrid.yml` file in the root of your project to configure the deployment settings.
```yaml
zipper: zipper.vivgrid.com:9000
secret:
tool: your_tool_name
```
- `zipper` (optional): The URL of the Vivgrid Zipper Service endpoint, the default value is `zipper.vivgrid.com:9000`.
- `secret`: The application secret of your Vivgrid project.
- `tool`: The name of your skill.
## Set Environment Variables
You can set environment variables for your skill by passing the `--env` option.
```bash
viv deploy . --env KEY1=VALUE1 --env KEY2=VALUE2
```
---
# Autosend
> Source: https://vivgrid.com/docs/marketplace/autosend
Send transactional and automated emails via Autosend on Vivgrid
## Overview
Enable your AI agent to generate and send professional emails to customers using [AutoSend](https://autosend.com). This integration allows you to automate transactional emails, notifications, and customer communications with AI-generated content.
## Use Cases
### Dynamic HTML Email Generation
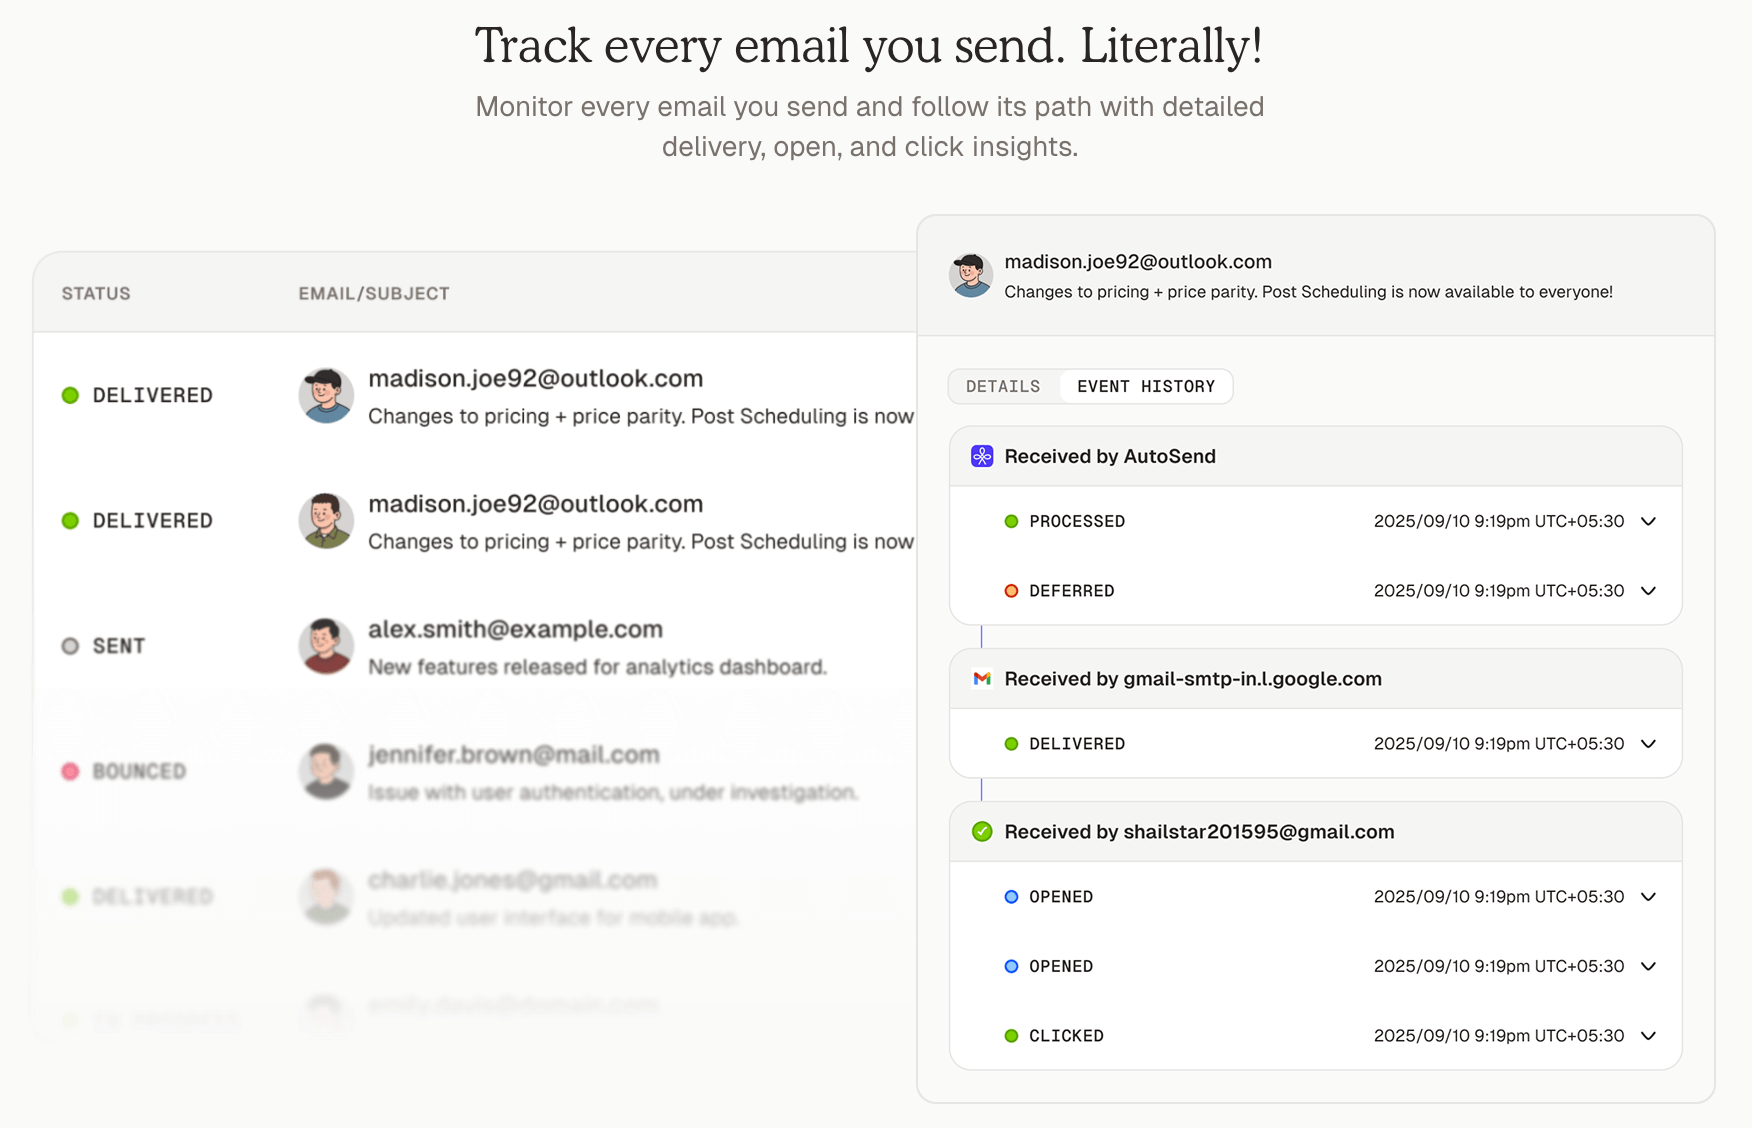
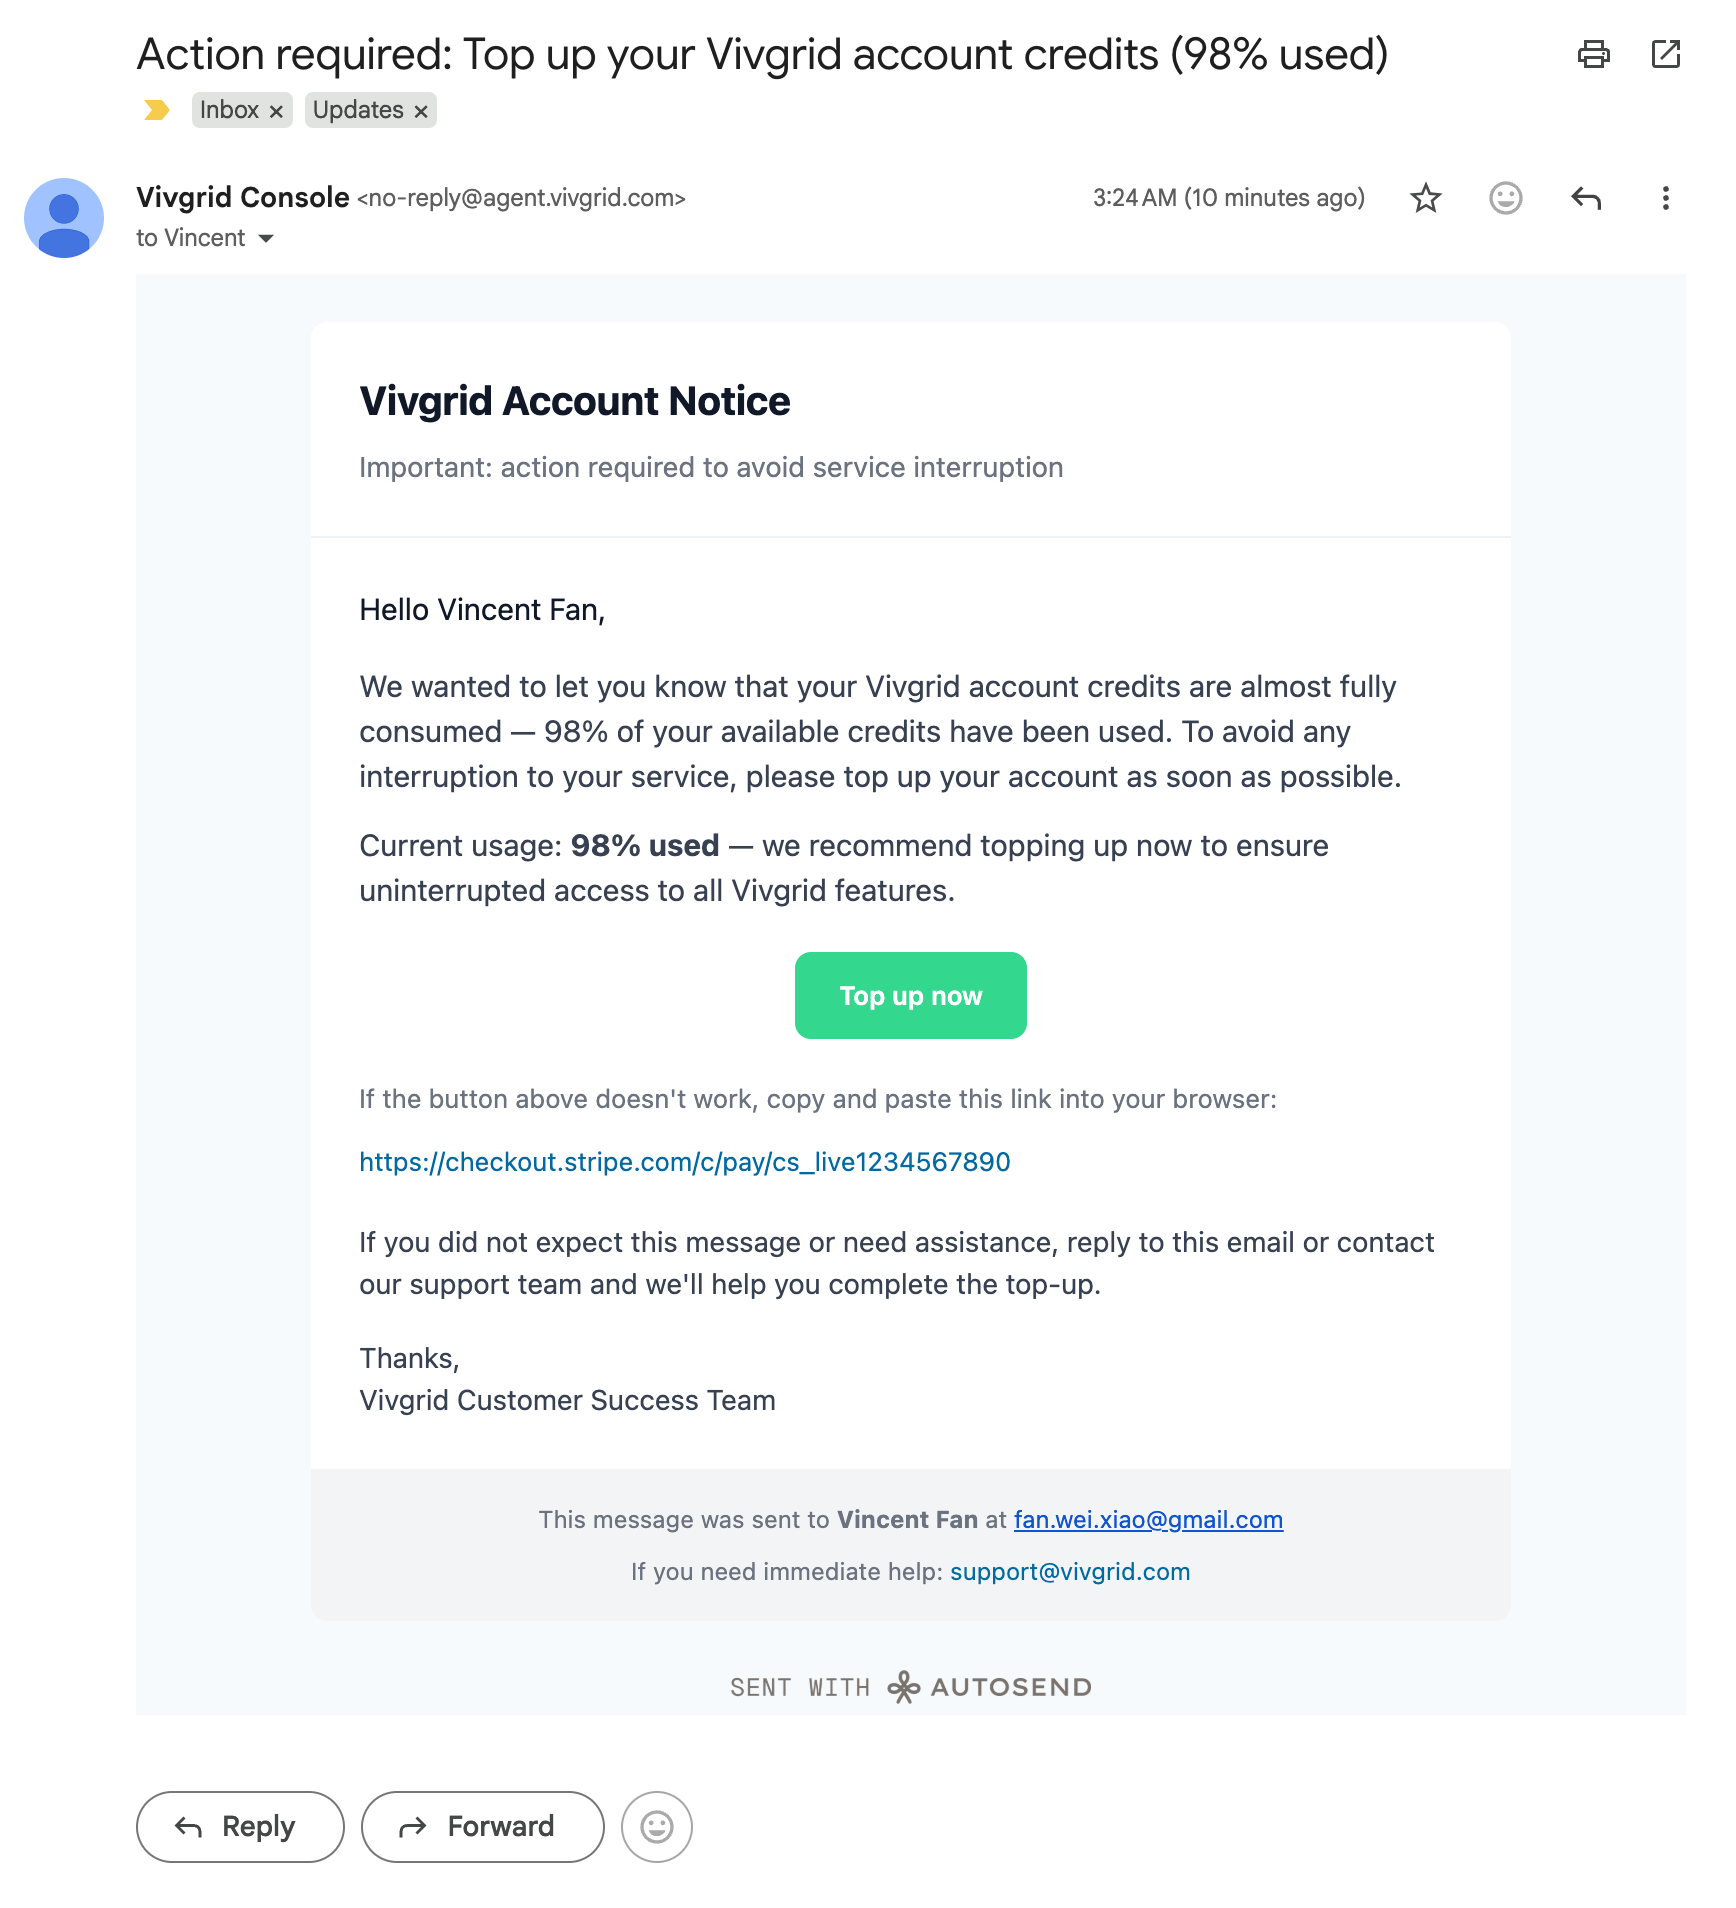
Generate and send custom HTML emails with dynamic content. In this example, we'll send a credit balance notification with a payment link.
```markdown Send html format email wrap
- Write a HTML-formatted email addressed to fan.wei.xiao@gmail.com, referring to the recipient as Vincent Van.
- Inform him that his account credits are nearly depleted (98% used) and he needs to top up promptly to prevent service interruption.
- Include a CTA button that links to: https://checkout.stripe.com/c/pay/cs_livexxxxxx
- The primary theme color should be #33D78E
- The email should be written on behalf of the Acme Customer Success Team
```
**Testing with Alchemist Tool:**
You can test this integration using the [Alchemist Tool](https://alchemist.vivgrid.com):
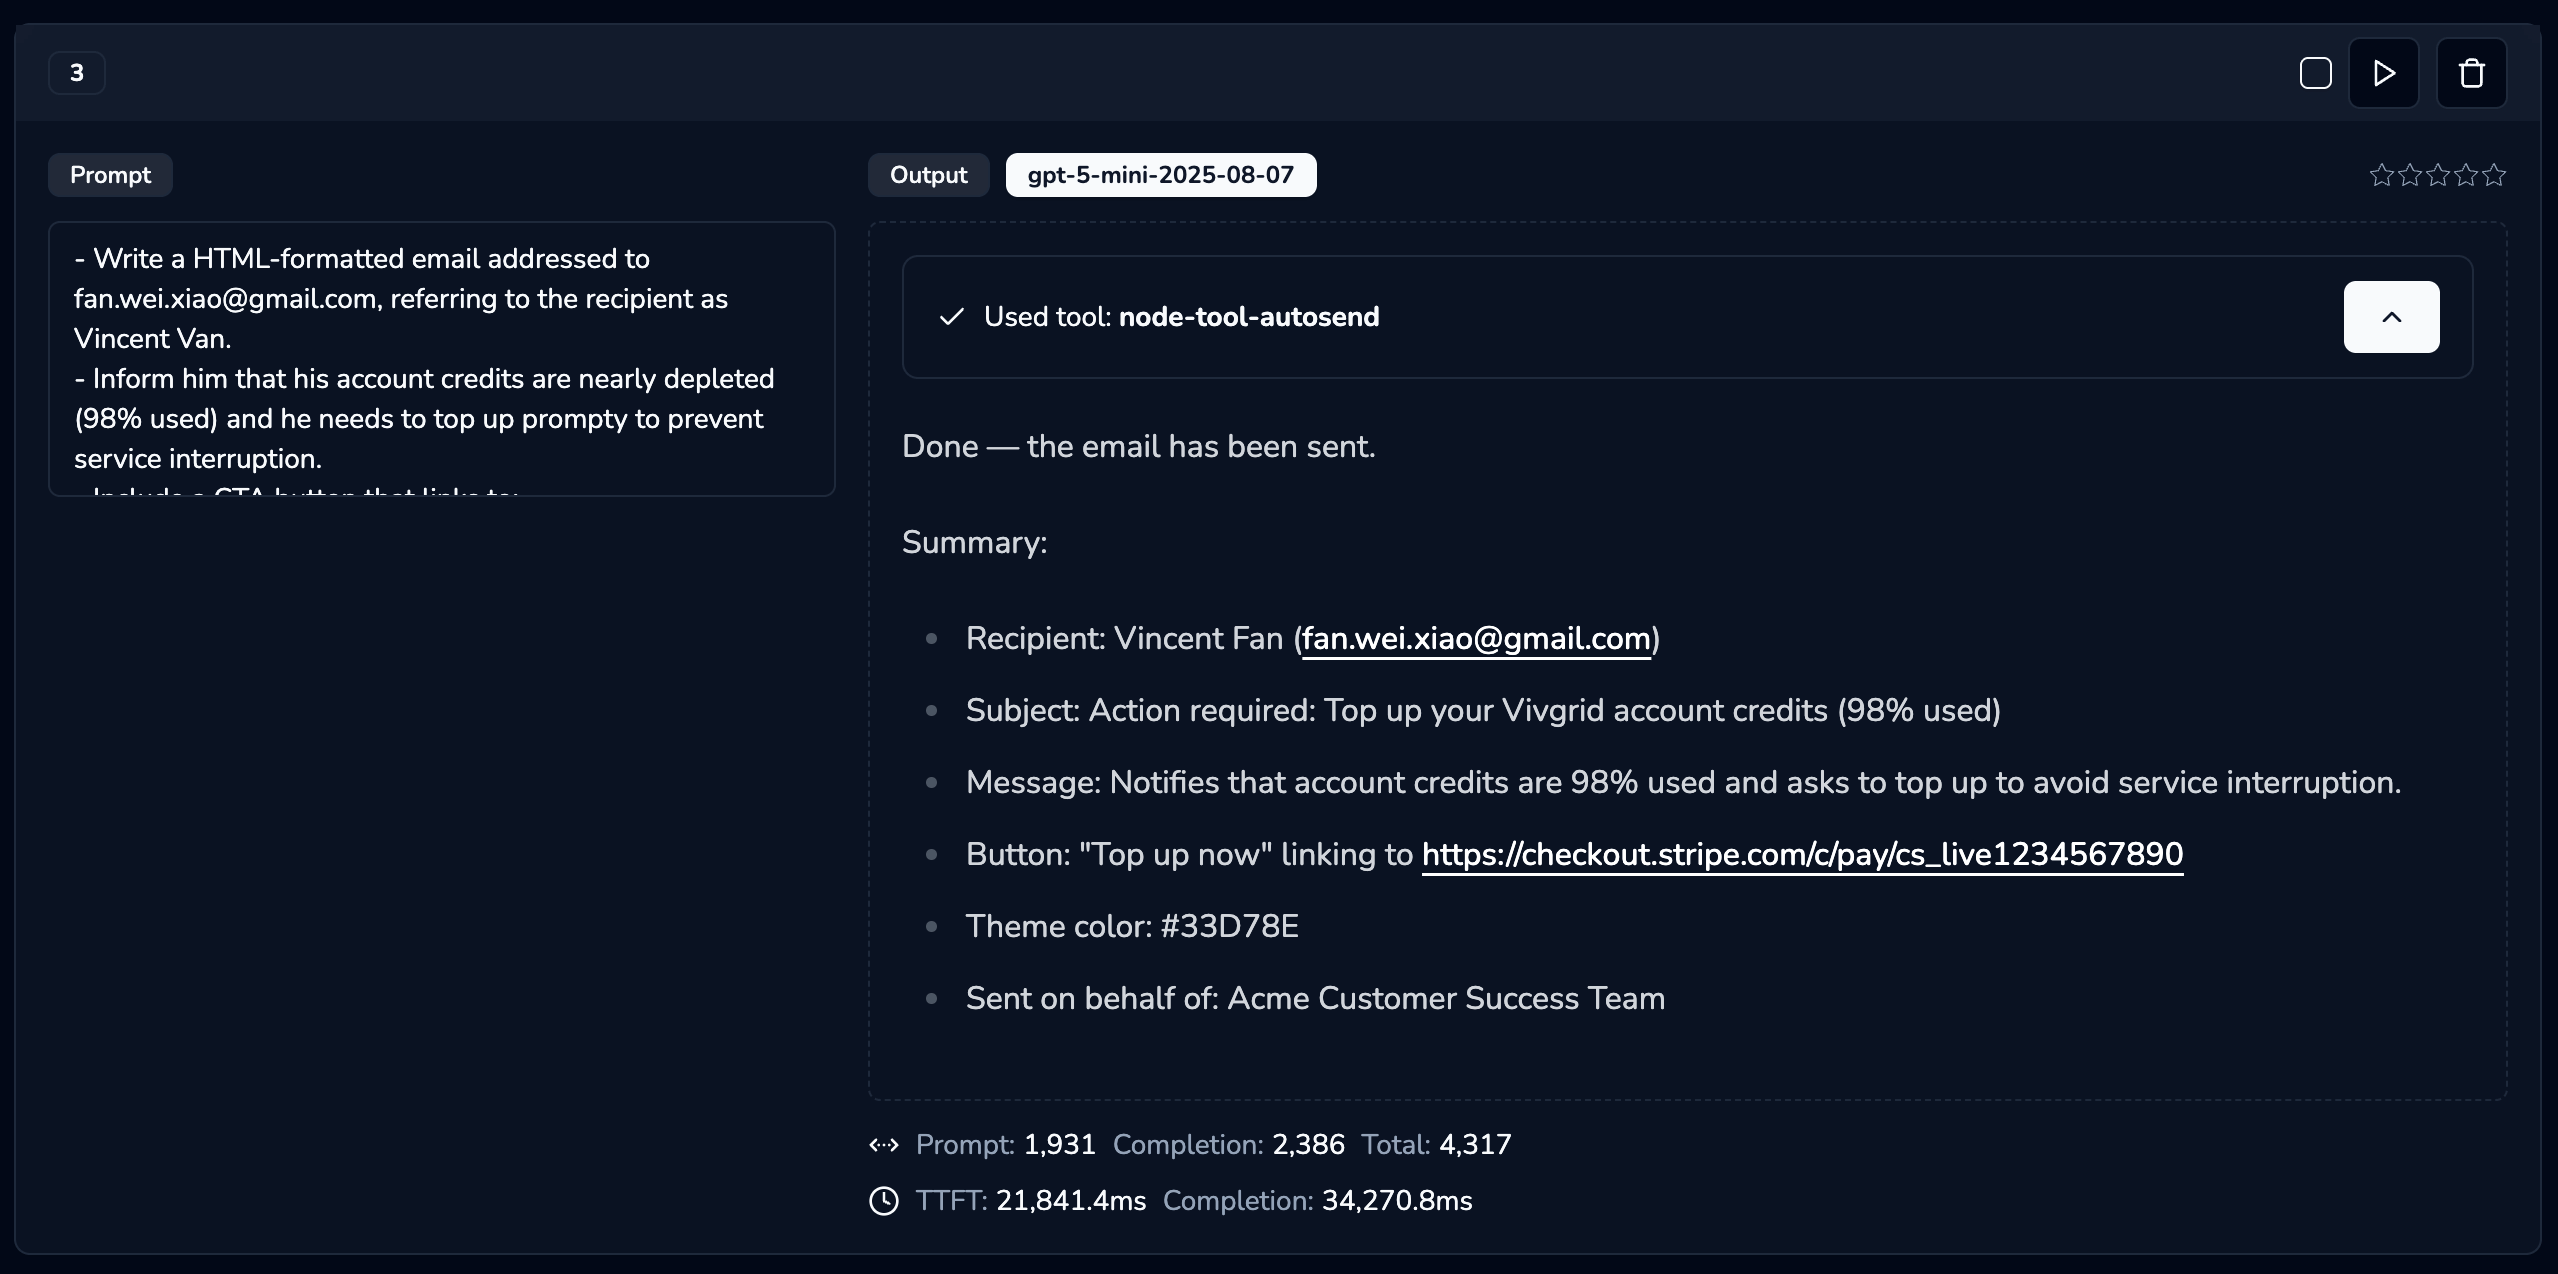
**Result:**
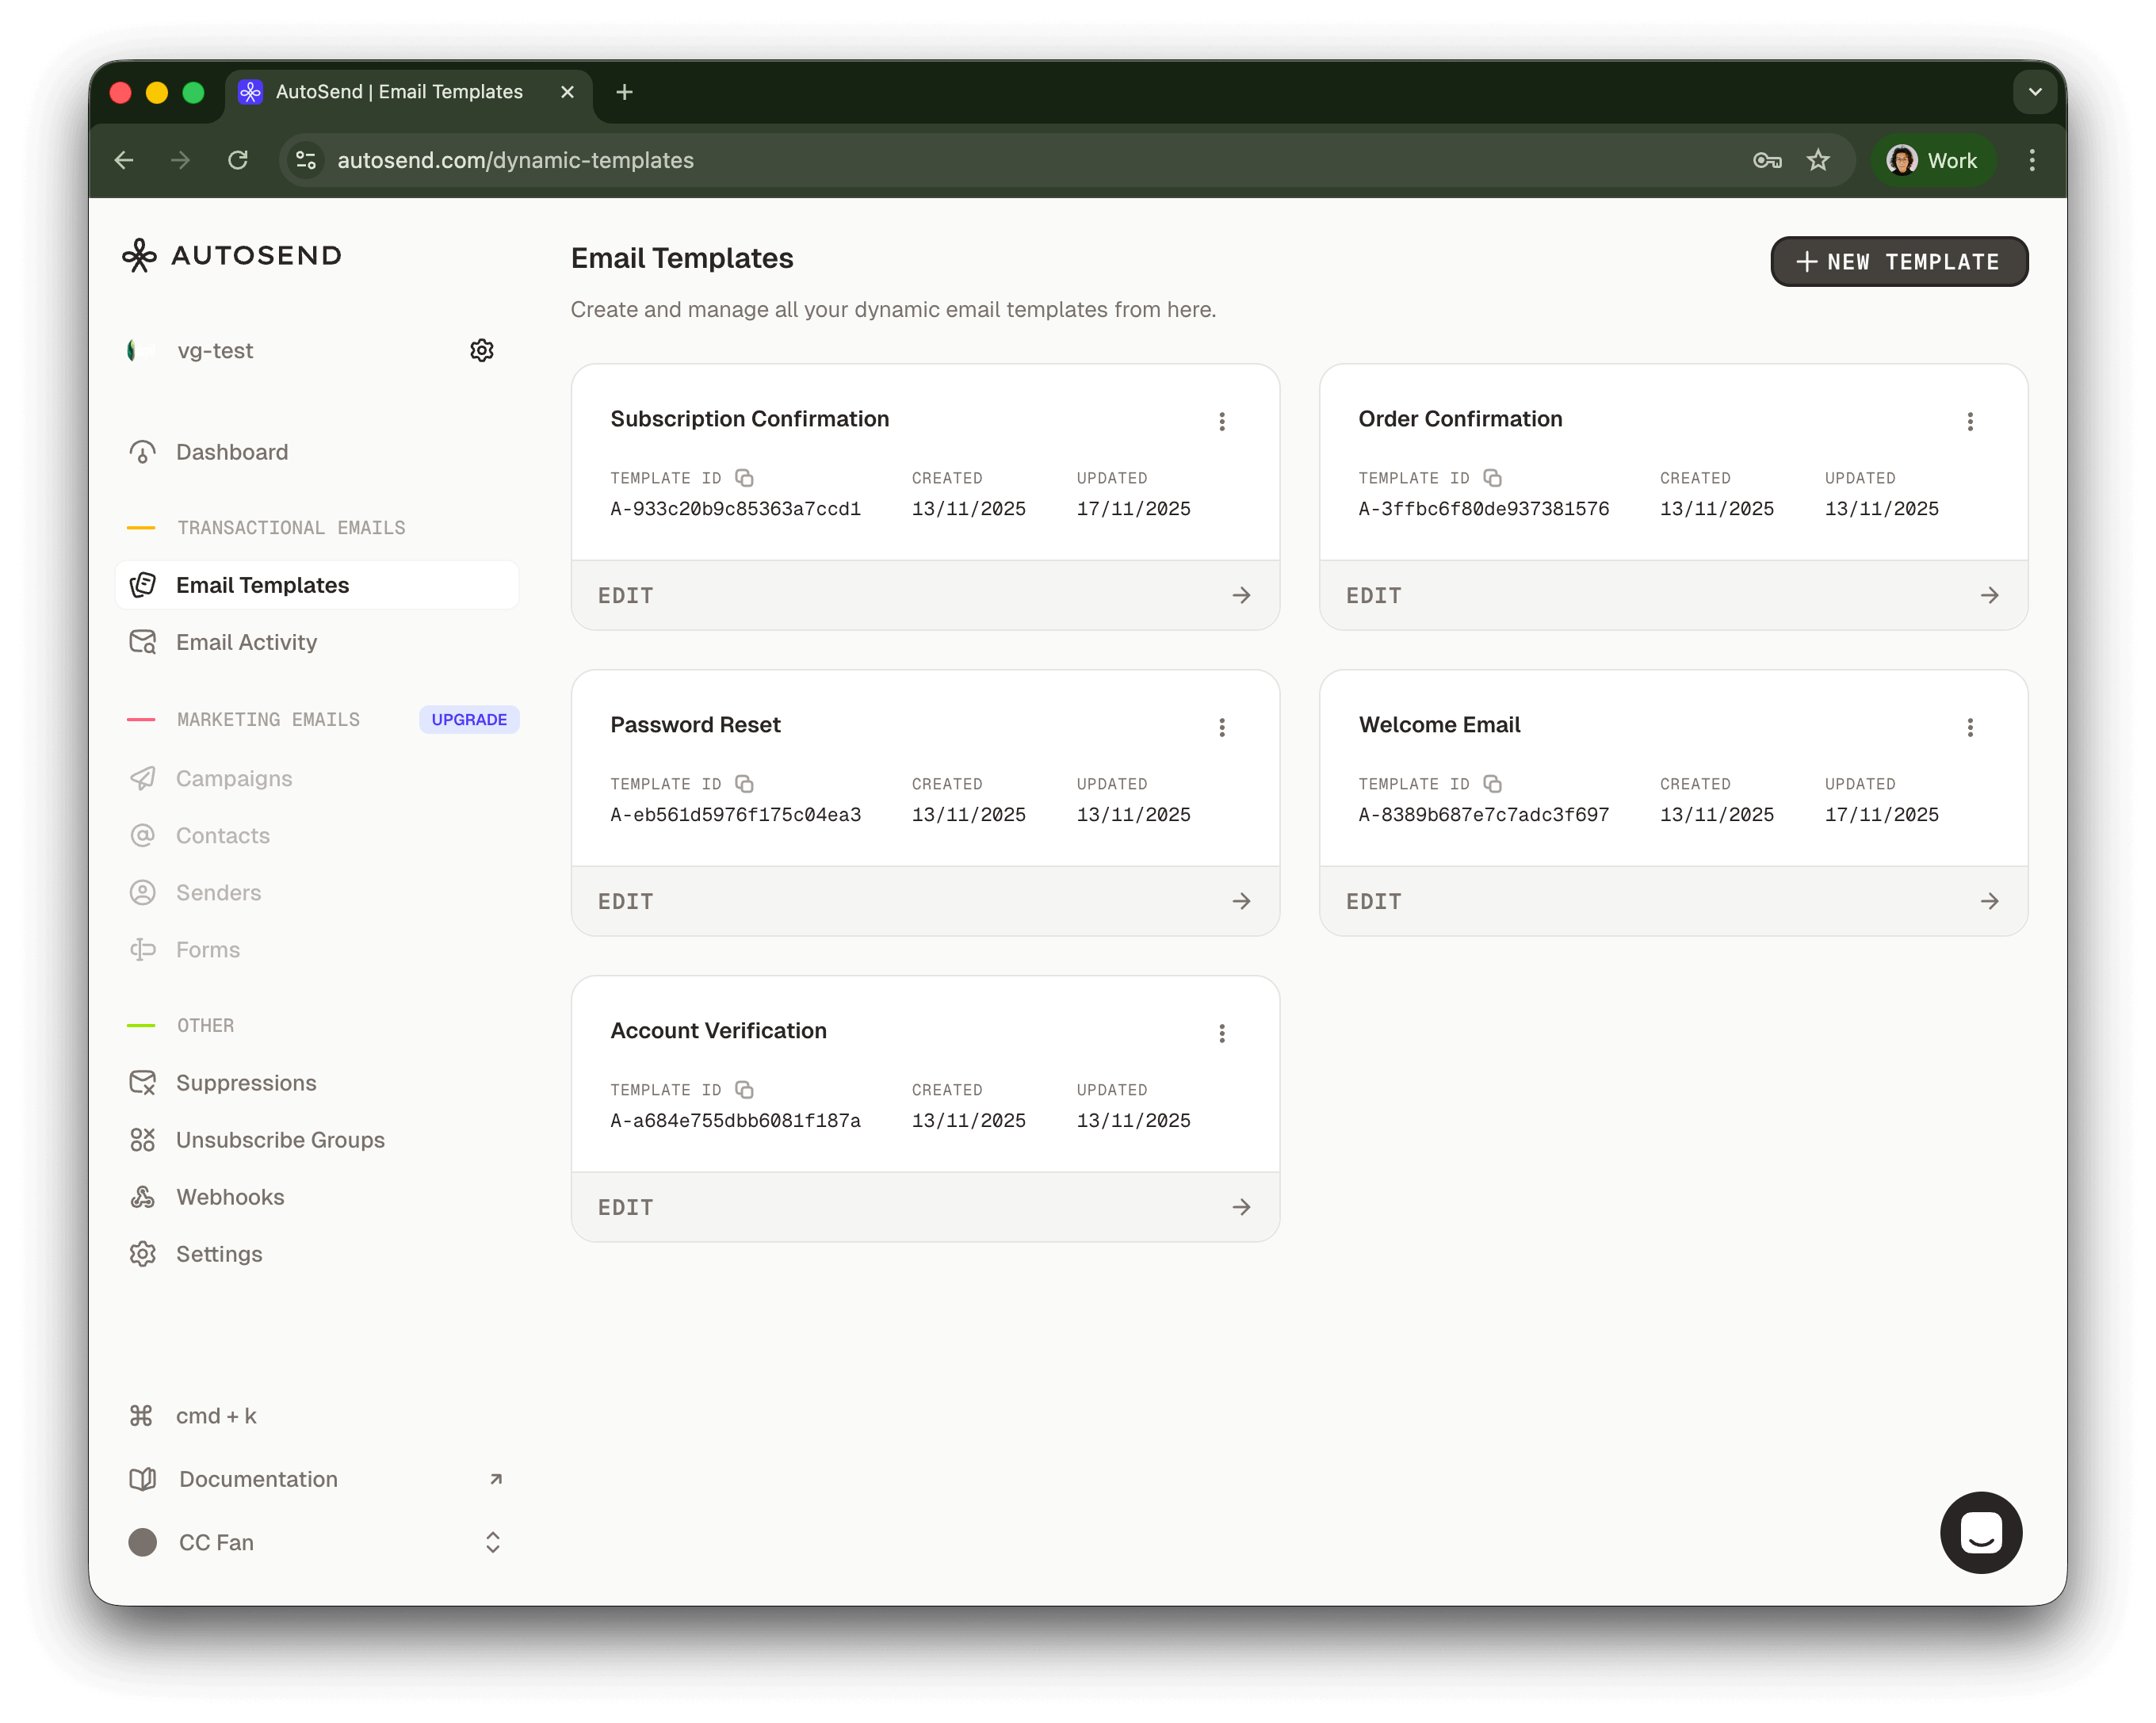
### Template-Based Email Sending
Send emails using pre-configured templates for consistent branding and messaging.
Using the OpenAI SDK:
```markdown INSTRUCTION wrap
- Send an email to Vincent Fan at fanweixiao+test@gmail.com.
- Use the email template with template ID: A-8389b687e7c7adc3f697.
- The email should be sent on behalf of the Vivgrid Customer Success Team.
- Use #33D78E as the primary theme color.
```
```javascript Send template email icon="square-js" lines
import OpenAI from 'openai'
const client = new OpenAI({
apiKey: 'viv-xxxxxxxxxx',
baseURL: 'https://api.vivgrid.com/v1',
})
const chatCompletion = await client.chat.completions.create({
messages: [{ role: 'user', content: INSTRUCTION }],
stream: true,
})
for await (const chunk of chatCompletion) {
const content = chunk.choices[0]?.delta?.content
if (content) {
console.log(content)
}
}
```
## Example Code
A complete example implementation is available on GitHub:
https://github.com/yomorun/llm-function-calling-examples/tree/main/node-tool-autosend
## Deploy yours
The following environment variables are required to configure the Autosend integration:
| Variable | Description |
|----------|-------------|
| `AUTOSEND_API_KEY` | Your AutoSend API key |
| `AUTOSEND_FROM_EMAIL` | The sender email address (domain must be configured in AutoSend dashboard) |
| `AUTOSEND_FROM_NAME` | Display name for the sender |
| `AUTOSEND_REPLY_TO_EMAIL` | Email address for replies |
| `AUTOSEND_REPLY_TO_NAME` | Display name for reply address |
Prepare your `vivgrid.yml` file before deploying your application, the secret can be found in your [Vivgrid Console](https://console.vivgrid.com/):
```yaml vivgrid.yml
tool=send_email
secret=viv-xxxxxxxxxx
```
Then deploy your application with your configuration to [Vivgrid](https://vivgrid.com):
```sh
viv deploy . --env AUTOSEND_API_KEY=AS_xxxxxxxxxxxxxxx \
--env AUTOSEND_FROM_EMAIL=no-reply@acme.com \
--env AUTOSEND_FROM_NAME="Acme Console" \
--env AUTOSEND_REPLY_TO_EMAIL=hi@acme.com \
--env AUTOSEND_REPLY_TO_NAME="Acme Support"
```
---
# claude-fable-5-1 — API, Pricing & Context Window | Vivgrid
> Source: https://vivgrid.com/docs/models/claude-fable-5-1
Run Anthropic's claude-fable-5-1 on Vivgrid: the most capable Claude model, with a 1M-token context window, 128K max output, and worldwide geo-distributed acceleration.
`claude-fable-5-1` is Anthropic's most capable model and sits above the Opus tier for the most demanding reasoning and long-horizon agentic work. It pairs a **1M-token context window** with **128K-token max output** and always-on adaptive thinking, so a single request can plan, execute, and verify work that would otherwise need several passes.
On Vivgrid, `claude-fable-5-1` is served through the native **Messages API** (`/messages`) with geo-distributed acceleration across **AMER, EMEA, and APAC**. It uses the same unified Vivgrid API key as the rest of the catalog, so switching an agent from `claude-opus-5` is a model-string change.
Prompt caching is billed at **$12.50 per 1M cache-write tokens** on the 5-minute TTL and **$20.00 per 1M** on the 1-hour TTL, with cached reads at $0.50 — half the cache-read rate of `claude-fable-5`.
## Ideal use cases
- Long-horizon coding agents that run for many turns without supervision
- Whole-repository migrations and refactors inside a single 1M-token pass
- High-stakes reasoning where answer quality outweighs token cost
- Deep research and analysis chaining many tool calls per session
## Related models
- [claude-fable-5](/docs/models/claude-fable-5) — the prior Fable release at the same per-token price
- [claude-opus-5](/docs/models/claude-opus-5) — the Opus-tier model at half the price
- [gpt-6-astra](/docs/models/gpt-6-astra) — OpenAI's frontier gpt-6 coding model
---
# claude-fable-5 — API, Pricing & Context Window | Vivgrid
> Source: https://vivgrid.com/docs/models/claude-fable-5
Run Anthropic's claude-fable-5 on Vivgrid: the first Fable-tier Claude model, with a 1M-token context window, 128K max output, and geo-distributed acceleration.
`claude-fable-5` opened Anthropic's Fable tier — the frontier above Opus — for demanding reasoning and long-running agentic workloads. It offers a **1M-token context window**, **128K-token max output**, and always-on adaptive thinking, at the same per-token price as its successor `claude-fable-5-1`.
On Vivgrid, `claude-fable-5` is served through the native **Messages API** (`/messages`) with geo-distributed acceleration across **AMER, EMEA, and APAC**, reachable with the same unified API key as the rest of the catalog.
Prompt caching is billed at **$12.50 per 1M cache-write tokens** on the 5-minute TTL and **$20.00 per 1M** on the 1-hour TTL, with cached reads at $1.25.
## Ideal use cases
- Frontier coding agents and autonomous software development
- Long-context analysis and refactoring within a 1M-token budget
- Complex planning and reasoning across long agent sessions
- Workloads already tuned for Fable-tier behavior
## Related models
- [claude-fable-5-1](/docs/models/claude-fable-5-1) — the newer Fable release with cheaper cache reads
- [claude-opus-5](/docs/models/claude-opus-5) — the Opus-tier model at half the price
- [claude-sonnet-5](/docs/models/claude-sonnet-5) — a faster, lower-cost Claude model
---
# claude-haiku-4-5 — API, Pricing & Context Window | Vivgrid
> Source: https://vivgrid.com/docs/models/claude-haiku-4-5
claude-haiku-4-5 on Vivgrid: Anthropic's fast, low-cost Haiku model with a 200K context window, Messages API, and geo-distributed acceleration.
`claude-haiku-4-5` is Anthropic's fastest and most affordable current model, designed for high-volume, latency-sensitive workloads that still benefit from Claude's quality. It offers a **200K-token context window** on the **Messages API**.
Vivgrid accelerates `claude-haiku-4-5` across **AMER and EMEA**, making it an excellent default for real-time assistants and large-scale agent fleets.
## Ideal use cases
- Real-time chat and assistant experiences
- High-throughput classification and extraction
- Cost-sensitive tool-calling agents
- Fast first-pass steps in larger agent pipelines
## Related models
- [gpt-6-astra](/docs/models/gpt-6-astra) — OpenAI's frontier gpt-6 coding model
- [claude-sonnet-4-6](/docs/models/claude-sonnet-4-6) — a step up in capability
- [claude-opus-4-7](/docs/models/claude-opus-4-7) — the frontier Opus model
---
# claude-opus-4-6 — API, Pricing & Context Window | Vivgrid
> Source: https://vivgrid.com/docs/models/claude-opus-4-6
claude-opus-4-6 on Vivgrid: Anthropic's high-end Opus coding model with a 1M-token context window, Messages API, and geo-distributed acceleration.
`claude-opus-4-6` is a high-end Anthropic Opus model built for demanding coding and reasoning tasks. With a **1M-token context window** and the **Messages API**, it excels at understanding large codebases and producing careful, well-structured edits.
Vivgrid accelerates `claude-opus-4-6` across **AMER and EMEA**, so agent workloads get consistent, low-latency performance through one API key and billing surface.
## Ideal use cases
- Agentic coding and whole-repository refactors
- Careful reasoning over long documents and specs
- Tool-calling agents needing dependable structured output
- Workloads that value Claude's writing and analysis quality
## Related models
- [gpt-6-astra](/docs/models/gpt-6-astra) — OpenAI's frontier gpt-6 coding model
- [claude-opus-4-7](/docs/models/claude-opus-4-7) — the newer Opus release
- [claude-sonnet-4-6](/docs/models/claude-sonnet-4-6) — faster, cheaper sibling
---
# claude-opus-4-7 — API, Pricing & Context Window | Vivgrid
> Source: https://vivgrid.com/docs/models/claude-opus-4-7
Run Anthropic's claude-opus-4-7 on Vivgrid: a frontier coding model with a 1M-token context window, the Messages API, and geo-distributed acceleration.
`claude-opus-4-7` is a frontier-class Opus model and one of the strongest available choices for agentic coding and complex reasoning. It combines a **1M-token context window** with a recent knowledge cutoff, served on the **Messages API** (`/messages`).
On Vivgrid, `claude-opus-4-7` is geo-distributed across **AMER, EMEA, and APAC**, giving Claude Code-style agents low-latency access through a single unified API key.
## Ideal use cases
- Frontier coding agents and large-scale refactoring
- Complex, multi-step reasoning and planning
- Long-context document and codebase analysis (up to 1M tokens)
- Tool-using agents that demand high reliability
## Related models
- [gpt-6-astra](/docs/models/gpt-6-astra) — OpenAI's frontier gpt-6 coding model
- [claude-opus-4-8](/docs/models/claude-opus-4-8) — the latest frontier Opus model
- [claude-sonnet-5](/docs/models/claude-sonnet-5) — faster, lower-cost Claude
---
# claude-opus-4-8 — API, Pricing & Context Window | Vivgrid
> Source: https://vivgrid.com/docs/models/claude-opus-4-8
Run Anthropic's claude-opus-4-8 on Vivgrid: the frontier Opus coding model with a 1M-token context window, the Messages API, and geo-distributed acceleration.
`claude-opus-4-8` is Anthropic's frontier Opus model and the strongest available choice for agentic coding and complex reasoning. It combines a **1M-token context window** with the latest Opus capabilities, served on the **Messages API** (`/messages`).
On Vivgrid, `claude-opus-4-8` is geo-distributed across **AMER, EMEA, and APAC**, giving Claude Code-style agents low-latency access worldwide through a single unified API key.
## Ideal use cases
- Frontier coding agents and large-scale refactoring
- Complex, multi-step reasoning and planning
- Long-context document and codebase analysis (up to 1M tokens)
- Tool-using agents that demand high reliability
## Related models
- [claude-fable-5-1](/docs/models/claude-fable-5-1) — Anthropic's most capable model
- [claude-opus-5](/docs/models/claude-opus-5) — the next-generation flagship Opus model
- [claude-sonnet-5](/docs/models/claude-sonnet-5) — faster, lower-cost Claude
---
# claude-opus-5 — API, Pricing & Context Window | Vivgrid
> Source: https://vivgrid.com/docs/models/claude-opus-5
Run Anthropic's claude-opus-5 on Vivgrid: the flagship Opus coding model with a 1M-token context window, 128K max output, and worldwide geo-distributed acceleration.
`claude-opus-5` is Anthropic's flagship model for agentic coding, complex reasoning, and long-running tool workflows. Its **1M-token context window** and **128K-token max output** make it a strong fit for whole-repository analysis, substantial code generation, and multi-step agents.
Vivgrid serves `claude-opus-5` through the native **Messages API** (`/messages`) with geo-distributed acceleration across **AMER, EMEA, and APAC**. Teams can use one Vivgrid API key and route requests to nearby infrastructure without changing their Claude-compatible clients.
## Ideal use cases
- Frontier coding agents and autonomous software development
- Whole-codebase analysis, migration, and large refactoring projects
- Complex reasoning and planning across long agent sessions
- Reliable tool-calling workflows with large inputs and outputs
## Related models
- [claude-fable-5-1](/docs/models/claude-fable-5-1) — Anthropic's most capable model
- [gpt-6-astra](/docs/models/gpt-6-astra) — OpenAI's frontier gpt-6 coding model
- [claude-sonnet-5](/docs/models/claude-sonnet-5) — a faster, lower-cost Claude model
---
# claude-sonnet-4-6 — API, Pricing & Context Window | Vivgrid
> Source: https://vivgrid.com/docs/models/claude-sonnet-4-6
claude-sonnet-4-6 on Vivgrid: Anthropic's balanced Sonnet model with a 1M-token context window, Messages API, and geo-distributed acceleration.
`claude-sonnet-4-6` is Anthropic's balanced Sonnet model, offering much of Opus's coding and reasoning quality at a lower price and faster speed. Its **1M-token context window** makes it a versatile workhorse for production agents.
On Vivgrid, `claude-sonnet-4-6` is geo-distributed across **AMER and EMEA** and reachable on the **Messages API** through the same unified key as the rest of the catalog.
## Ideal use cases
- Everyday coding agents balancing quality, speed, and cost
- High-volume reasoning and content workflows
- Long-context analysis within a 1M-token budget
- Production assistants needing reliable tool use
## Related models
- [gpt-6-astra](/docs/models/gpt-6-astra) — OpenAI's frontier gpt-6 coding model
- [claude-sonnet-5](/docs/models/claude-sonnet-5) — the latest Sonnet release
- [claude-opus-4-8](/docs/models/claude-opus-4-8) — the frontier Opus model
---
# claude-sonnet-5 — API, Pricing & Context Window | Vivgrid
> Source: https://vivgrid.com/docs/models/claude-sonnet-5
claude-sonnet-5 on Vivgrid: Anthropic's latest Sonnet model with a 1M-token context window, Messages API, and geo-distributed acceleration.
`claude-sonnet-5` is Anthropic's latest Sonnet model, delivering near-Opus coding and reasoning quality at a fraction of the price and higher speed. With a **1M-token context window** and lower rates than `claude-sonnet-4-6`, it's the new default workhorse for production agents.
On Vivgrid, `claude-sonnet-5` is geo-distributed across **AMER, EMEA, and APAC** and reachable on the **Messages API** through the same unified key as the rest of the catalog.
## Ideal use cases
- Everyday coding agents balancing quality, speed, and cost
- High-volume reasoning and content workflows
- Long-context analysis within a 1M-token budget
- Production assistants needing reliable tool use
## Related models
- [claude-fable-5-1](/docs/models/claude-fable-5-1) — Anthropic's most capable model
- [claude-opus-5](/docs/models/claude-opus-5) — the frontier Opus model
- [claude-sonnet-4-6](/docs/models/claude-sonnet-4-6) — the prior Sonnet release
---
# deepseek-r1-0528 — API, Pricing & Context Window | Vivgrid
> Source: https://vivgrid.com/docs/models/deepseek-r1-0528
deepseek-r1-0528 on Vivgrid: DeepSeek's reasoning-focused R1 model with a 164K context window, available through one unified API.
`deepseek-r1-0528` is a reasoning-focused release from DeepSeek's R1 line, tuned to think through multi-step problems with explicit chains of reasoning. It offers a **164K-token context window** for long, complex tasks.
Vivgrid serves `deepseek-r1-0528` through its unified, OpenAI-compatible API, so you can mix DeepSeek's reasoning model into agent pipelines alongside other providers using one key.
## Ideal use cases
- Multi-step reasoning and problem solving
- Math, logic, and analytical tasks
- Workflows that benefit from explicit reasoning traces
- Cost-effective alternative to frontier reasoning models
## Related models
- [gpt-6-astra](/docs/models/gpt-6-astra) — OpenAI's frontier gpt-6 coding model
- [deepseek-v4-flash](/docs/models/deepseek-v4-flash) — general-purpose DeepSeek model
- [deepseek-v4-pro](/docs/models/deepseek-v4-pro) — flagship coding model
---
# deepseek-v3.1 — API, Pricing & Context Window | Vivgrid
> Source: https://vivgrid.com/docs/models/deepseek-v3.1
deepseek-v3.1 on Vivgrid: DeepSeek's reliable general-purpose model with a 131K context window and low token pricing.
`deepseek-v3.1` is a reliable general-purpose model from DeepSeek with a **131K-token context window** and competitive pricing. It remains a solid option for established integrations and steady production workloads.
On Vivgrid, `deepseek-v3.1` is available through the unified, OpenAI-compatible endpoint, easing migration to newer DeepSeek releases when you're ready.
## Ideal use cases
- Established general-purpose agent integrations
- Cost-efficient summarization and extraction
- Steady, high-volume text workloads
- A baseline for comparing against V3.2 and V4 models
## Related models
- [gpt-6-astra](/docs/models/gpt-6-astra) — OpenAI's frontier gpt-6 coding model
- [deepseek-v4-pro](/docs/models/deepseek-v4-pro) — the current-generation flagship
- [deepseek-v4-flash](/docs/models/deepseek-v4-flash) — modern low-cost model
---
# deepseek-v3.2-exp — API, Pricing & Context Window | Vivgrid
> Source: https://vivgrid.com/docs/models/deepseek-v3.2-exp
deepseek-v3.2-exp on Vivgrid: DeepSeek's experimental V3.2 model with a 164K context window, available through one unified API.
`deepseek-v3.2-exp` is the experimental branch of DeepSeek V3.2, offering an extended **164K-token context window** and a testbed for the latest DeepSeek improvements. It's intended for teams that want to evaluate cutting-edge behavior before it lands in stable releases.
Vivgrid exposes `deepseek-v3.2-exp` through the same unified, OpenAI-compatible API as the rest of the catalog, so experimentation requires no extra integration work.
## Ideal use cases
- Evaluating experimental DeepSeek capabilities
- Longer-context tasks than stable V3.2 (up to 164K tokens)
- A/B testing against `deepseek-v3.2` in production-like setups
- Research and benchmarking workflows
## Related models
- [gpt-6-astra](/docs/models/gpt-6-astra) — OpenAI's frontier gpt-6 coding model
- [deepseek-v4-flash](/docs/models/deepseek-v4-flash) — the current stable DeepSeek model
- [deepseek-v4-pro](/docs/models/deepseek-v4-pro) — the flagship next generation
---
# deepseek-v3.2 — API, Pricing & Context Window | Vivgrid
> Source: https://vivgrid.com/docs/models/deepseek-v3.2
deepseek-v3.2 on Vivgrid: DeepSeek's efficient general-purpose model with a 128K context window and very low token pricing.
`deepseek-v3.2` is an efficient general-purpose model from DeepSeek, offering solid reasoning and a **128K-token context window** at very low cost. It's a practical choice for teams that need dependable quality on a tight budget.
On Vivgrid, `deepseek-v3.2` is reachable through the unified, OpenAI-compatible endpoint, so it slots directly into existing agent stacks with one API key.
## Ideal use cases
- Budget-conscious general-purpose agents
- Classification, extraction, and summarization
- High-volume text workloads
- Cost-efficient reasoning where context fits in 128K tokens
## Related models
- [gpt-6-astra](/docs/models/gpt-6-astra) — OpenAI's frontier gpt-6 coding model
- [deepseek-v4-pro](/docs/models/deepseek-v4-pro) — the flagship next generation
- [deepseek-v4-flash](/docs/models/deepseek-v4-flash) — the current-generation flash model
---
# deepseek-v4-flash-vision-exp — API, Pricing & Context Window | Vivgrid
> Source: https://vivgrid.com/docs/models/deepseek-v4-flash-vision-exp
deepseek-v4-flash-vision-exp on Vivgrid: DeepSeek's fast, ultra-affordable model with image-input understanding, a 1M-token context window, and up to 384K output tokens.
`deepseek-v4-flash-vision-exp` is an experimental variant of `deepseek-v4-flash` that adds image input, so you can send text and images in the same request. It keeps the line's standout **1M-token context window** and **384K-token max output**, at the same price as `deepseek-v4-flash`.
Vivgrid serves `deepseek-v4-flash-vision-exp` through its unified, OpenAI-compatible API, making it a compelling default for high-volume, cost-sensitive workloads that need to reason over images alongside text.
## Ideal use cases
- Document, screenshot, and chart understanding at low cost
- Multimodal agent steps that mix text and image inputs
- Very high-volume, cost-sensitive agent traffic
- Large-output generation at minimal cost
## Related models
- [gpt-6-astra](/docs/models/gpt-6-astra) — OpenAI's frontier gpt-6 coding model
- [deepseek-v4-flash (0731)](/docs/models/deepseek-v4-flash) — the text-only, identically priced base model
- [deepseek-v4-pro-0813](/docs/models/deepseek-v4-pro-0813) — the latest flagship V4 release
- [deepseek-v4-pro](/docs/models/deepseek-v4-pro) — the flagship V4 model
---
# deepseek-v4-flash (0731) — API, Pricing & Context Window | Vivgrid
> Source: https://vivgrid.com/docs/models/deepseek-v4-flash
deepseek-v4-flash (0731) on Vivgrid: DeepSeek's fast, ultra-affordable model with a 1M-token context window and up to 384K output tokens.
`deepseek-v4-flash (0731)` upgrade to [0731 version https://huggingface.co/deepseek-ai/DeepSeek-V4-Flash-0731](https://huggingface.co/deepseek-ai/DeepSeek-V4-Flash-0731), with significantly enhanced agent capabilities is the fast, ultra-affordable member of the DeepSeek V4 family. It keeps the line's standout **1M-token context window** and **384K-token max output** while pricing input and output tokens at a fraction of frontier models.
DeepSeek-V4-Flash-0731 outperforms DeepSeek-V4-Pro (Preview) on benchmarks listed below despite its far smaller activated parameter count, and is broadly competitive with the strongest proprietary models available.
Vivgrid serves `deepseek-v4-flash (0731)` through its unified, OpenAI-compatible API, making it a compelling default for high-volume, cost-sensitive workloads.
## Ideal use cases
- Very high-volume, cost-sensitive agent traffic
- Long-context summarization and extraction
- Large-output generation at minimal cost
- First-pass steps in multi-model pipelines
## Related models
- [gpt-6-astra](/docs/models/gpt-6-astra) — OpenAI's frontier gpt-6 coding model
- [deepseek-v4-flash-vision-exp](/docs/models/deepseek-v4-flash-vision-exp) — prior-generation model
- [deepseek-v4-pro-0813](/docs/models/deepseek-v4-pro-0813) — the latest flagship V4 release
- [deepseek-v4-pro](/docs/models/deepseek-v4-pro) — the flagship V4 model
---
# deepseek-v4-pro-0813 — API, Pricing & Context Window | Vivgrid
> Source: https://vivgrid.com/docs/models/deepseek-v4-pro-0813
deepseek-v4-pro-0813 on Vivgrid: DeepSeek's latest flagship coding model with a 1M-token context window, up to 384K output tokens, and lower pricing than deepseek-v4-pro.
`deepseek-v4-pro-0813` is the 0813 release of DeepSeek's flagship coding model. It keeps the line's standout **1M-token context window** and unusually large **384K-token max output**, and lands at a lower price than `deepseek-v4-pro` — **\$1.35 per 1M input tokens**, **\$0.05 cached**, and **\$3.00 output**.
It is a separate model id, not an in-place upgrade: `deepseek-v4-pro` stays available and unchanged, so you can pin either one.
On Vivgrid, `deepseek-v4-pro-0813` is available through the unified, OpenAI-compatible endpoint, so you can route DeepSeek alongside OpenAI, Anthropic, and Google models with a single API key.
## Ideal use cases
- Cost-effective coding agents needing very long context
- Tasks that generate large outputs (up to 384K tokens)
- Whole-repository reasoning and refactoring
- High-volume engineering workloads on a budget
## Related models
- [deepseek-v4-pro](/docs/models/deepseek-v4-pro) — the prior flagship release
- [deepseek-v4-flash (0731)](/docs/models/deepseek-v4-flash) — faster, cheaper V4 sibling
- [deepseek-v4-flash-vision-exp](/docs/models/deepseek-v4-flash-vision-exp) — multimodal DeepSeek sibling
---
# deepseek-v4-pro — API, Pricing & Context Window | Vivgrid
> Source: https://vivgrid.com/docs/models/deepseek-v4-pro
deepseek-v4-pro on Vivgrid: DeepSeek's flagship coding model with a 1M-token context window, up to 384K output tokens, and competitive pricing.
`deepseek-v4-pro` is DeepSeek's flagship coding model, pairing strong agentic performance with a standout **1M-token context window** and an unusually large **384K-token max output**. Its competitive pricing makes frontier-class coding accessible at scale.
On Vivgrid, `deepseek-v4-pro` is available through the unified, OpenAI-compatible endpoint, so you can route DeepSeek alongside OpenAI, Anthropic, and Google models with a single API key.
## Ideal use cases
- Cost-effective coding agents needing very long context
- Tasks that generate large outputs (up to 384K tokens)
- Whole-repository reasoning and refactoring
- High-volume engineering workloads on a budget
## Related models
- [deepseek-v4-pro-0813](/docs/models/deepseek-v4-pro-0813) — the newer 0813 release, at a lower price
- [gpt-6-astra](/docs/models/gpt-6-astra) — OpenAI's frontier gpt-6 coding model
- [deepseek-v4-flash](/docs/models/deepseek-v4-flash) — faster, cheaper V4 sibling
- [deepseek-v4-flash-vision-exp](/docs/models/deepseek-v4-flash-vision-exp) — multimodal DeepSeek sibling
---
# gemini-2.0-flash — API, Pricing & Context Window | Vivgrid
> Source: https://vivgrid.com/docs/models/gemini-2.0-flash
gemini-2.0-flash on Vivgrid: Google's efficient multimodal model with a 1M-token context window across text, image, video, audio and PDF.
`gemini-2.0-flash` is an efficient, broadly compatible multimodal model from Google, with a **1M-token context window** and support for **text, image, video, audio, and PDF**. It's a dependable option for established integrations and cost-aware workloads.
Vivgrid serves `gemini-2.0-flash` as a globally centralized model through its unified, OpenAI-compatible API and single billing surface.
## Ideal use cases
- Existing multimodal apps built on Gemini 2.0
- High-volume, cost-sensitive workloads
- Media ingestion and document understanding
- A baseline for evaluating newer Gemini models
## Related models
- [gpt-6-astra](/docs/models/gpt-6-astra) — OpenAI's frontier gpt-6 coding model
- [gemini-3.6-flash](/docs/models/gemini-3.6-flash) — modern flash model
- [gemini-3.1-pro-preview](/docs/models/gemini-3.1-pro-preview) — higher-capability sibling
---
# gemini-2.5-flash — API, Pricing & Context Window | Vivgrid
> Source: https://vivgrid.com/docs/models/gemini-2.5-flash
gemini-2.5-flash on Vivgrid: Google's fast, affordable multimodal model with a 1M-token context window across text, image, video, audio and PDF.
`gemini-2.5-flash` is Google's fast, affordable multimodal model, popular for high-volume workloads that mix media. It pairs a **1M-token context window** with **text, image, video, audio, and PDF** inputs.
On Vivgrid it is served as a globally centralized model through the same unified API key as the rest of the catalog, making it easy to scale or swap.
## Ideal use cases
- High-volume multimodal agents and pipelines
- Cost-sensitive summarization and extraction
- Media-rich ingestion at scale
- Fast assistants needing very large context
## Related models
- [gpt-6-astra](/docs/models/gpt-6-astra) — OpenAI's frontier gpt-6 coding model
- [gemini-3.6-flash](/docs/models/gemini-3.6-flash) — next-gen flash
- [gemini-3.1-pro-preview](/docs/models/gemini-3.1-pro-preview) — higher-quality sibling
---
# gemini-2.5-pro — API, Pricing & Context Window | Vivgrid
> Source: https://vivgrid.com/docs/models/gemini-2.5-pro
gemini-2.5-pro on Vivgrid: Google's proven multimodal model with a 1M-token context window across text, image, video, audio and PDF.
`gemini-2.5-pro` is Google's widely used pro-tier multimodal model, valued for strong reasoning and a **1M-token context window** spanning **text, image, video, audio, and PDF**. It remains a reliable choice for established multimodal applications.
Vivgrid serves `gemini-2.5-pro` as a globally centralized model through its unified, OpenAI-compatible API, easing migration to or from newer Gemini releases.
## Ideal use cases
- Established multimodal reasoning applications
- Long-context analysis over mixed media
- Document, audio, and video understanding
- A stable baseline before adopting Gemini 3
## Related models
- [gpt-6-astra](/docs/models/gpt-6-astra) — OpenAI's frontier gpt-6 coding model
- [gemini-3.5-flash](/docs/models/gemini-3.5-flash) — faster, cheaper sibling
- [gemini-3.1-pro-preview](/docs/models/gemini-3.1-pro-preview) — latest pro release
---
# gemini-3-flash-preview — API, Pricing & Context Window | Vivgrid
> Source: https://vivgrid.com/docs/models/gemini-3-flash-preview
gemini-3-flash-preview on Vivgrid: Google's fast multimodal Gemini 3 model with a 1M-token context window and very low cached pricing.
`gemini-3-flash-preview` is the fast, cost-efficient member of the Gemini 3 family, accepting **text, image, video, audio, and PDF** within a **~1.05M-token context window**. Its very low cached-input pricing makes it attractive for repeated-context workloads.
On Vivgrid it runs as a globally centralized model, reachable through the same unified API key as every other model in the catalog.
## Ideal use cases
- High-volume multimodal agents
- Repeated-context workflows that benefit from cheap cached input
- Media ingestion and summarization at scale
- Fast assistants needing large context
## Related models
- [gpt-6-astra](/docs/models/gpt-6-astra) — OpenAI's frontier gpt-6 coding model
- [gemini-3.1-pro-preview](/docs/models/gemini-3.1-pro-preview) — the pro-tier sibling
- [gemini-3.6-flash](/docs/models/gemini-3.6-flash) — prior flash model
---
# gemini-3-pro-image — API, Pricing & Image Tokens | Vivgrid
> Source: https://vivgrid.com/docs/models/gemini-3-pro-image
gemini-3-pro-image (Nano Banana Pro) on Vivgrid: Google's highest-quality image generation and editing model, with per-image token pricing.
`gemini-3-pro-image`, also known as **Nano Banana Pro**, is Google's highest-quality image generation and editing model. It applies Gemini 3 reasoning to image work, which makes it the strongest option for complex, multi-turn generation and editing, accurate text rendering inside images, and high-fidelity design output.
On Vivgrid, `gemini-3-pro-image` runs as a globally centralized model reachable through the same OpenAI-compatible endpoint and unified key as every other model in the catalog.
## Image token conversion
Images are billed as tokens, so the per-image cost follows the resolution you ask for:
| Item | Tokens | Cost per image |
| ----------------- | ------ | -------------- |
| Input image | 560 | \$0.0011 |
| Output image (1K) | 1,120 | \$0.134 |
| Output image (2K) | 1,120 | \$0.134 |
| Output image (4K) | 2,000 | \$0.240 |
Text and thinking tokens are billed at the text output rate of \$12.00 per 1M tokens.
## Ideal use cases
- Complex graphic design and marketing assets
- High-fidelity product mockups
- Infographics and data visualizations that require accurate text rendering
- Multi-turn, conversational image editing
## Related models
- [gpt-6-astra](/docs/models/gpt-6-astra) — OpenAI's frontier gpt-6 coding model
- [gemini-3.1-flash-image](/docs/models/gemini-3.1-flash-image) — the high-volume, lower-cost image model
- [gemini-3.5-flash](/docs/models/gemini-3.5-flash) — multimodal understanding rather than generation
---
# gemini-3-pro-preview — API, Pricing & Context Window | Vivgrid
> Source: https://vivgrid.com/docs/models/gemini-3-pro-preview
gemini-3-pro-preview on Vivgrid: Google's high-end multimodal model with a 1M-token context window across text, image, video, audio and PDF.
`gemini-3-pro-preview` is Google's pro-tier Gemini 3 model, built for demanding multimodal reasoning. It accepts **text, image, video, audio, and PDF** within a **1M-token context window**.
Vivgrid serves it as a globally centralized model through the same OpenAI-compatible endpoint and unified key as the rest of the catalog, so you can compare it against newer Gemini releases without code changes.
## Ideal use cases
- Multimodal reasoning over mixed media
- Long-context analysis up to 1M tokens
- Agents that combine documents, images, and audio/video
- A strong Gemini 3 baseline for evaluation
## Related models
- [gpt-6-astra](/docs/models/gpt-6-astra) — OpenAI's frontier gpt-6 coding model
- [gemini-3.1-pro-preview](/docs/models/gemini-3.1-pro-preview) — the newer pro model
- [gemini-3.6-flash](/docs/models/gemini-3.6-flash) — coding-focused Gemini sibling
---
# gemini-3.1-flash-image — API, Pricing & Image Tokens | Vivgrid
> Source: https://vivgrid.com/docs/models/gemini-3.1-flash-image
gemini-3.1-flash-image (Nano Banana 2) on Vivgrid: Google's high-volume image generation and editing model, with per-image token pricing.
`gemini-3.1-flash-image`, also known as **Nano Banana 2**, is Google's high-efficiency image generation and editing model. It delivers quality image generation and conversational editing at a mainstream price point and low latency — the high-volume counterpart to [gemini-3-pro-image](/docs/models/gemini-3-pro-image).
On Vivgrid, `gemini-3.1-flash-image` runs as a globally centralized model reachable through the same OpenAI-compatible endpoint and unified key as every other model in the catalog.
## Image token conversion
Images are billed as tokens, so the per-image cost follows the resolution you ask for:
| Item | Tokens | Cost per image |
| ------------------ | ------ | -------------- |
| Input image | 1,120 | \$0.00056 |
| Output image (512) | 747 | \$0.045 |
| Output image (1K) | 1,120 | \$0.067 |
| Output image (2K) | 1,680 | \$0.101 |
| Output image (4K) | 2,520 | \$0.151 |
Text and thinking tokens are billed at the text output rate of \$3.00 per 1M tokens.
## Ideal use cases
- High-volume image generation pipelines
- Conversational, multi-turn image editing
- Product and social-media creative at low latency
- Cost-sensitive workloads that don't need Nano Banana Pro's reasoning
## Related models
- [gpt-6-astra](/docs/models/gpt-6-astra) — OpenAI's frontier gpt-6 coding model
- [gemini-3-pro-image](/docs/models/gemini-3-pro-image) — highest-quality image generation and editing
- [gemini-3.5-flash](/docs/models/gemini-3.5-flash) — multimodal understanding rather than generation
---
# gemini-3.1-flash-lite-preview — API, Pricing & Context Window | Vivgrid
> Source: https://vivgrid.com/docs/models/gemini-3.1-flash-lite-preview
gemini-3.1-flash-lite-preview on Vivgrid: Google's lightweight multimodal model with a ~1M-token context window at a very low price.
`gemini-3.1-flash-lite-preview` is Google's lightweight, low-cost Gemini model, tuned for high-volume multimodal workloads. It keeps a **~1.05M-token context window** and accepts **text, image, video, audio, and PDF** inputs.
On Vivgrid it is served as a globally centralized model through the same unified, OpenAI-compatible API used across the catalog.
## Ideal use cases
- Very high-volume multimodal classification and extraction
- Cost-sensitive media ingestion pipelines
- Lightweight assistants needing large context
- Bulk PDF, image, and audio triage
## Related models
- [gpt-6-astra](/docs/models/gpt-6-astra) — OpenAI's frontier gpt-6 coding model
- [gemini-3.5-flash](/docs/models/gemini-3.5-flash) — faster, higher-quality flash
- [gemini-3.1-pro-preview](/docs/models/gemini-3.1-pro-preview) — the pro-tier model
---
# gemini-3.1-pro-preview — API, Pricing & Context Window | Vivgrid
> Source: https://vivgrid.com/docs/models/gemini-3.1-pro-preview
gemini-3.1-pro-preview on Vivgrid: Google's high-end multimodal coding model with a ~1M-token context window across text, image, video, audio and PDF.
`gemini-3.1-pro-preview` is Google's high-end Gemini model, positioned for coding and complex multimodal reasoning. It accepts **text, image, video, audio, and PDF** within a **~1.05M-token context window**.
On Vivgrid it runs as a globally centralized model. Because it relies on Google's global endpoint, regional acceleration is limited — but it remains available through the same unified API as the rest of the catalog.
## Ideal use cases
- Multimodal coding and reasoning agents
- Tasks blending long text with images, video, audio, or PDFs
- Large-context analysis up to ~1M tokens
- Workflows that benefit from Gemini's native multimodality
## Related models
- [gpt-6-astra](/docs/models/gpt-6-astra) — OpenAI's frontier gpt-6 coding model
- [gemini-3.5-flash](/docs/models/gemini-3.5-flash) — faster Gemini sibling
- [gemini-3-pro-preview](/docs/models/gemini-3-pro-preview) — the prior pro release
---
# gemini-3.5-flash — API, Pricing & Context Window | Vivgrid
> Source: https://vivgrid.com/docs/models/gemini-3.5-flash
gemini-3.5-flash on Vivgrid: Google's fast multimodal model with a 1M-token context window across text, image, video, audio and PDF.
`gemini-3.5-flash` is Google's fast, fully multimodal model, accepting **text, image, video, audio, and PDF** inputs within a **1M-token context window**. It's a strong agent model for workflows that mix media types at scale.
On Vivgrid, `gemini-3.5-flash` runs as a globally centralized model reachable through the same OpenAI-compatible endpoint and unified key as every other model in the catalog.
## Ideal use cases
- Multimodal agents combining video, audio, images, and PDFs
- Long-context understanding up to 1M tokens
- Fast, high-volume reasoning and summarization
- Media-heavy ingestion and analysis pipelines
## Related models
- [gpt-6-astra](/docs/models/gpt-6-astra) — OpenAI's frontier gpt-6 coding model
- [gemini-3.1-pro-preview](/docs/models/gemini-3.1-pro-preview) — higher-end Gemini for coding
- [gemini-3.6-flash](/docs/models/gemini-3.6-flash) — prior flash generation
---
# gemini-3.6-flash — API, Pricing & Context Window | Vivgrid
> Source: https://vivgrid.com/docs/models/gemini-3.6-flash
gemini-3.6-flash on Vivgrid: Google's fast agentic model with a 1M-token context window, tuned for coding loops and multi-step tool use.
`gemini-3.6-flash` is Google's fast Gemini model for the agentic era, built for code generation, multi-step orchestration, and spatial reasoning at flash speed. It keeps a **1M-token context window** and accepts **text, image, video, audio, and PDF** inputs, and is more token-efficient than `gemini-3.5-flash` — finishing comparable multi-step workflows in fewer turns.
On Vivgrid, `gemini-3.6-flash` runs as a globally centralized model reachable through the same OpenAI-compatible endpoint and unified key as every other model in the catalog.
The rates above are Google's introductory prices and apply **through December
31, 2026**. From January 1, 2027 the standard rates take effect: \$1.50 input,
\$0.15 cached input, and \$7.50 output per 1M tokens.
## Ideal use cases
- Rapid agentic loops with heavy tool calling
- Full-stack code generation and refactoring at low cost
- Long-context understanding up to 1M tokens
- High-volume multimodal reasoning and summarization
## Related models
- [gemini-3.8-flash](/docs/models/gemini-3.8-flash) — newest flash generation, 128K max output
- [gemini-3.7-flash](/docs/models/gemini-3.7-flash) — newer flash generation at the same price
- [gemini-3.1-pro-preview](/docs/models/gemini-3.1-pro-preview) — higher-end Gemini for coding
---
# gemini-3.7-flash — API, Pricing & Context Window | Vivgrid
> Source: https://vivgrid.com/docs/models/gemini-3.7-flash
gemini-3.7-flash on Vivgrid: Google's latest fast agentic model with a 1M-token context window, at introductory pricing through 2026.
`gemini-3.7-flash` is Google's latest fast Gemini model, built for agentic coding loops and multi-step tool use. It keeps a **1M-token context window** and accepts **text, image, video, audio, and PDF** inputs.
On Vivgrid, `gemini-3.7-flash` runs as a globally centralized model reachable through the same OpenAI-compatible endpoint and unified key as every other model in the catalog.
The rates above are Google's introductory prices and apply **through December
31, 2026**. From January 1, 2027 the standard rates take effect: \$1.50 input,
\$0.15 cached input, and \$7.50 output per 1M tokens.
## Ideal use cases
- Rapid agentic loops with heavy tool calling
- Full-stack code generation and refactoring at low cost
- Long-context understanding up to 1M tokens
- High-volume multimodal reasoning and summarization
## Related models
- [gemini-3.8-flash](/docs/models/gemini-3.8-flash) — newer flash generation, 128K max output
- [gemini-3.6-flash](/docs/models/gemini-3.6-flash) — prior flash generation
- [gemini-3.1-pro-preview](/docs/models/gemini-3.1-pro-preview) — higher-end Gemini for coding
---
# gemini-3.8-flash — API, Pricing & Context Window | Vivgrid
> Source: https://vivgrid.com/docs/models/gemini-3.8-flash
gemini-3.8-flash on Vivgrid: Google's newest fast agentic model with a 1M-token context window, 128K max output, and full text, image, video, audio, and PDF input.
`gemini-3.8-flash` is Google's newest fast Gemini model, built for agentic coding loops and multi-step tool use. It keeps the line's **1M-token context window**, doubles the max output to **128K tokens**, and accepts **text, image, video, audio, and PDF** inputs.
On Vivgrid, `gemini-3.8-flash` runs as a globally centralized model reachable through the same OpenAI-compatible endpoint and unified key as every other model in the catalog.
Input and output are priced identically to `gemini-3.7-flash` at **\$0.75 per 1M input tokens** and **\$3.75 per 1M output tokens**. Cached input is **\$0.15 per 1M** — twice `gemini-3.7-flash`'s introductory cached rate — so cache-heavy workloads should compare the two before switching.
## Ideal use cases
- Rapid agentic loops with heavy tool calling
- Long-form generation that needs more than a 64K output ceiling
- Long-context understanding up to 1M tokens
- High-volume multimodal reasoning and summarization
## Related models
- [gemini-3.7-flash](/docs/models/gemini-3.7-flash) — prior flash generation, cheaper cached input
- [gemini-3.1-pro-preview](/docs/models/gemini-3.1-pro-preview) — higher-end Gemini for coding
- [claude-fable-5-1](/docs/models/claude-fable-5-1) — Anthropic's most capable model
---
# glm-5.1 — API, Pricing & Context Window | Vivgrid
> Source: https://vivgrid.com/docs/models/glm-5.1
glm-5.1 on Vivgrid: Zhipu AI's capable coding model with a 200K context window, function calling, and competitive pricing.
`glm-5.1` is Zhipu AI's capable coding and reasoning model, offering a **200K-token context window** and reliable function calling at a competitive price. It's a strong open-weight-style option for agentic coding workloads.
On Vivgrid, `glm-5.1` is reachable through the unified, OpenAI-compatible endpoint, so it integrates cleanly alongside models from OpenAI, Anthropic, Google, and DeepSeek under one API key.
## Ideal use cases
- Cost-effective coding agents and CLIs
- Tool-calling workflows on Chat Completions
- General reasoning within a 200K-token context
- Teams diversifying beyond US-based providers
## Related models
- [gpt-6-astra](/docs/models/gpt-6-astra) — OpenAI's frontier gpt-6 coding model
- [glm-5.2](/docs/models/glm-5.2) — newer GLM with a 1M-token context window
- [deepseek-v4-pro](/docs/models/deepseek-v4-pro) — flagship low-cost coding model
---
# glm-5.2 — API, Pricing & Context Window | Vivgrid
> Source: https://vivgrid.com/docs/models/glm-5.2
glm-5.2 on Vivgrid: Zhipu AI's coding model with a 1M-token context window, function calling, and competitive pricing.
`glm-5.2` is Zhipu AI's latest coding and reasoning model, pairing reliable function calling with a major upgrade: a **1M-token context window**, up from 200K in `glm-5.1`. It's a strong, low-cost option for agentic coding workloads that need to reason over large codebases.
On Vivgrid, `glm-5.2` is reachable through the unified, OpenAI-compatible endpoint, so it integrates cleanly alongside models from OpenAI, Anthropic, Google, and DeepSeek under one API key.
## Ideal use cases
- Cost-effective coding agents and CLIs
- Whole-repository reasoning within a 1M-token context
- Tool-calling workflows on Chat Completions
- Teams diversifying beyond US-based providers
## Related models
- [gpt-6-astra](/docs/models/gpt-6-astra) — OpenAI's frontier gpt-6 coding model
- [glm-5.3](/docs/models/glm-5.3) — same base model and price, newer post-training
- [deepseek-v4-pro](/docs/models/deepseek-v4-pro) — flagship low-cost coding model
---
# glm-5.3-flash — API, Pricing & Context Window | Vivgrid
> Source: https://vivgrid.com/docs/models/glm-5.3-flash
glm-5.3-flash on Vivgrid: Zhipu AI's fast, low-cost multimodal model with image, video, and audio input, a 1M-token context window, and up to 384K output tokens.
`glm-5.3-flash` is Zhipu AI's lightweight sibling to `glm-5.3`. It trades the flagship's coding-benchmark tuning for speed and price, and adds image, video, and audio input — so the same request can reason over text alongside media. It keeps the line's **1M-token context window** and **384K-token max output**.
On Vivgrid, `glm-5.3-flash` is reachable through the unified, OpenAI-compatible endpoint, so it integrates cleanly alongside models from OpenAI, Anthropic, Google, and DeepSeek under one API key.
## Ideal use cases
- High-volume, cost-sensitive agent traffic that still needs tool calling
- Multimodal steps that mix text with image, video, or audio input
- Whole-repository reasoning within a 1M-token context at low cost
- Draft or first-pass generation ahead of a flagship model's final pass
## Related models
- [gpt-6-astra](/docs/models/gpt-6-astra) — OpenAI's frontier gpt-6 coding model
- [glm-5.3](/docs/models/glm-5.3) — the flagship, text-only coding model this is derived from
- [deepseek-v4-flash-vision-exp](/docs/models/deepseek-v4-flash-vision-exp) — alternative low-cost multimodal model
---
# glm-5.3 — API, Pricing & Context Window | Vivgrid
> Source: https://vivgrid.com/docs/models/glm-5.3
glm-5.3 on Vivgrid: Zhipu AI's coding and long-horizon agent model with a 1M-token context window, function calling, and competitive pricing.
`glm-5.3` is Zhipu AI's newest coding model. It keeps the `glm-5.2` base model and 1M-token context window, and puts its gains into post-training: better long-horizon agent behaviour, more reliable multi-step tool use, and stronger results on coding benchmarks — at the same price as `glm-5.2`.
On Vivgrid, `glm-5.3` is reachable through the unified, OpenAI-compatible endpoint, so it integrates cleanly alongside models from OpenAI, Anthropic, Google, and DeepSeek under one API key.
## Ideal use cases
- Long-horizon coding agents that chain many tool calls
- Whole-repository reasoning within a 1M-token context
- Cost-effective drop-in upgrade from `glm-5.2` at identical pricing
- Teams diversifying beyond US-based providers
## Related models
- [gpt-6-astra](/docs/models/gpt-6-astra) — OpenAI's frontier gpt-6 coding model
- [glm-5.2](/docs/models/glm-5.2) — same base model and price, prior post-training
- [kimi-k3](/docs/models/kimi-k3) — alternative frontier coding model with a 1M context
---
# gpt-4.1 — API, Pricing & Context Window | Vivgrid
> Source: https://vivgrid.com/docs/models/gpt-4.1
gpt-4.1 on Vivgrid: OpenAI's GPT-4.1 with a ~1M-token context window and image input, available through a single unified API.
`gpt-4.1` is OpenAI's refined GPT-4-generation model, notable for its very large **~1.05M-token context window** and strong instruction following. It remains a dependable choice for long-document workflows and established integrations.
Vivgrid serves `gpt-4.1` through its unified, OpenAI-compatible endpoint, so you can keep proven prompts running while routing through one API key and billing surface.
## Ideal use cases
- Long-document analysis and summarization
- Stable production integrations built on GPT-4.x
- Instruction-following and structured extraction
- Workloads needing a very large context at GPT-4 pricing
## Related models
- [gpt-6-astra](/docs/models/gpt-6-astra) — the gpt-6 generation flagship
- [gpt-5.6-terra](/docs/models/gpt-5.6-terra) — current balanced GPT model
- [gpt-5.6-luna](/docs/models/gpt-5.6-luna) — cheaper modern alternative
---
# gpt-4o — API, Pricing & Context Window | Vivgrid
> Source: https://vivgrid.com/docs/models/gpt-4o
gpt-4o on Vivgrid: OpenAI's multimodal GPT-4o with a 128K context window and image input, accessible through one unified API key.
`gpt-4o` is OpenAI's widely adopted multimodal GPT-4-class model, balancing quality, speed, and cost across text and image inputs. With a **128K-token context window**, it powers a huge range of production assistants.
On Vivgrid, `gpt-4o` is available through the same OpenAI-compatible endpoint as newer models, making it easy to keep existing apps running or migrate gradually to GPT-5.
## Ideal use cases
- Established multimodal chat and assistant apps
- Text and image understanding tasks
- Broadly compatible production workloads
- A baseline for comparing against newer GPT-5 models
## Related models
- [gpt-6-astra](/docs/models/gpt-6-astra) — the gpt-6 generation flagship
- [gpt-5.6-terra](/docs/models/gpt-5.6-terra) — refined current-generation model
- [gpt-5.6-luna](/docs/models/gpt-5.6-luna) — low-cost modern alternative
---
# gpt-5-chat — API, Pricing & Context Window | Vivgrid
> Source: https://vivgrid.com/docs/models/gpt-5-chat
gpt-5-chat on Vivgrid: a conversation-tuned GPT-5 model with a 128K context window and image input, accessed through one unified API.
`gpt-5-chat` is the conversation-optimized variant of GPT-5, tuned for natural, helpful multi-turn dialogue. With a **128K-token context window** and image input, it's a good fit for product chatbots and assistant experiences.
On Vivgrid, `gpt-5-chat` is available through the same OpenAI-compatible endpoint and unified API key as every other model, so you can A/B it against alternatives without code changes.
## Ideal use cases
- Customer-facing chat assistants
- Conversational product experiences
- Multi-turn support and Q&A bots
- Scenarios prioritizing fluent dialogue over deep tool use
## Related models
- [gpt-6-astra](/docs/models/gpt-6-astra) — the gpt-6 generation flagship
- [gpt-5.6-luna](/docs/models/gpt-5.6-luna) — smaller, faster sibling
- [gpt-5.5](/docs/models/gpt-5.5) — newer general-purpose model
---
# gpt-5-mini — API, Pricing & Context Window | Vivgrid
> Source: https://vivgrid.com/docs/models/gpt-5-mini
gpt-5-mini on Vivgrid: a fast, affordable GPT-5 model with a 272K context window, function calling, and three-region acceleration.
`gpt-5-mini` is the compact, budget-friendly member of the GPT-5 family. It keeps a **272K-token context window** and function-calling support while delivering faster responses at a fraction of the flagship price.
Vivgrid geo-distributes `gpt-5-mini` across **AMER, EMEA, and APAC**, making it ideal for high-volume, latency-sensitive traffic anywhere in the world.
## Ideal use cases
- High-throughput chat and agent backends
- Classification, extraction, and routing
- Cost-conscious tool-calling workflows
- Edge cases where latency beats maximum quality
## Related models
- [gpt-6-astra](/docs/models/gpt-6-astra) — the gpt-6 generation flagship
- [gpt-5.6-luna](/docs/models/gpt-5.6-luna) — newer-generation mini
- [gpt-5.6-terra](/docs/models/gpt-5.6-terra) — balanced current-generation model
---
# gpt-5.1-codex-max — API, Pricing & Context Window | Vivgrid
> Source: https://vivgrid.com/docs/models/gpt-5.1-codex-max
gpt-5.1-codex-max on Vivgrid: an extended-effort Codex coding model on the Responses API with a 400K context window and geo-distributed acceleration.
`gpt-5.1-codex-max` is the extended-effort variant of OpenAI's Codex 5.1 line, tuned to push harder on difficult, long-horizon coding problems. It runs on the **Responses API** and is a good fit when you want maximum reasoning depth from the 5.1 Codex generation.
On Vivgrid it offers a **400K-token context window** and geo-distributed acceleration across **AMER and EMEA**, balancing depth with responsive latency.
## Ideal use cases
- Hard, multi-file engineering tasks needing extra reasoning effort
- Codex agents tackling complex debugging and architecture changes
- Long agent loops where thoroughness matters more than raw speed
- Responses-API tooling that wants the strongest 5.1 Codex option
## Related models
- [gpt-6-astra](/docs/models/gpt-6-astra) — the gpt-6 generation flagship
- [gpt-5.6-sol](/docs/models/gpt-5.6-sol) — flagship coding model
- [gpt-5.3-codex](/docs/models/gpt-5.3-codex) — newer Codex generation
---
# gpt-5.1-codex — API, Pricing & Context Window | Vivgrid
> Source: https://vivgrid.com/docs/models/gpt-5.1-codex
gpt-5.1-codex on Vivgrid: a Codex-tuned coding model on the Responses API with a 400K context window and three-region geo-distributed acceleration.
`gpt-5.1-codex` is OpenAI's Codex-tuned 5.1 coding model, designed for agentic software engineering through the **Responses API**. It is a well-rounded, cost-effective option for everyday coding agents.
Vivgrid accelerates `gpt-5.1-codex` across **AMER, EMEA, and APAC** — the broadest reach in the Codex line — with a **400K-token context window** for project-scale sessions.
## Ideal use cases
- Day-to-day coding agents on the Responses API
- Globally distributed teams needing low latency in three regions
- Automated edits, reviews, and test generation
- Tool-calling workflows that chain editor and shell actions
## Related models
- [gpt-6-astra](/docs/models/gpt-6-astra) — the gpt-6 generation flagship
- [gpt-5.3-codex](/docs/models/gpt-5.3-codex) — the current Codex generation
- [gpt-5.6-sol](/docs/models/gpt-5.6-sol) — flagship coding model
---
# gpt-5.1 — API, Pricing & Context Window | Vivgrid
> Source: https://vivgrid.com/docs/models/gpt-5.1
gpt-5.1 on Vivgrid: a general-purpose GPT-5 model with a 272K context window, text, image and audio input, and regional acceleration.
`gpt-5.1` is a versatile GPT-5 generation model with a **272K-token context window** and support for text, image, and audio inputs. It's a balanced option for agents and assistants that need solid reasoning without flagship pricing.
Vivgrid accelerates `gpt-5.1` across **AMER and EMEA** and exposes it through the same OpenAI-compatible endpoint used by every model in the catalog.
## Ideal use cases
- Multimodal assistants handling text, image, and audio
- General reasoning and conversation
- Function-calling agents at moderate cost
- Workloads upgrading from `gpt-5`
## Related models
- [gpt-6-astra](/docs/models/gpt-6-astra) — the gpt-6 generation flagship
- [gpt-5.5](/docs/models/gpt-5.5) — the flagship GPT-5 model
- [gpt-5.3-codex](/docs/models/gpt-5.3-codex) — Codex-tuned model for coding
---
# gpt-5.2-codex — API, Pricing & Context Window | Vivgrid
> Source: https://vivgrid.com/docs/models/gpt-5.2-codex
gpt-5.2-codex on Vivgrid: a Codex-tuned coding model on the Responses API with a 400K context window, function calling, and regional acceleration.
`gpt-5.2-codex` is a Codex-tuned member of the GPT-5 family, built for agentic coding on OpenAI's **Responses API**. It is a dependable choice for software-engineering agents that read, edit, and test code in a loop.
Vivgrid serves `gpt-5.2-codex` with geo-distributed acceleration across **AMER and EMEA** and a **400K-token context window**, so it can hold substantial project context within a single session.
## Ideal use cases
- Codex and Responses-API coding assistants
- Automated refactoring, test generation, and bug fixing
- Tool-calling agents that orchestrate shell and editor actions
- Cost-aware coding workloads that don't need the latest Codex release
## Related models
- [gpt-6-astra](/docs/models/gpt-6-astra) — the gpt-6 generation flagship
- [gpt-5.3-codex](/docs/models/gpt-5.3-codex) — the newer Codex generation
- [gpt-5.6-sol](/docs/models/gpt-5.6-sol) — flagship coding alternative
---
# gpt-5.2 — API, Pricing & Context Window | Vivgrid
> Source: https://vivgrid.com/docs/models/gpt-5.2
gpt-5.2 on Vivgrid: a capable general-purpose GPT-5 model with a 400K context window, function calling, and geo-distributed acceleration.
`gpt-5.2` is a strong general-purpose model from the GPT-5 generation, suited to reasoning, writing, and agent workloads on the Chat Completions API. With a **400K-token context window** it handles long documents and multi-turn agent state with ease.
On Vivgrid, `gpt-5.2` is geo-distributed across **AMER and EMEA** and reachable through the same unified API key as the rest of the catalog.
## Ideal use cases
- General-purpose agents and assistants
- Long-form reasoning, analysis, and content generation
- Function-calling workflows on Chat Completions
- Drop-in upgrade path from earlier GPT-5 models
## Related models
- [gpt-6-astra](/docs/models/gpt-6-astra) — the gpt-6 generation flagship
- [gpt-5.5](/docs/models/gpt-5.5) — the flagship 5.x release
- [gpt-5.6-terra](/docs/models/gpt-5.6-terra) — balanced current-generation model
---
# gpt-5.3-codex — API, Pricing & Context Window | Vivgrid
> Source: https://vivgrid.com/docs/models/gpt-5.3-codex
gpt-5.3-codex on Vivgrid: OpenAI's Codex-tuned coding model on the Responses API, with a 400K context window and geo-distributed acceleration.
`gpt-5.3-codex` is OpenAI's Codex-optimized coding model, tuned for agentic software engineering: editing files, running tools, and iterating in a loop. It is served on the **Responses API** (`/responses`), the surface that Codex and similar coding CLIs expect.
With a **400K-token context window** and geo-distributed acceleration across **AMER and EMEA**, it delivers low-latency, long-horizon coding sessions on Vivgrid through a single API key.
## Ideal use cases
- Codex CLI and other Responses-API coding agents
- Iterative, tool-driven software engineering tasks
- Repository-scale edits within a 400K-token budget
- Pipelines that benefit from streamed, incremental output
## Related models
- [gpt-6-astra](/docs/models/gpt-6-astra) — the gpt-6 generation flagship
- [gpt-5.6-sol](/docs/models/gpt-5.6-sol) — the newer, flagship Codex-capable model
- [gpt-5.5](/docs/models/gpt-5.5) — flagship model on the Chat Completions API
---
# gpt-5.4-mini — API, Pricing & Context Window | Vivgrid
> Source: https://vivgrid.com/docs/models/gpt-5.4-mini
gpt-5.4-mini on Vivgrid: a fast, low-cost GPT-5.4 model with a 400K context window, PDF and image input, and three-region acceleration.
`gpt-5.4-mini` is the cost-efficient sibling of `gpt-5.4`, tuned for high-throughput workloads where speed and price matter more than maximum reasoning depth. It still offers a generous **400K-token context window** plus image and PDF input.
On Vivgrid it is geo-distributed across **AMER, EMEA, and APAC**, making it a strong default for latency-sensitive, high-volume agent traffic worldwide.
## Ideal use cases
- High-volume agents and chat backends with tight cost budgets
- Document understanding over PDFs and images
- Classification, extraction, and routing tasks
- Real-time experiences where latency is critical
## Related models
- [gpt-6-astra](/docs/models/gpt-6-astra) — the gpt-6 generation flagship
- [gpt-5.6-luna](/docs/models/gpt-5.6-luna) — the smallest, cheapest current tier
- [gemini-3.1-flash-lite-preview](/docs/models/gemini-3.1-flash-lite-preview) — ultra-low-cost cross-provider option
---
# gpt-5.4-nano — API, Pricing & Context Window | Vivgrid
> Source: https://vivgrid.com/docs/models/gpt-5.4-nano
gpt-5.4-nano on Vivgrid: the smallest, most economical GPT-5.4 model with a 400K context window and image and PDF input for high-scale tasks.
`gpt-5.4-nano` is the smallest and most economical model in the GPT-5.4 family, built for massive-scale, latency-sensitive workloads. Despite its size it keeps a **400K-token context window** and supports image and PDF inputs.
Vivgrid serves it with geo-distributed acceleration across **AMER and EMEA**, so even the highest-volume pipelines stay fast and affordable.
## Ideal use cases
- Very high-volume classification, tagging, and routing
- Lightweight assistants and autocomplete-style features
- Cost-sensitive preprocessing in larger agent pipelines
- Bulk document and image triage
## Related models
- [gpt-6-astra](/docs/models/gpt-6-astra) — the gpt-6 generation flagship
- [gpt-5.6-luna](/docs/models/gpt-5.6-luna) — a step up in current-generation quality
- [gemini-3.1-flash-lite-preview](/docs/models/gemini-3.1-flash-lite-preview) — ultra-low-cost cross-provider option
---
# gpt-5.4 — API, Pricing & Context Window | Vivgrid
> Source: https://vivgrid.com/docs/models/gpt-5.4
Use OpenAI's gpt-5.4 on Vivgrid: a 1.05M-token coding model with broad three-region acceleration (AMER, EMEA, APAC) and a unified, OpenAI-compatible API.
`gpt-5.4` is a high-capability OpenAI coding model that balances frontier-level quality with a more accessible price than `gpt-5.5`. Its **1.05M-token context window** comfortably holds large codebases, design docs, and long agent histories.
On Vivgrid it has the **widest acceleration footprint** of the GPT-5 family — geo-distributed across **AMER, EMEA, and APAC** — making it a strong default for globally distributed teams and agents.
## Ideal use cases
- Production coding agents that need frontier quality at moderate cost
- Teams with users across the Americas, Europe, and Asia-Pacific
- Long-context analysis and refactoring of large repositories
- Tool-calling agents requiring reliable, structured outputs
## Related models
- [gpt-6-astra](/docs/models/gpt-6-astra) — the gpt-6 generation flagship
- [gpt-5.6-luna](/docs/models/gpt-5.6-luna) — a faster, cheaper current-generation sibling
- [gpt-5.3-codex](/docs/models/gpt-5.3-codex) — Codex-tuned current-generation model
---
# gpt-5.5 — API, Pricing & Context Window | Vivgrid
> Source: https://vivgrid.com/docs/models/gpt-5.5
Run OpenAI's gpt-5.5 on Vivgrid: a 1.05M-token flagship coding model for agents and CLIs, with geo-distributed acceleration and a unified API.
`gpt-5.5` is OpenAI's flagship model and Vivgrid's top recommendation for coding agents. It pairs a **1.05M-token context window** with strong multi-step reasoning, making it well suited for whole-repository refactors, long agent traces, and complex tool-calling workflows.
On Vivgrid, `gpt-5.5` is served through a single OpenAI-compatible endpoint with **geo-distributed acceleration across AMER and EMEA**, so requests are routed to the nearest compute region for lower latency. You can switch your agent to `gpt-5.5` from the Console without changing a line of application code.
## Ideal use cases
- Autonomous coding agents and CLI tools (Codex, OpenCode, Claude Code-style flows)
- Large-context tasks: reading and editing entire codebases in one pass
- High-stakes reasoning where output quality outweighs token cost
- Multi-tool agents that chain function calls across long sessions
## Related models
- [gpt-6-astra](/docs/models/gpt-6-astra) — the gpt-6 generation flagship
- [gpt-5.4](/docs/models/gpt-5.4) — the prior flagship at a lower price point
- [gpt-5.3-codex](/docs/models/gpt-5.3-codex) — Codex-tuned variant on the Responses API
---
# gpt-5.6-luna — API, Pricing & Context Window | Vivgrid
> Source: https://vivgrid.com/docs/models/gpt-5.6-luna
gpt-5.6-luna on Vivgrid: OpenAI's fast, low-cost gpt-5.6 model with a 1.05M-token context window for high-volume agent workloads.
`gpt-5.6-luna` is the fast, low-cost model in OpenAI's gpt-5.6 family. Unlike earlier small models, it keeps the family's **1.05M-token context window**, making it the cheapest way to run long-context agents at scale.
On Vivgrid, `gpt-5.6-luna` is served through a single OpenAI-compatible endpoint with **geo-distributed acceleration across AMER and EMEA**, reachable with the same unified key as the rest of the catalog.
Requests beyond **272K input tokens** are billed at the long-context rate: $2.00 input / $0.20 cached input / $9.00 output per 1M tokens.
## Ideal use cases
- High-volume agent and content pipelines where cost dominates
- Long-context retrieval, summarization, and classification
- Fast interactive assistants and chat products
- Fallback or draft model alongside gpt-5.6-sol / terra
## Related models
- [gpt-6-astra](/docs/models/gpt-6-astra) — the gpt-6 generation flagship
- [gpt-5.6-terra](/docs/models/gpt-5.6-terra) — the balanced gpt-5.6 model
- [gpt-5.6-sol](/docs/models/gpt-5.6-sol) — the flagship gpt-5.6 model
---
# gpt-5.6-sol — API, Pricing & Context Window | Vivgrid
> Source: https://vivgrid.com/docs/models/gpt-5.6-sol
Run OpenAI's gpt-5.6-sol on Vivgrid: the flagship gpt-5.6 coding model with a 1.05M-token context window, geo-distributed acceleration, and a unified API.
`gpt-5.6-sol` is the flagship of OpenAI's gpt-5.6 family and the successor to `gpt-5.5`. It pairs a **1.05M-token context window** with frontier multi-step reasoning, built for whole-repository refactors, long agent traces, and complex tool-calling workflows.
On Vivgrid, `gpt-5.6-sol` is served through a single OpenAI-compatible endpoint with **geo-distributed acceleration across AMER and EMEA**, so requests are routed to the nearest compute region for lower latency. You can switch your agent to `gpt-5.6-sol` from the Console without changing a line of application code.
Requests beyond **272K input tokens** are billed at the long-context rate: $10.00 input / $1.00 cached input / $45.00 output per 1M tokens.
## Ideal use cases
- Autonomous coding agents and CLI tools (Codex, OpenCode, Claude Code-style flows)
- Large-context tasks: reading and editing entire codebases in one pass
- High-stakes reasoning where output quality outweighs token cost
- Multi-tool agents that chain function calls across long sessions
## Related models
- [gpt-6-astra](/docs/models/gpt-6-astra) — the gpt-6 generation flagship
- [gpt-5.6-terra](/docs/models/gpt-5.6-terra) — the balanced gpt-5.6 model at half the price
- [gpt-5.6-luna](/docs/models/gpt-5.6-luna) — the fast, low-cost gpt-5.6 model
---
# gpt-5.6-terra — API, Pricing & Context Window | Vivgrid
> Source: https://vivgrid.com/docs/models/gpt-5.6-terra
gpt-5.6-terra on Vivgrid: OpenAI's balanced gpt-5.6 model with a 1.05M-token context window, strong coding performance, and geo-distributed acceleration.
`gpt-5.6-terra` is the balanced model in OpenAI's gpt-5.6 family and the successor to `gpt-5.4`, delivering most of `gpt-5.6-sol`'s coding and reasoning quality at half the price. Its **1.05M-token context window** makes it a strong default for production agents.
On Vivgrid, `gpt-5.6-terra` is served through a single OpenAI-compatible endpoint with **geo-distributed acceleration across AMER and EMEA**, reachable with the same unified key as the rest of the catalog.
Requests beyond **272K input tokens** are billed at the long-context rate: $5.00 input / $0.50 cached input / $22.50 output per 1M tokens.
## Ideal use cases
- Production coding agents balancing quality, speed, and cost
- Whole-repository analysis within a 1.05M-token context
- High-volume tool-calling workflows on Chat Completions
- Teams standardizing on one model across coding and agent tasks
## Related models
- [gpt-6-astra](/docs/models/gpt-6-astra) — the gpt-6 generation flagship
- [gpt-5.6-sol](/docs/models/gpt-5.6-sol) — the flagship gpt-5.6 model
- [gpt-5.6-luna](/docs/models/gpt-5.6-luna) — the fast, low-cost gpt-5.6 model
---
# gpt-5 — API, Pricing & Context Window | Vivgrid
> Source: https://vivgrid.com/docs/models/gpt-5
gpt-5 on Vivgrid: OpenAI's GPT-5 model with a 272K context window, function calling, and three-region geo-distributed acceleration.
`gpt-5` is OpenAI's foundational GPT-5 model, a reliable all-rounder for reasoning, coding assistance, and agent workloads. Its **272K-token context window** covers most long-context needs, and it supports robust function calling.
On Vivgrid, `gpt-5` enjoys one of the widest acceleration footprints — geo-distributed across **AMER, EMEA, and APAC** — for consistently low latency worldwide.
## Ideal use cases
- General-purpose agents and chat assistants
- Tool-calling workflows that need dependable structured output
- Globally distributed deployments
- A stable baseline before adopting newer 5.x models
## Related models
- [gpt-6-astra](/docs/models/gpt-6-astra) — the gpt-6 generation flagship
- [gpt-5.5](/docs/models/gpt-5.5) — the current flagship with more capability
- [gpt-5.6-luna](/docs/models/gpt-5.6-luna) — smaller, cheaper sibling
---
# gpt-6-astra — API, Pricing & Context Window | Vivgrid
> Source: https://vivgrid.com/docs/models/gpt-6-astra
Run OpenAI's gpt-6-astra on Vivgrid: the flagship gpt-6 coding model with a 1.05M-token context window, geo-distributed acceleration, and a unified API.
`gpt-6-astra` opens OpenAI's gpt-6 generation and succeeds `gpt-5.6-sol`. It pairs a **1.05M-token context window** with a step up in multi-step reasoning and tool use, built for whole-repository refactors, long-running agents, and workflows where output quality outweighs token cost.
On Vivgrid, `gpt-6-astra` is served through a single OpenAI-compatible endpoint with **geo-distributed acceleration across AMER, EMEA, and APAC**, so requests are routed to the nearest compute region for lower latency. You can switch your agent to `gpt-6-astra` from the Console without changing a line of application code.
It is available on both OpenAI surfaces — **Chat Completions** (`/chat/completions`) and the **Responses API** (`/responses`) — so coding CLIs that expect the Responses wire format, such as [Codex](/docs/tutorials/codex) and [Pi](/docs/tutorials/pi), work against the same key.
Prompt caching is billed at **$12.50 per 1M cache-write tokens**, with cached reads at $1.00.
Requests beyond **272K input tokens** are billed at the long-context rate: $20.00 input / $2.00 cached input / $25.00 cache write / $75.00 output per 1M tokens.
## Ideal use cases
- Frontier coding agents and CLI tools (Codex, OpenCode, Claude Code-style flows)
- Whole-codebase reads and edits in a single 1.05M-token pass
- High-stakes reasoning where answer quality outweighs token cost
- Long agent traces that chain many tool calls across a session
## Related models
- [gpt-5.6-sol](/docs/models/gpt-5.6-sol) — the prior-generation flagship at half the price
- [gpt-5.6-terra](/docs/models/gpt-5.6-terra) — the balanced gpt-5.6 model
- [claude-fable-5-1](/docs/models/claude-fable-5-1) — Anthropic's most capable model
---
# grok-4-1-fast-non-reasoning — API, Pricing & Context Window | Vivgrid
> Source: https://vivgrid.com/docs/models/grok-4-1-fast-non-reasoning
grok-4-1-fast-non-reasoning on Vivgrid: xAI's low-latency model with a 2M-token context window and image input, via one unified API.
`grok-4-1-fast-non-reasoning` is the low-latency variant of xAI's Grok 4.1 fast line, optimized for quick responses without extended reasoning. It keeps the same massive **2M-token context window** and image input, prioritizing speed for high-throughput workloads.
Vivgrid serves `grok-4-1-fast-non-reasoning` through its unified, OpenAI-compatible API and single billing surface.
## Ideal use cases
- Latency-sensitive, high-volume traffic
- Large-context retrieval and summarization (up to 2M tokens)
- Fast classification and extraction
- Workloads where speed beats deep reasoning
## Related models
- [gpt-6-astra](/docs/models/gpt-6-astra) — OpenAI's frontier gpt-6 coding model
- [deepseek-v4-flash](/docs/models/deepseek-v4-flash) — reasoning-capable alternative
- [gemini-3.7-flash](/docs/models/gemini-3.7-flash) — large-context flash model
---
# grok-4-1-fast-reasoning — API, Pricing & Context Window | Vivgrid
> Source: https://vivgrid.com/docs/models/grok-4-1-fast-reasoning
grok-4-1-fast-reasoning on Vivgrid: xAI's fast reasoning model with a 2M-token context window and image input, via one unified API.
`grok-4-1-fast-reasoning` is xAI's fast reasoning model, pairing an enormous **2M-token context window** with image input and an emphasis on quick, structured problem solving. The large context makes it well suited to sprawling documents and long agent histories.
On Vivgrid, `grok-4-1-fast-reasoning` is available through the unified, OpenAI-compatible API, so xAI slots into multi-provider agent stacks with a single key.
## Ideal use cases
- Reasoning over very large contexts (up to 2M tokens)
- Analytical and multi-step problem solving
- Agents ingesting large document sets
- Mixed text-and-image reasoning tasks
## Related models
- [gpt-6-astra](/docs/models/gpt-6-astra) — OpenAI's frontier gpt-6 coding model
- [deepseek-v4-flash](/docs/models/deepseek-v4-flash) — reasoning-capable alternative
- [gemini-3.7-flash](/docs/models/gemini-3.7-flash) — large-context flash model
---
# kimi-k2.6 — API, Pricing & Context Window | Vivgrid
> Source: https://vivgrid.com/docs/models/kimi-k2.6
kimi-k2.6 on Vivgrid: Moonshot AI's coding model with a 262K context window, up to 256K output tokens, and function calling.
`kimi-k2.6` is Moonshot AI's capable coding model, notable for a **262K-token context window** paired with an exceptionally large **256K-token max output**. That combination suits agents that both read and generate large volumes of code.
Vivgrid serves `kimi-k2.6` through its unified, OpenAI-compatible API, letting you route Moonshot alongside other providers with a single key and billing surface.
## Ideal use cases
- Coding agents that produce large outputs
- Long-context engineering and refactoring tasks
- Tool-calling workflows on Chat Completions
- Cost-effective alternative to frontier coding models
## Related models
- [gpt-6-astra](/docs/models/gpt-6-astra) — OpenAI's frontier gpt-6 coding model
- [kimi-k3](/docs/models/kimi-k3) — the next-generation Moonshot coding model
- [minimax-m3](/docs/models/minimax-m3) — high-context coding option
---
# kimi-k3 — API, Pricing & Context Window | Vivgrid
> Source: https://vivgrid.com/docs/models/kimi-k3
Run Moonshot AI's kimi-k3 on Vivgrid: a frontier coding model with a 1M-token context window, 128K max output, tool calling, and an OpenAI-compatible API.
`kimi-k3` is Moonshot AI's frontier model for coding, reasoning, and agentic workflows. It expands the Kimi family to a **1M-token context window** with up to **128K output tokens**, allowing agents to reason over large repositories and complete substantial engineering tasks in a single run.
Vivgrid exposes `kimi-k3` through the unified, **OpenAI-compatible Chat Completions API** (`/chat/completions`). You can use the same API key, client libraries, billing, and observability as the rest of the Vivgrid model catalog.
## Ideal use cases
- Long-context coding agents and repository-scale refactoring
- Complex software engineering, debugging, and code review
- Tool-calling agents that need dependable multi-step reasoning
- Teams seeking a high-capability alternative to frontier US models
## Related models
- [gpt-6-astra](/docs/models/gpt-6-astra) — OpenAI's frontier gpt-6 coding model
- [minimax-m3](/docs/models/minimax-m3) — a lower-cost coding alternative
- [claude-opus-5](/docs/models/claude-opus-5) — Anthropic's flagship coding model
---
# llama3.1-8b — API, Pricing & Context Window | Vivgrid
> Source: https://vivgrid.com/docs/models/llama3.1-8b
llama3.1-8b on Vivgrid: Meta's efficient 8B open model with a 128K context window, available through one unified API.
`llama3.1-8b` is Meta's efficient 8-billion-parameter open model, offering a **128K-token context window** and dependable performance for lightweight tasks. Its small size makes it fast and inexpensive for high-volume workloads.
On Vivgrid, `llama3.1-8b` is available through the unified, OpenAI-compatible API, providing an open-model option alongside the catalog's commercial models under a single key.
## Ideal use cases
- Lightweight, high-volume text tasks
- Cost-sensitive classification and extraction
- Simple assistants and autocomplete features
- An open-model baseline for evaluation
## Related models
- [gpt-6-astra](/docs/models/gpt-6-astra) — OpenAI's frontier gpt-6 coding model
- [deepseek-v4-flash](/docs/models/deepseek-v4-flash) — ultra-affordable option
- [gemini-3.1-flash-lite-preview](/docs/models/gemini-3.1-flash-lite-preview) — efficient multimodal option
---
# minimax-m2.7 — API, Pricing & Context Window | Vivgrid
> Source: https://vivgrid.com/docs/models/minimax-m2.7
minimax-m2.7 on Vivgrid: MiniMax's affordable coding model with a 205K context window, 131K max output, and APAC acceleration.
`minimax-m2.7` is MiniMax's affordable coding model, offering a **205K-token context window** and **131K-token max output** at some of the lowest prices in the catalog. It's well suited to high-volume coding and reasoning on a tight budget.
Vivgrid serves `minimax-m2.7` through its unified, OpenAI-compatible API with **APAC acceleration**, ideal for Asia-Pacific teams.
## Ideal use cases
- Budget-focused coding agents
- High-volume code generation and review
- APAC deployments needing low latency
- Cost-efficient steps in larger pipelines
## Related models
- [gpt-6-astra](/docs/models/gpt-6-astra) — OpenAI's frontier gpt-6 coding model
- [minimax-m3](/docs/models/minimax-m3) — the newer MiniMax generation
- [deepseek-v4-flash](/docs/models/deepseek-v4-flash) — ultra-affordable option
---
# minimax-m3 — API, Pricing & Context Window | Vivgrid
> Source: https://vivgrid.com/docs/models/minimax-m3
minimax-m3 on Vivgrid: MiniMax's efficient coding model with a 512K context window, 128K max output, and very competitive pricing.
`minimax-m3` is MiniMax's efficient coding model, combining a large **512K-token context window** with **128K-token max output** and very competitive token pricing. It's a strong value pick for long-context coding agents.
On Vivgrid, `minimax-m3` is available through the unified, OpenAI-compatible endpoint and is accelerated in **APAC**, making it especially attractive for Asia-Pacific deployments.
## Ideal use cases
- Long-context coding agents on a budget
- APAC-based deployments needing low latency
- Tasks generating substantial code output
- High-volume engineering workloads
## Related models
- [gpt-6-astra](/docs/models/gpt-6-astra) — OpenAI's frontier gpt-6 coding model
- [minimax-m2.7](/docs/models/minimax-m2.7) — the prior MiniMax generation
- [kimi-k3](/docs/models/kimi-k3) — frontier Moonshot coding model
---
# Claude Code × Vivgrid
> Source: https://vivgrid.com/docs/tutorials/claude-code
How to use Vivgrid with Claude Fabel 5.1, Claude Opus 5 in Claude Code
## Configure Claude Code to Use Vivgrid (Claude Fabel 5.1, Claude Opus 5)
First, you need to get your Vivgrid API Key from your [Vivgrid Console](https://console.vivgrid.com).
Then, copy the following configuration files to your claude code config file `~/.claude/settings.json`.
```json ~/.claude/settings.json lines icon="json"
{
"env": {
"CLAUDE_CODE_ENABLE_TELEMETRY": "0",
"OTEL_METRICS_EXPORTER": "otlp",
"CLAUDE_CODE_DISABLE_1M_CONTEXT": "1",
"MAX_CONSECUTIVE_AUTOCOMPACT_FAILURES": "3",
"DISABLE_EXTRA_USAGE_COMMAND": "1",
"DISABLE_FEEDBACK_COMMAND": "1",
"ENABLE_TOOL_SEARCH": "true",
"CLAUDE_CODE_ATTRIBUTION_HEADER": "0",
"CLAUDE_CODE_DISABLE_TERMINAL_TITLE": "1",
"ANTHROPIC_AUTH_TOKEN": "{YOUR_VIVGRID_KEY}",
"ANTHROPIC_BASE_URL": "https://api.vivgrid.com/",
"ANTHROPIC_DEFAULT_HAIKU_MODEL": "claude-sonnet-5",
"ANTHROPIC_DEFAULT_OPUS_MODEL": "claude-fable-5-1",
"ANTHROPIC_DEFAULT_SONNET_MODEL": "claude-opus-5",
"ANTHROPIC_MODEL": "opus",
"CLAUDE_CODE_DISABLE_NONESSENTIAL_TRAFFIC": "1",
"CLAUDE_CODE_DISABLE_EXPERIMENTAL_BETAS": "1"
}
}
```
## Start Using Claude Code with Vivgrid
```bash
claude
```
---
# OpenClaw × Vivgrid
> Source: https://vivgrid.com/docs/tutorials/clawdbot
How to configure OpenClaw to use advanced LLMs through Vivgrid's unified model gateway
## Configure OpenClaw to Use Vivgrid
By configuring OpenClaw to use Vivgrid as its model provider, you can access advanced LLMs through a single, stable endpoint.
Vivgrid acts as an LLM gateway that manages model selection, upgrades, and routing, so OpenClaw is not tied to a specific model or vendor.
First, open the [Vivgrid Console](https://console.vivgrid.com), create a new project, and select `OpenClaw Model`:
After creating the project, go to `API Endpoint` and copy your API key.
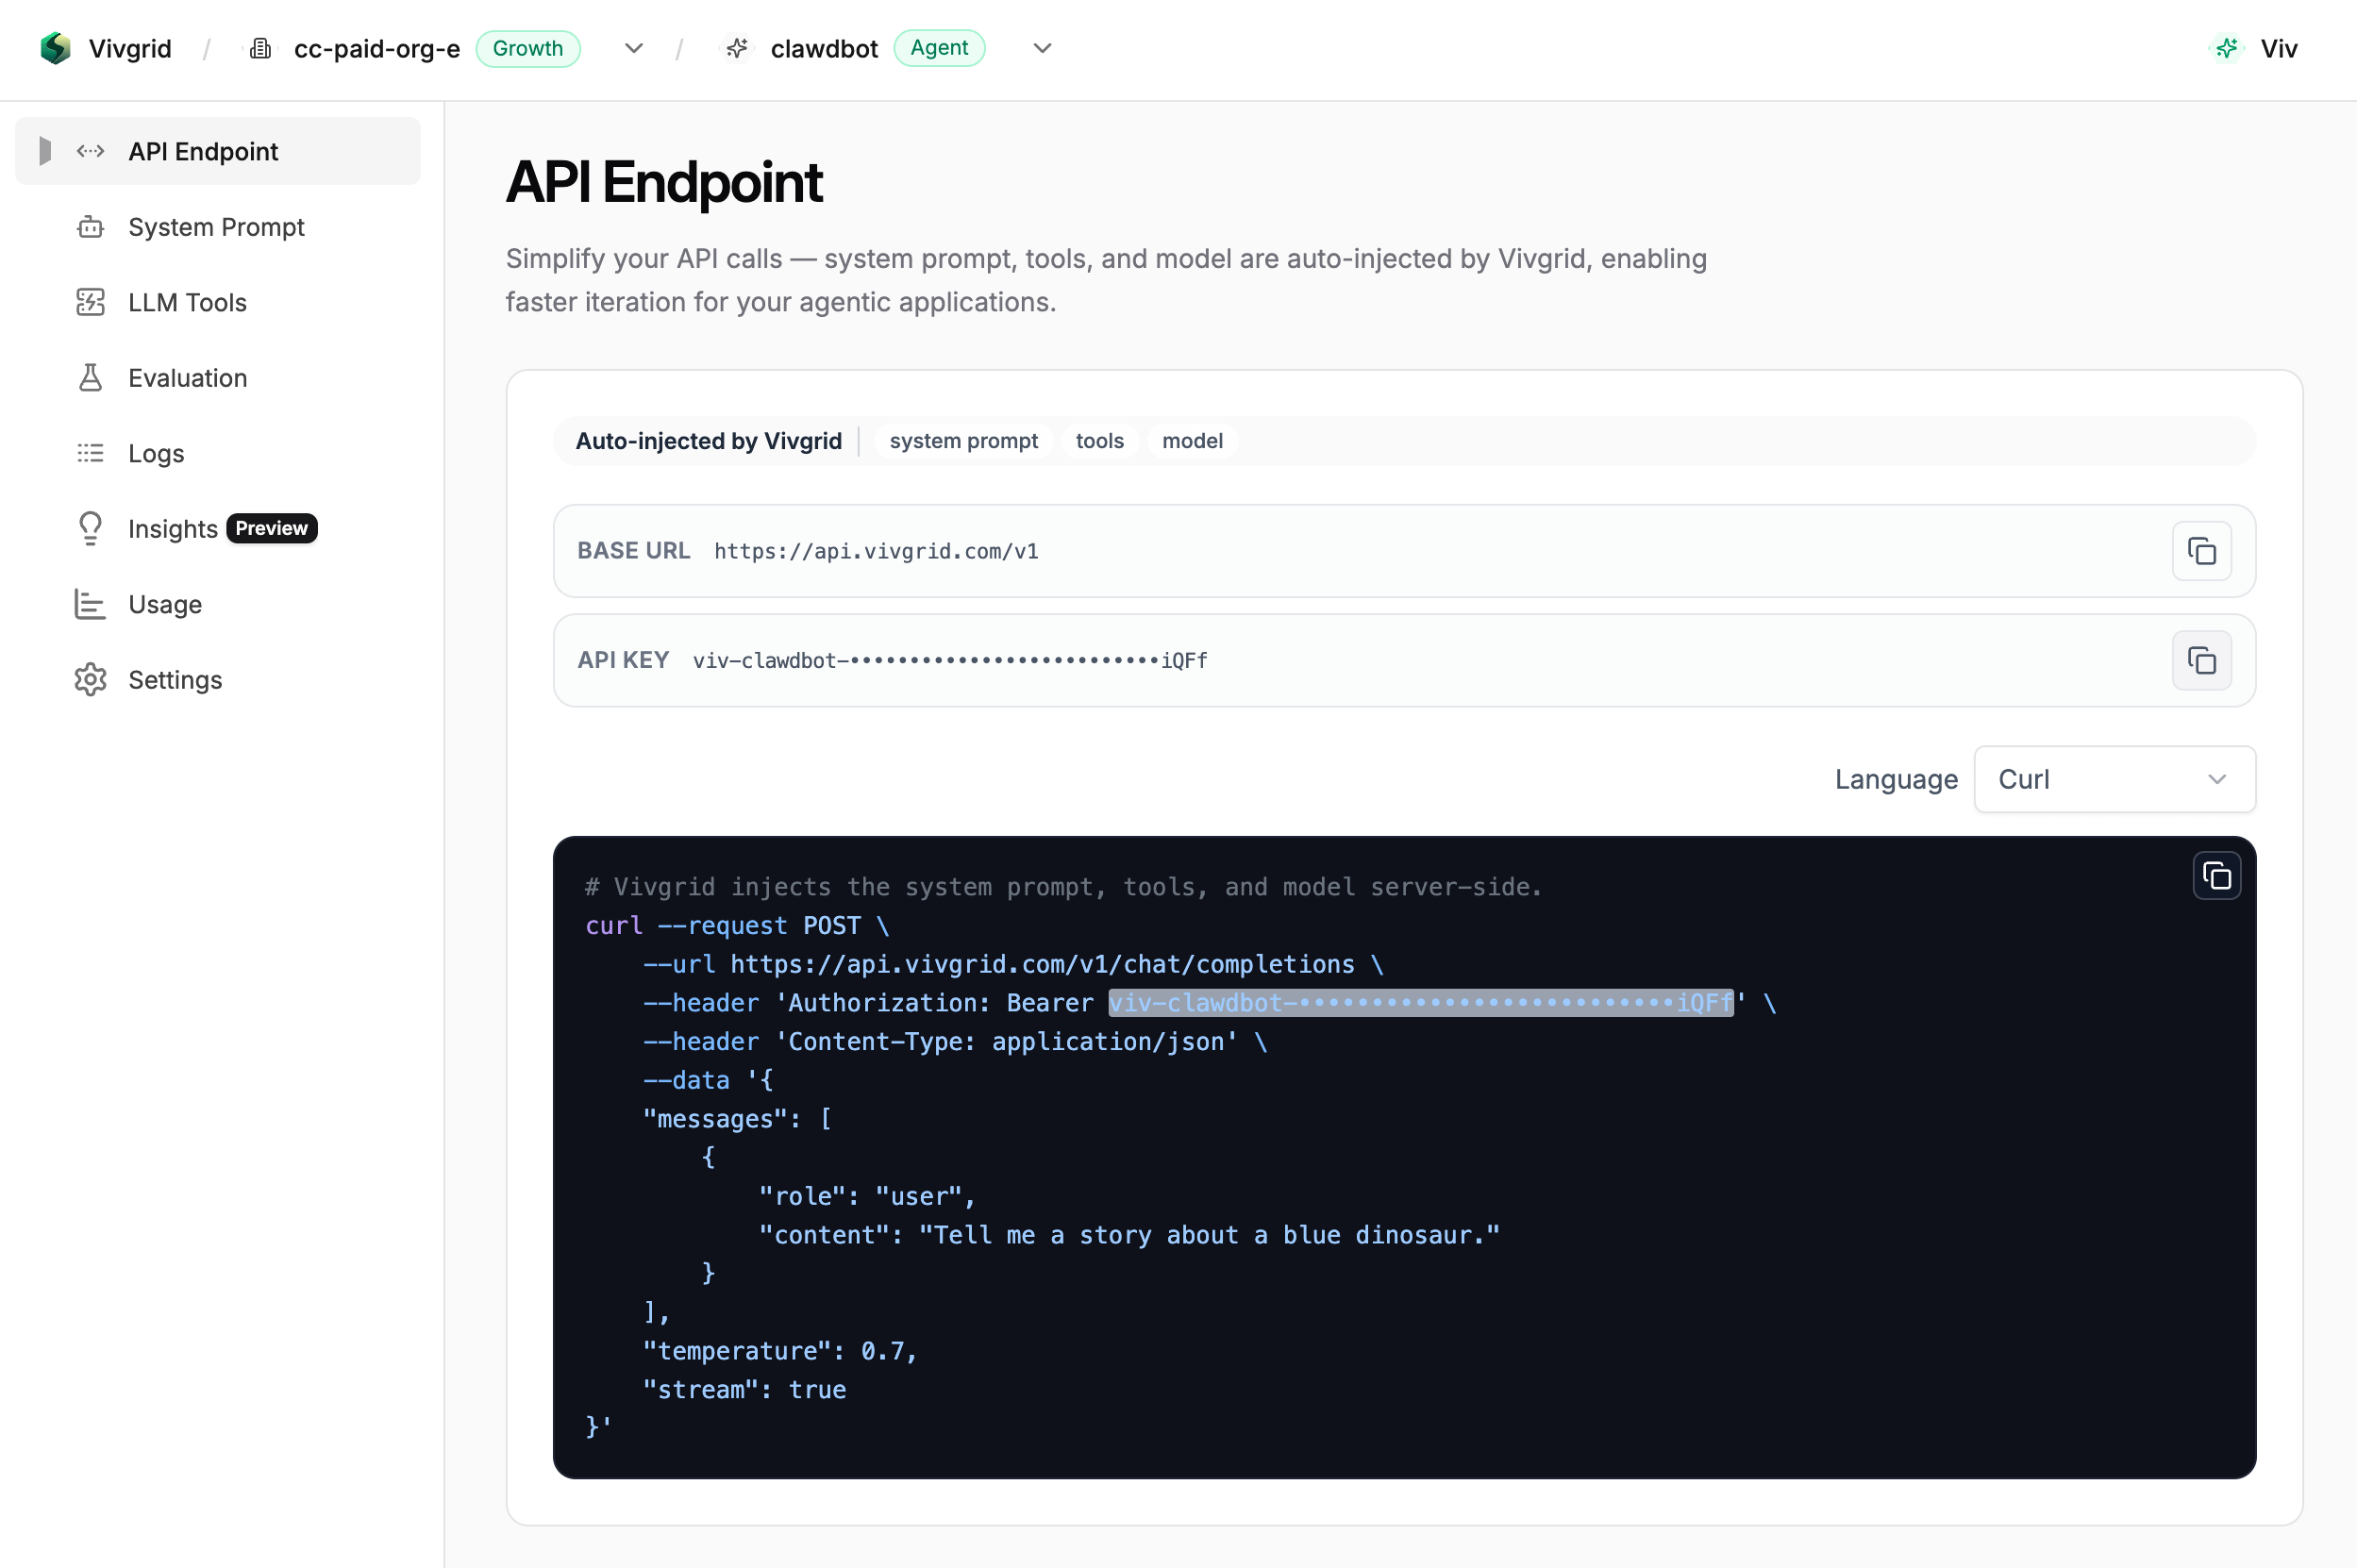
Next, add Vivgrid as a model provider in your `openclaw.json` configuration file, and set the agent's primary model to `vivgrid/auto`:
```json ~/.openclaw/openclaw.json lines icon="rust" highlight={4-15,28-30}
{
"models": {
"providers": {
"vivgrid": {
"baseUrl": "https://api.vivgrid.com/v1",
"apiKey": "viv-openclaw-xxxxxxxxxxxxxxxxxxxx",
"api": "openai-completions",
"models": [
{
"id": "auto",
"name": "auto",
"contextWindow": 128000
}
]
}
}
},
"agents": {
"defaults": {
"maxConcurrent": 4,
"subagents": {
"maxConcurrent": 8
},
"compaction": {
"mode": "safeguard"
},
"workspace": "/home/cc/clawd",
"model": {
"primary": "vivgrid/auto"
}
}
},
// ... other configurations ...
}
```
After saving the configuration, restart the OpenClaw gateway service to apply the changes:
```sh
openclaw gateway restart
```
You can change the underlying LLM at any time in the Vivgrid Console without modifying OpenClaw's configuration. Simply go to your project's `Settings` tab and select the model you want (for example, `gemini-3-pro-preview` or `DeepSeek-V3.2`).
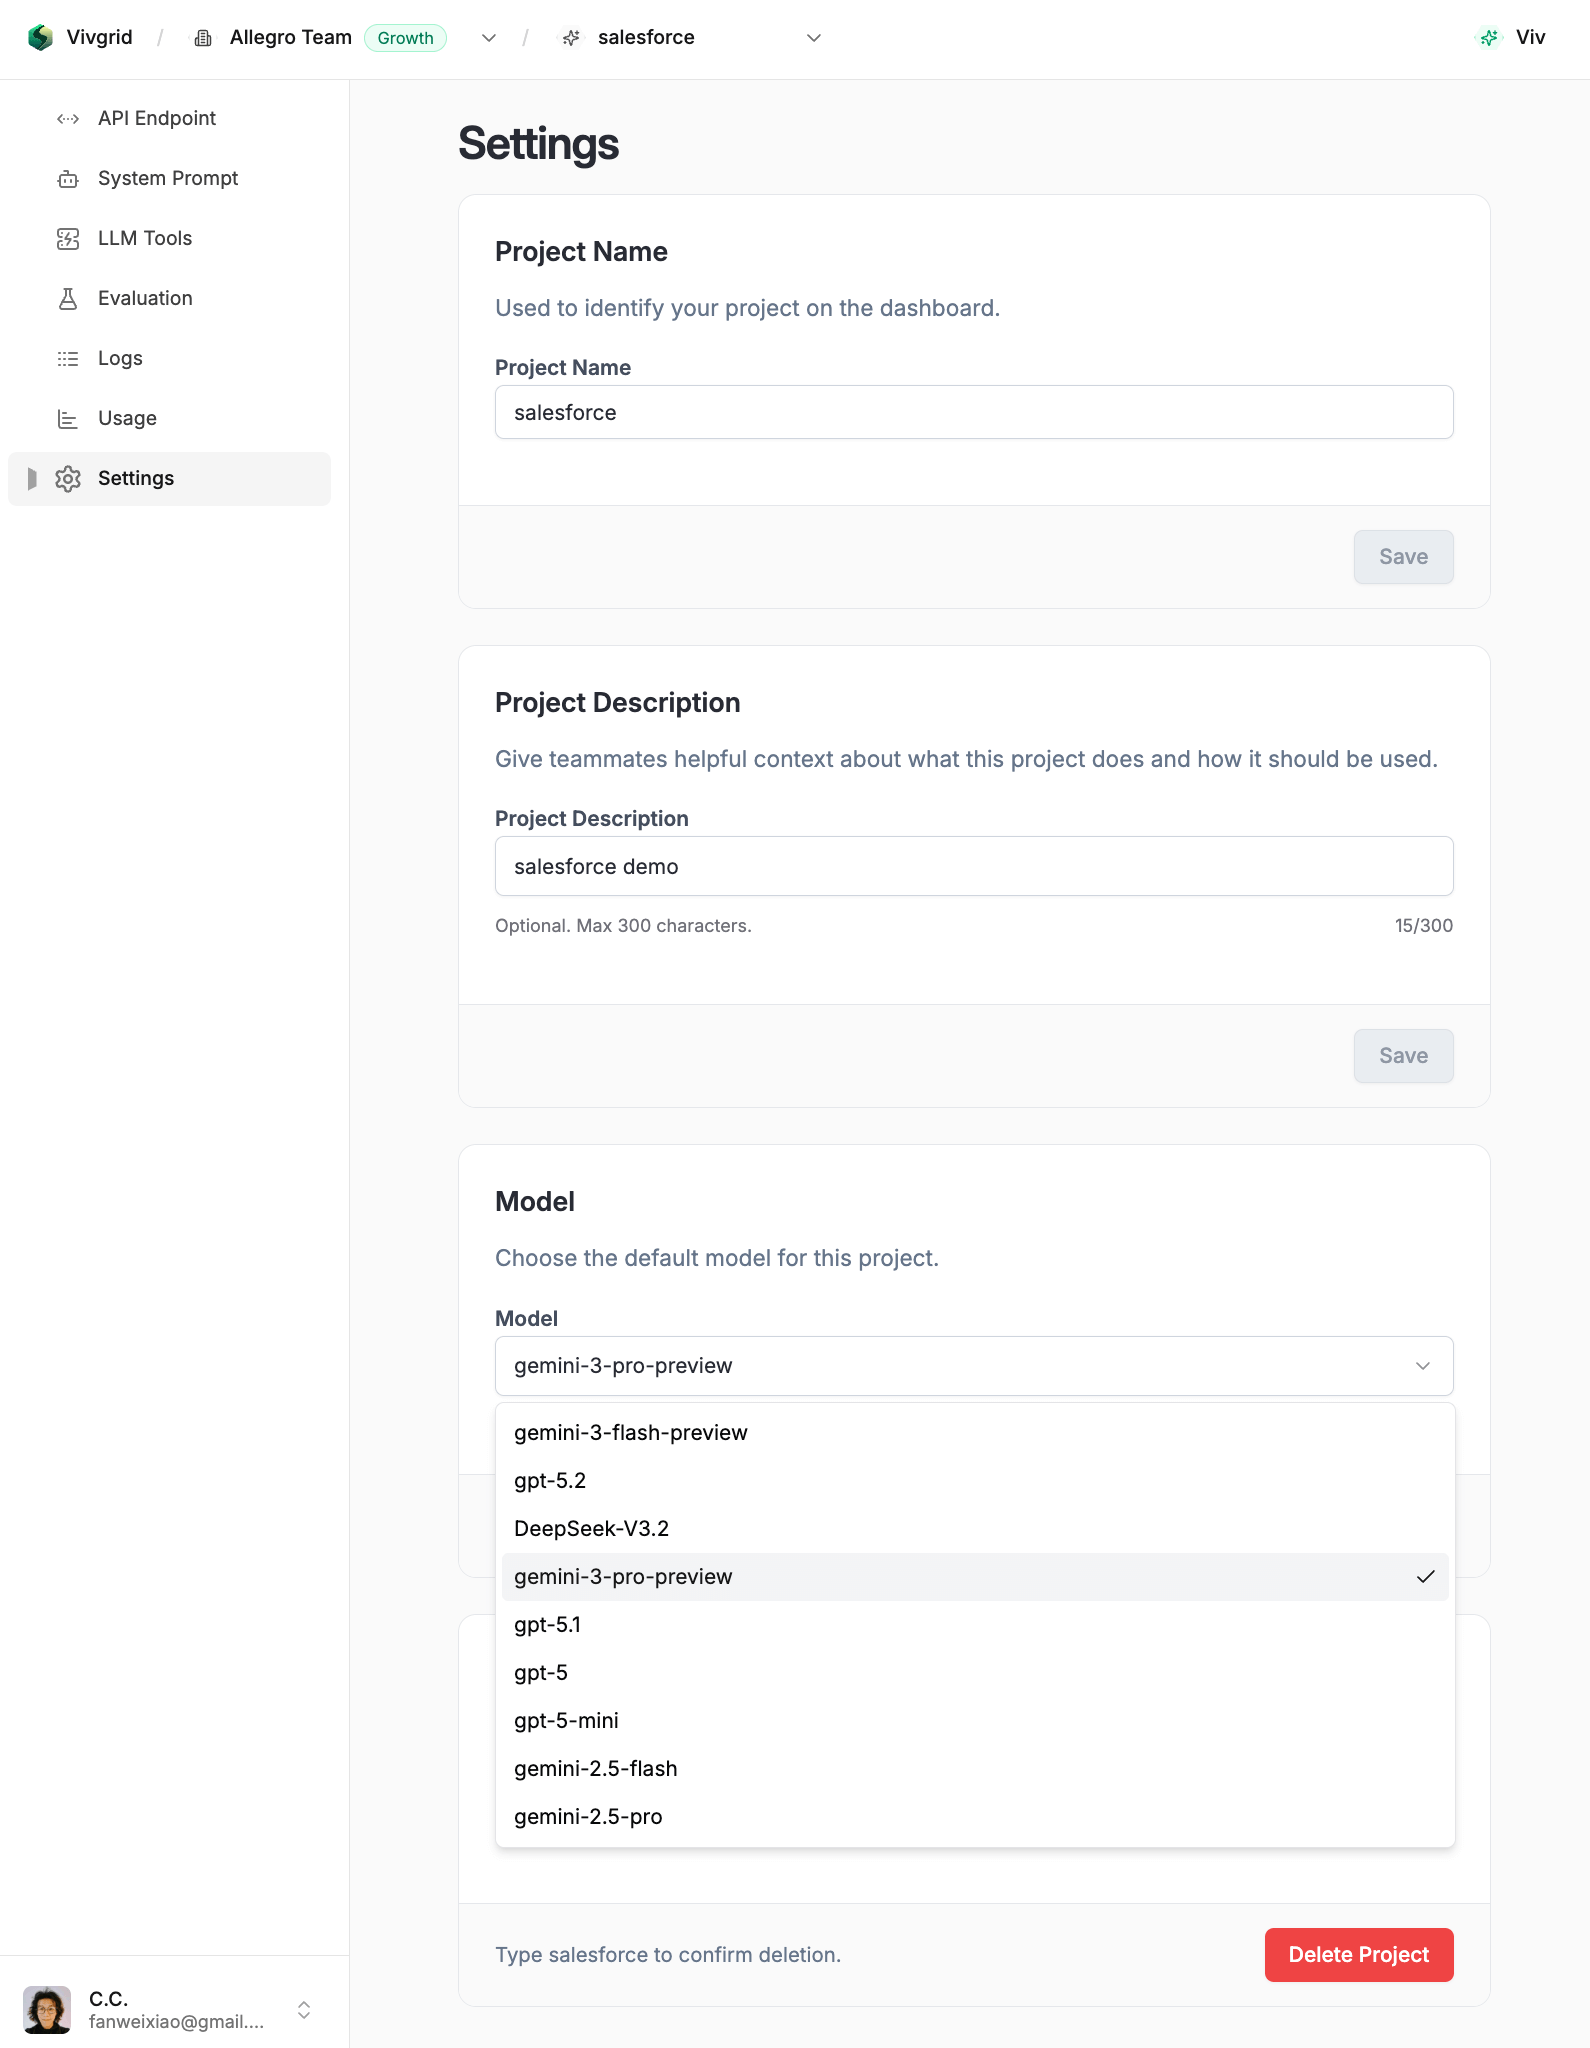
{/*
For better monitoring and debugging, enable `Insights` in the Vivgrid Console. This will provide detailed logs of model interactions, latency, and errors.

*/}
## Best Practices
Use `vivgrid/auto` as the primary model for OpenClaw agents.
By setting the model to `vivgrid/auto`, OpenClaw connects to Vivgrid's managed routing layer instead of a fixed LLM. This allows you to:
- Upgrade or switch underlying LLMs at any time in the Vivgrid Console
- Avoid changing `openclaw.json` when models evolve
- Eliminate service restarts for model upgrades
- Keep your agent configuration stable and future-proof
This is the recommended setup for production environments.
---
# ChatGPT/Codex × Vivgrid
> Source: https://vivgrid.com/docs/tutorials/codex
How to use Vivgrid with gpt-6-astra, gpt-5.6 and gpt-5.3-codex in Codex
## Install Codex
```
npm i -g @openai/codex
```
## Configure Codex to Use Vivgrid (gpt-6-astra)
Copy the following configuration files to your codex config file.
```toml ~/.codex/config.toml lines icon="rust" highlight={2,11}
model = "gpt-6-astra"
model_provider = "vivgrid"
model_reasoning_effort = "high"
model_reasoning_summary = "detailed"
model_verbosity = "medium"
personality = "pragmatic"
preferred_auth_method = "apikey"
forced_login_method = "api"
[features]
streamable_shell = true
unified_exec = true
shell_snapshot = true
js_repl = false
[model_providers.vivgrid]
name = "Vivgrid"
base_url = "https://api.vivgrid.com/v1"
wire_api = "responses"
experimental_bearer_token = "viv-xxxxxxxxxxxxx"
```
## Start Using Codex with Vivgrid
Run ChatGPT App
---
# Elia x Vivgrid
> Source: https://vivgrid.com/docs/tutorials/elia
How to integrate Vivgrid to Elia
## Elia
[Elia](https://github.com/darrenburns/elia) is an open source TUI for interacting with LLMs, it's designed to be keyboard-focused and efficient to use.
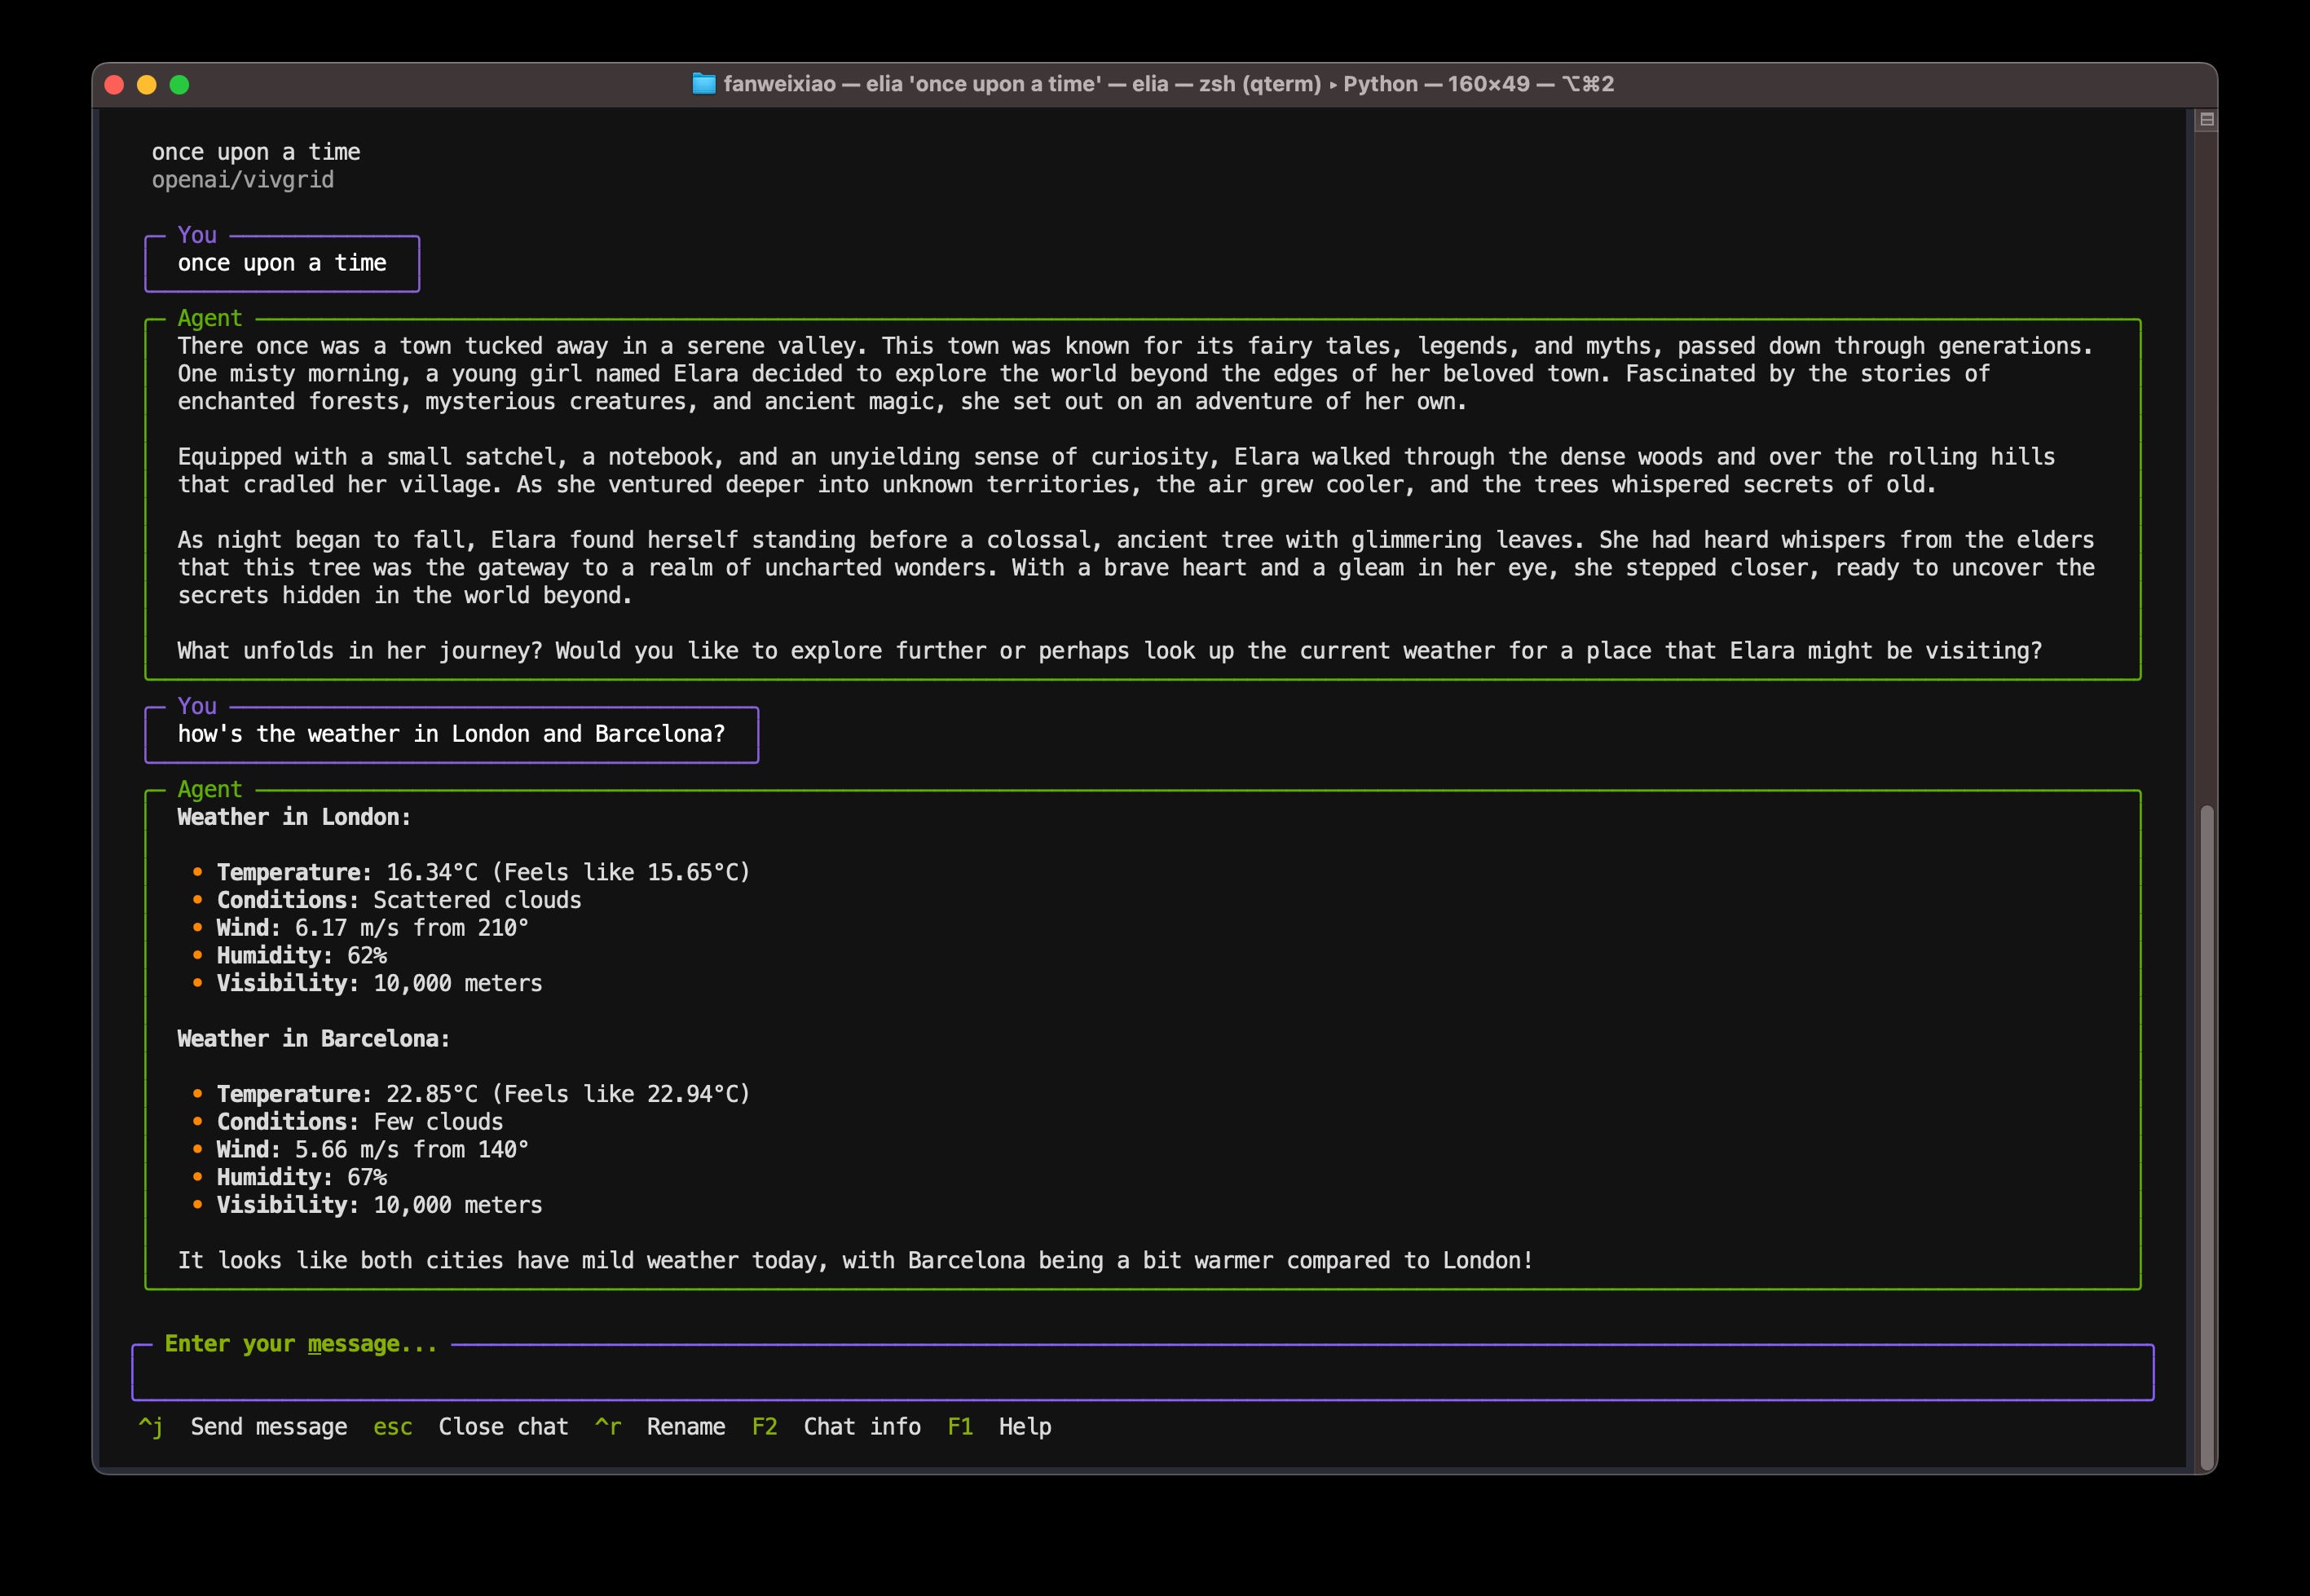
## Install Elia
Elia can be installed by [pipx](https://github.com/pypa/pipx), if you don't have pipx, follow these steps:
```sh tab="Mac"
brew install pipx
```
```sh tab="Fedora"
sudo dnf install pipx
```
```sh tab="Ubuntu"
sudo apt update && sudo apt install pipx
```
```sh tab="Windows"
scoop install pipx
```
After this, remember run:
```sh
pipx ensurepath
```
Then, install Elia:
```sh
pipx install elia-chat
```
## Configure Elia for Vivgrid
edit elia configuration file:
```sh
vim ~/.config/elia/config.toml
```
with content:
```toml
default_model="vivgrid"
[[models]]
id = "vivgrid"
name = "openai/vivgrid"
api_base = "https://api.vivgrid.com/v1/"
api_key = ""
```
## Try it!
```sh
elia "how's the weather in London?"
```
---
# OpenCode × Vivgrid
> Source: https://vivgrid.com/docs/tutorials/opencode
How to use Vivgrid with gpt-6-astra in OpenCode.ai
## OpenCode
[OpenCode.ai](https://opencode.ai) is an open-source, model-agnostic AI coding agent designed to bring powerful AI assistance directly into developers’ workflows—whether you are working in the terminal, using a desktop application, or inside an IDE extension.
Key features include:
- **Terminal-first, multi-interface design**\
A native terminal UI (TUI), with optional desktop and IDE extensions, allows developers to work in their preferred environment.
- **Context-aware intelligence**\
Language Server Protocol (LSP) integration enables deep understanding of project structure and symbols.
- **Multi-session collaboration**\
Run parallel agent sessions within the same repository and share them for collaborative debugging or review.
- **Privacy-first by design**\
Code and project context are not stored on remote servers, making OpenCode suitable for sensitive or proprietary codebases.
## Configure OpenCode.ai to Use Vivgrid (GPT-6 Astra)
One of OpenCode’s core strengths is its clean separation between **authentication** and **runtime model configuration**. Credentials are configured independently from model selection, allowing you to switch providers or models without changing your workflow.
To use [Vivgrid](https://vivgrid.com) as the provider and `gpt-6-astra` as the model, you only need to configure as:
## Debugging
If you encounter issues, enable detailed logs:
```sh
opencode run "hello" --print-logs --log-level DEBUG
```
This will surface provider initialization, model resolution, and API-level errors.
## GUI
This configuration also works for OpenCode GUI App.
## Summary
With only two small configuration files, [OpenCode](https://opencode.ai) becomes a provider-agnostic AI coding agent, while [Vivgrid](https://vivgrid.com) serves as a drop-in, OpenAI-compatible backend for [GPT-5.5](https://platform.openai.com/docs/models/gpt-5.5).
This clear separation between credential management and runtime configuration is what makes OpenCode especially well-suited for advanced models, custom providers, and production-grade AI coding workflows.
---
# Pi × Vivgrid
> Source: https://vivgrid.com/docs/tutorials/pi
How to use Vivgrid with gpt-6-astra, deepseek-v4-pro and claude-opus-5 in Pi
## Pi
[Pi](https://pi.dev) is a minimal terminal coding harness. It ships with read, bash, edit and write tools, then gets out of your way — you extend it with TypeScript extensions, skills, prompt templates and themes instead of forking it.
Key features include:
- **Provider-agnostic by design**\
Any OpenAI-, Anthropic- or Google-compatible endpoint becomes a first-class provider through a single JSON file.
- **Four run modes**\
Interactive TUI, `--print` for one-shot prompts, JSON/RPC for process integration, and an SDK for embedding.
- **Sessions you can branch**\
Continue, resume, fork or export any session; compaction keeps long runs inside the context window.
- **Extend it yourself**\
Extensions are plain TypeScript files, shareable as npm or git packages.
## Install Pi
```bash
npm install -g --ignore-scripts @earendil-works/pi-coding-agent
```
Or use the installer script:
```bash
curl -fsSL https://pi.dev/install.sh | sh
```
## Configure Pi to Use Vivgrid
Grab your API key from the [Vivgrid Console](https://console.vivgrid.com), then add Vivgrid as a provider in `~/.pi/agent/models.json`:
```json ~/.pi/agent/models.json lines icon="json" highlight={4,5,6}
{
"providers": {
"vivgrid": {
"baseUrl": "https://api.vivgrid.com/v1",
"apiKey": "viv-xxxxxxxxxxxxx",
"api": "openai-completions",
"models": [
{
"id": "gpt-6-astra",
"api": "openai-responses",
"reasoning": true,
"input": ["text", "image"],
"contextWindow": 1050000,
"maxTokens": 128000
},
{
"id": "claude-fable-5-1",
"reasoning": true,
"contextWindow": 1000000,
"maxTokens": 128000
},
{
"id": "gemini-3.8-flash",
"reasoning": true,
"input": ["text", "image"],
"contextWindow": 1000000,
"maxTokens": 65536
},
{
"id": "claude-opus-5",
"reasoning": true,
"contextWindow": 1000000,
"maxTokens": 128000
},
{
"id": "deepseek-v4-pro-0813",
"reasoning": true,
"contextWindow": 1000000,
"maxTokens": 128000
},
{
"id": "glm-5.3",
"reasoning": true,
"contextWindow": 1000000,
"maxTokens": 128000
}
]
}
}
}
```
Three things worth noting:
- One key, one `baseUrl` — every Vivgrid model in the list is reachable through the same OpenAI-compatible endpoint.
- The GPT entries override `api` at the model level to `openai-responses`, because Vivgrid serves the GPT-6 and GPT-5.6 families through the Responses API. The rest stay on `openai-completions`.
- `glm-5.3-flash` sets `compat.supportsDeveloperRole` to `false`, so Pi sends the system prompt as a `system` message instead of a `developer` one.
`models.json` is re-read every time you open `/model`. Add a model mid-session
and it shows up immediately — no restart needed.
Add more models from the [Vivgrid catalog](/docs/models) by appending entries to the same list.
## Make Vivgrid the Default
Set the provider, model and thinking level Pi starts with in `~/.pi/agent/settings.json`:
```json ~/.pi/agent/settings.json lines icon="json" highlight={2,3,4}
{
"defaultProvider": "vivgrid",
"defaultModel": "gpt-6-astra",
"defaultThinkingLevel": "high",
"theme": "dark",
"tuiMode": "regular"
}
```
`defaultThinkingLevel` accepts `off`, `minimal`, `low`, `medium`, `high`, `xhigh` and `max`.
## Verify
List everything Pi resolved for the provider:
```bash
pi --list-models vivgrid
```
```
provider model context max-out thinking images
vivgrid gpt-6-astra 1.1M 128K yes yes
vivgrid claude-fable-5-1 1M 128K yes no
vivgrid claude-opus-5 1M 128K yes no
vivgrid deepseek-v4-pro-0813 1M 128K yes no
vivgrid gemini-3.8-flash 1M 65.5K yes yes
vivgrid glm-5.3 1M 128K yes no
```
## Start Using Pi with Vivgrid
```bash
pi
```
Press `/model` to switch models, or `Ctrl+P` to cycle through them. You can also pick a model per run:
```bash
pi --provider vivgrid --model gpt-6-astra --thinking high
```
Or run a one-shot prompt without entering the TUI:
```bash
pi -p "explain the auth flow in this repo" --model vivgrid/deepseek-v4-flash
```
## Summary
Pi keeps credentials and model definitions in one small JSON file, which makes [Vivgrid](https://vivgrid.com) a drop-in backend: point `baseUrl` at `https://api.vivgrid.com/v1`, paste one key, and the whole catalog — GPT-6, DeepSeek-V4, Gemini 3.7, GLM-5.3 — becomes selectable from `/model` with geo-distributed acceleration behind it.
---
# Chat Completions
> Source: https://vivgrid.com/docs/api/agent/completions
OpenAI-compatible Chat Completions endpoint.
---
# OCR
> Source: https://vivgrid.com/docs/api/model-api/ocr
Extracts text from an image via chat-style message with image_url content.
---
# Embeddings
> Source: https://vivgrid.com/docs/api/model-api/embedding
Generates an embedding vector representing the input text.
---
# Vibe Coding
> Source: https://vivgrid.com/docs/api/model-api/vibe-coding
Creates a model response. Provide text or image inputs to generate text or JSON outputs. Supports tool calling and conversation state.
---
# Audio-to-Text
> Source: https://vivgrid.com/docs/api/model-api/whisper
Transcribes audio into the input language.
---
# Text-to-Speech
> Source: https://vivgrid.com/docs/api/model-api/tts
Generates audio from text input (text-to-speech).
---
# Image
> Source: https://vivgrid.com/docs/api/model-api/images
Creates an image from a text prompt (OpenAI-compatible).
---
# Rerank
> Source: https://vivgrid.com/docs/api/model-api/rerank
Re-ranks a list of documents against a query using an embedding/rerank model.
---
# Privacy Policy – Vivgrid | User Data Protection & Security
> Source: https://vivgrid.com/privacy
Vivgrid respects your privacy. Discover what personal & usage data we collect, how we use it, and how you can update or delete your account at any time.
**Effective date: August 1st, 2024**
Allegro US, LLC. ("Vivgrid", "we", "us", or "our") is committed to protecting the privacy and security of our users. This Privacy Policy explains how we collect, use, and disclose information about you when you use the vivgrid app and related services (collectively, the "Service").
### 1. Information We Collect
We may collect the following types of information about you:
1.1. Personal Information: When you create an account, we may collect your name, email address, profile pictures and other information you provide.
1.2. Usage Information: We may collect information about how you use the Service, such as the content you create, share, or interact with.
1.3. Device Information: We may collect information about the device you use to access the Service, such as the hardware model, operating system, and unique device identifiers.
1.4. Location Information: We may collect information about your location, such as your IP address or GPS location, to provide location-based features or services.
### 2. How We Use Your Information
We may use the information we collect about you for the following purposes:
2.1. Providing and Improving the Service: We use your information to operate, maintain, and improve the Service, and to develop new features and services.
2.2. Personalization: We may use your information to personalize your experience on the Service, such as by providing customized content or recommendations.
2.3. Communication: We may use your information to communicate with you about the Service, such as to send you updates, notifications, or to respond to your inquiries.
2.4. Compliance and Safety: We may use your information to comply with legal requirements, enforce our policies, and protect the safety and security of the Service and our users.
### 3. How We Share Your Information
We may share your information with the following parties:
3.1. Service Providers: We may share your information with third-party service providers who perform services on our behalf, such as hosting, data analysis, or customer support.
3.2. Legal Compliance: We may share your information in response to a legal request, such as a subpoena or court order, or to comply with applicable laws or regulations.
3.3. Business Transfers: We may share your information in connection with a merger, acquisition, or sale of all or a portion of our assets.
### 4. Your Choices
You have the following choices regarding your information:
4.1. Access and Update: You can access and update your account information by logging into your account on the Service.
4.2. Deletion: You can delete your account at any time by contacting us at [privacy@vivgrid.com](mailto:privacy@vivgrid.com).
4.3. Opt-Out: You can opt-out of receiving certain communications from us by following the instructions provided in those communications.
### 5. Security
We take reasonable measures to protect your information from unauthorized access, use, or disclosure. However, no security measures are perfect, and we cannot guarantee the absolute security of your information.
### 6. Changes to this Privacy Policy
We may update this Privacy Policy from time to time. We will notify you of any changes by posting the updated Privacy Policy on the Service.
### 7. Contact Us
If you have any questions or concerns about this Privacy Policy or our privacy practices, please contact us at [privacy@vivgrid.com](mailto:privacy@vivgrid.com).
---
# AI Terms and Conditions You Need to Know
> Source: https://vivgrid.com/terms
Review Vivgrid's AI terms and conditions outlining platform rules, user responsibilities, data usage, acceptable use, and ethical AI practices.
**Last updated August 29th, 2024**
PLEASE READ THESE TERMS AND CONDITIONS CAREFULLY BEFORE USING THE SERVICE OFFERED BY ALLEGRO US, LLC (“VIVGRID”). BY MUTUALLY EXECUTING ONE OR MORE ORDER FORMS WITH COMPANY WHICH REFERENCE THESE TERMS (EACH, A “SERVICE ORDER”) OR BY ACCESSING OR USING THE SERVICES IN ANY MANNER, YOU (“YOU” OR “CUSTOMER”) AGREE TO BE BOUND BY THESE TERMS (TOGETHER WITH ALL SERVICE DESCRIPTIONS AND/OR ORDER FORMS, IF ANY, THE “AGREEMENT”) TO THE EXCLUSION OF ALL OTHER TERMS. YOU REPRESENT AND WARRANT THAT YOU HAVE THE AUTHORITY TO ENTER INTO THIS AGREEMENT; IF YOU ARE ENTERING INTO THIS AGREEMENT ON BEHALF OF AN ORGANIZATION OR ENTITY, REFERENCES TO “CUSTOMER” AND “YOU” IN THIS AGREEMENT, EXCEPT THIS SENTENCE, REFER TO THAT ORGANIZATION OR ENTITY. IF YOU DO NOT AGREE TO ALL OF THE FOLLOWING, YOU MAY NOT USE OR ACCESS THE SERVICES IN ANY MANNER. IF THE TERMS OF THIS AGREEMENT ARE CONSIDERED AN OFFER, ACCEPTANCE IS EXPRESSLY LIMITED TO SUCH TERMS.
### 1. SCOPE OF SERVICE AND RESTRICTIONS
1. **Access and Scope of Service**. Subject to Customer’s compliance with the terms and conditions of the Agreement, including use in accordance with the applicable Service Description and, if applicable, Vivgrid’s receipt of the applicable Fees with respect to the service specified in the corresponding Service Order (the “Service”), Vivgrid will use commercially reasonable efforts to make the Service available to Customer as set forth in this Agreement and the Service Description and/or Service Order. Subject to Customer’s compliance with the terms and conditions of the Agreement, Customer may access and use the Service during the period specified in the Service Description or Service Order, if applicable. Any such use of the Service by Customer is solely for Customer’s internal business. Notwithstanding the foregoing, Customer may use the Service with respect to third party data, and such third-party data shall be considered Customer Data.
2. **Service Description**. Customer’s use of the Services shall at all times be limited and subject to the use limitations and authorizations as specified within Vivgrid’s published listing currently located at the following URL https://vivgrid.com/pricing for the Service (the “Service Description”).
3. **Modifications**. In the absence of any conflicting terms defined within a committed Service Order, Customer acknowledges and agrees that Vivgrid may discontinue or terminate the Service at any time and for any reason or modify the applicable terms by publishing a notice on the Vivgrid website or by other means to the extent required by applicable law.
4. **Trial Use**. If Customer is accessing or making use of the Service on a trial basis (the “Trial Use”) as identified in the corresponding Service Order, or as presented to Customer in connection with such trial basis or per an applicable Service Description (the “Trial Use Limitations”), Customer may use the Service consistent with the Trial Use Limitations provided such use does not to exceed the Service levels or related entitlements set forth in the Trial Use Limitations. Customer acknowledges and agrees that the Trial Use is provided on an “as-is” basis and the Trial Use is provided without any indemnification, support, warranties or representation of any kind. Further, Trial Use may be subject to certain additional restrictions, limitations and differing terms all as specified in the corresponding Trial Use Limitations.
5. **Restrictions**. Customer will use the Service only in accordance with all applicable laws, including, but not limited to, laws related to data (whether applicable within the United States, the European Union, or otherwise). Customer agrees not to (and will not allow any third party to): (i) remove or otherwise alter any proprietary notices or labels from the Service or any portion thereof; (ii) reverse engineer, decompile, disassemble, or otherwise attempt to discover the underlying structure, ideas, or algorithms of the Service or any software used to provide or make the Service available; or (iii) rent, resell or otherwise allow any third-party direct access to or use of the Service.
6. **Ownership**. Vivgrid retains all right, title, and interest in and to the Service, and any software, products, works or other intellectual property created, used, provided or made available by Vivgrid under or in connection with the Service. Customer may from time to time provide suggestions, comments or other feedback to Vivgrid with respect to the Service (“Feedback”). Customer hereby grants to Vivgrid a nonexclusive, worldwide, perpetual, irrevocable, transferable, sublicensable, royalty-free, fully paid-up license to use and exploit any Feedback for any purpose. Nothing in this Agreement will impair Vivgrid’s right to develop, acquire, license, market, promote or distribute products, software or technologies that perform the same or similar functions as, or otherwise compete with any products, software or technologies that Customer may develop, produce, market, or distribute.
7. **Software**. Customer acknowledges and agrees that no software code with respect to the Service will be provided to Customer hereunder, and that certain software libraries and tools, and updates thereto, are necessary to access and use the Service (the “Vivgrid Tools”). The Vivgrid Tools should be available at the following URL: https://github.com/vivgrid/cli under applicable open source licensing terms. Customer agrees that it is responsible for obtaining, installing and maintaining the Vivgrid Tools, and that Vivgrid makes no representations, warranties or is otherwise liable or obligated hereunder with respect to such Vivgrid tools.
8. **Customer Data**. Customer is solely responsible for Customer Data including, but not limited to: (a) compliance with all applicable laws and regulations; and (b) any claims that Customer Data infringes, misappropriates, or otherwise violates the rights of any third party. Customer is responsible for the use of the Service by any person to whom Customer has given access to the Service, even if Customer did not authorize such use. Customer agrees and acknowledges that Customer Data may be irretrievably deleted if Customer’s account is terminated.
9. **Use of Customer Data**. Customer hereby grants to Vivgrid a limited license to use Customer Data as necessary to provide the Service to Customer. For purposes of this Agreement, “Customer Data” shall mean any data, information or other material provided, uploaded, or submitted by Customer to the Service in the course of using the Service. Customer shall retain all right, title and interest in and to the Customer Data, including all intellectual property rights therein. Notwithstanding anything to the contrary herein, in no event will Vivgrid sell or share any personal data to the extent included within Customer Data (including but not limited to any data inputs or outputs resulting from an authorized user's use of the Service) to any third party for marketing purposes.
10. **Aggregated De-Identified Data**. Notwithstanding anything to the contrary, Vivgrid may freely use Aggregated De-identified Data for Vivgrid’s business purposes (including without limitation, for purposes of improving, testing, operating, promoting and marketing Vivgrid’s current and future products and services). “Aggregated De-identified Data” means data collected by Vivgrid in connection with Customer’s use of the Service, but only in aggregate, de-identified form which is not linked specifically to Customer or any individual, excluding Customer Data uploaded or submitted by Customer.
11. **Personal Data**. Customer represents and warrants that it will not provide access, transfer or otherwise make available to Vivgrid any personally identifiable information or personal data subject to applicable law or regulation (“Subject Data”). Customer acknowledges and agrees that Subject Data is not necessary for Customer to use the Service.
12. **Service Suspension**. Vivgrid may suspend Customer’s access to or use of the Service as follows: (a) immediately if Vivgrid reasonably believes Customer’s use of the Service may pose a security risk to or may adversely impact the Service; (b) immediately if Vivgrid reasonably believes Customer is or has used the Service in connection with any of the following: cryptocurrency mining or related blockchain related activities, denial of service attacks, peer-to-peer file sharing, or as a general file-hosting or media-serving platform; (c) immediately if Customer become insolvent, has ceased to operate in the ordinary course, made an assignment for the benefit of creditors, or becomes the subject of any bankruptcy, reorganization, liquidation, dissolution or similar proceeding; (d) following thirty (30) days written notice if Customer is in breach of this Agreement or any Service Description or Service Order (and has not cured such breach, if curable, within the thirty (30) days of such notice); or (e) Customer has failed to pay Vivgrid the Fees with respect to the Service. If any amount owing by Customer is thirty (30) or more days overdue (or 10 or more days overdue in the case of invoices to be paid by credit card), Vivgrid may, without limiting any rights and remedies, accelerate Customer’s unpaid fee obligations to become immediately due and payable, and suspend the provision of the Service to Customer until the overdue amounts are paid in full. Vivgrid will give Customer at least ten (10) days’ prior notice that its account is overdue before suspending services to Customer due to overdue amounts.
13. **Data Transfer**. For clarity, Customer understands and agrees that by using the Services, Customer is explicitly consenting to the processing and transfer of Customer Data (which may constitute Personal Data) within and to the United States, Canada, the European Economic Area, Australia, and Asia.
### 2. FEES AND TAXES
1. **Fees**. Customer shall pay to Vivgrid the fees as set forth in each applicable Service Order(s) or Service Description (collectively, the “Fees”) and will provide accurate and updated billing contact information. Minimum commitments as set forth in Service Orders and Service Descriptions are (a) based on the Service purchased and not actual usage, unless otherwise defined within a Service Description; (b) non-cancelable; and (c) cannot be decreased during the specified term set forth in an applicable Service Order. Fees are not refundable. To the extent defined within a Service Description, Customer may be auto-billed by Vivgrid following each billing period.
2. **Invoicing Terms**. Vivgrid will invoice Customer either monthly or according to the billing frequency stated in the applicable Service Description or Service Order. Invoices are due pursuant to the corresponding Service Description or Service Order. If any invoiced amount is not received by Vivgrid by the due date, then without limiting Vivgrid’s rights or remedies: (a) those charges may accrue late interest at the rate of 1.5% of the outstanding balance per month, or the maximum rate permitted by law, whichever is lower, and (b) Vivgrid may condition future renewals and Service Orders on shorter payment terms. If Vivgrid is required to initiate legal action due to nonpayment of fees, Customer shall bear all costs resulting from the collection of such fees.
3. **Taxes**. Any and all payments made by Vivgrid in accordance with this Agreement are exclusive of any taxes that might be assessed against Customer by any jurisdiction. Customer shall pay or reimburse Vivgrid for all value-added, sales, use, property and similar taxes; all customs duties, import fees, stamp duties, license fees and similar charges; and all other mandatory payments to government agencies of whatever kind, except taxes imposed on the net or gross income of Vivgrid. All amounts payable to Vivgrid under this Agreement shall be without set-off and without deduction of any taxes, levies, imposts, charges, withholdings and/or duties of any nature which may be levied or imposed, including without limitation, value added tax, customs duty and withholding tax.
### 3. TERM AND TERMINATION
1. **Term**. The term of this Agreement shall commence on the Effective and unless terminated earlier according to this Section 3, will end on the last day of the term specified in an applicable Service Description or last Service Order (the “Term”). Each Service Description or Service Order will renew automatically at the end of the applicable term unless either party provides to the other advance written notice with respect to non-renewal at least thirty (30) days prior to the end of the then current term.
2. **Termination**. This Agreement and the applicable Service Description or Service Orders hereunder may be terminated: (a) by either party if the other has materially breached this Agreement, within thirty (30) calendar days after written notice of such breach to the other party if the breach is remediable or immediately upon notice if the breach is not remediable; or (b) by Vivgrid upon written notice to Customer if Customer (i) has made or attempted to make any assignment for the benefit of its creditors or any compositions with creditors, (ii) has any action or proceedings under any bankruptcy or insolvency laws taken by or against it which have not been dismissed within sixty (60) days, (iii) has effected a compulsory or voluntary liquidation or dissolution, or (iv) has undergone the occurrence of any event analogous to any of the foregoing under the law of any jurisdiction.
3. **Effect of Termination**. Upon any expiration or termination of this Agreement, Customer shall (i) immediately cease use of the Service, and (ii) return all Vivgrid Confidential Information and other materials and information provided by Vivgrid. Any termination or expiration shall not relieve Customer of its obligation to pay all Fees accruing prior to termination. If the Agreement is terminated due to Section 3.2 (a), Customer shall pay to Vivgrid all Fees set forth in the corresponding Service Order(s).
4. **Survival**. The following provisions will survive termination of this Agreement: Sections 1.4 (Ownership), 3.3 (Effect of Termination), Section 3.4 (Survival), Section 4 (Confidentiality), Section 7 (Limitation of Liability), Section 8 (Miscellaneous).
### 4. CONFIDENTIALITY
During the term of this Agreement, either party may provide the other party with confidential and/or proprietary materials and information (“Confidential Information”). All materials and information provided by the disclosing party and identified at the time of disclosure as “Confidential” or bearing a similar legend, and all other information that the receiving party reasonably should have known was the Confidential Information of the disclosing party, shall be considered Confidential Information. This Agreement is Confidential Information, and all pricing terms are Vivgrid Confidential Information. The receiving party shall maintain the confidentiality of the Confidential Information and will not disclose such information to any third party without the prior written consent of the disclosing party. The receiving party will only use the Confidential Information internally for the purposes contemplated hereunder. The obligations in this Section shall not apply to any information that: (a) is made generally available to the public without breach of this Agreement, (b) is developed by the receiving party independently from and without reference to the Confidential Information, (c) is disclosed to the receiving party by a third party without restriction, or (d) was in the receiving party’s lawful possession prior to the disclosure and was not obtained by the receiving party either directly or indirectly from the disclosing party. The receiving party may disclose Confidential Information as required by law or court order; provided that, the receiving party provides the disclosing with prompt written notice thereof and uses the receiving party’s best efforts to limit disclosure. At any time, upon the disclosing party’s written request, the receiving party shall return to the disclosing party all disclosing party’s Confidential Information in its possession, including, without limitation, all copies and extracts thereof.
### 5. INDEMNIFICATION
1. **Indemnification by Customer**. Customer will defend, indemnify, and hold Vivgrid, its affiliates, suppliers and licensors harmless and each of their respective officers, directors, employees and representatives from and against any claims, damages, losses, liabilities, costs, and expenses (including reasonable attorneys’ fees) arising out of or relating to any third party claim with respect to: (a) Customer Data; (b) breach of this Agreement or violation of applicable law by Customer; or (c) alleged infringement or misappropriation of third-party’s intellectual property rights resulting from Customer Data.
2. **Indemnification by Vivgrid**. Vivgrid will defend, indemnify, and hold Customer harmless from and against any third party claims, damages, losses, liabilities, costs, and expenses (including reasonable attorneys’ fees) arising from claims by a thirty party that Customer’s use of the Service directly infringes or misappropriates a third party’s United States (or Berne Convention signatory country) intellectual property rights (an “Infringement Claim”). Notwithstanding any other provision in this Agreement, Vivgrid shall have no obligation to indemnify or reimburse Customer with respect to any Infringement Claim to the extent arising from: (a) the combination of any Customer Data with the Service; (b) the combination of any products or services, other than those provided by Vivgrid to Customer under this Agreement, with the Service; or (c) non-discretionary designs or specifications provided to Vivgrid by Customer that caused such Infringement Claim. Customer agrees to reimburse Vivgrid for any and all damages, losses, costs and expenses incurred as a result of any of the foregoing actions.
3. **Notice of Claim and Indemnity Procedure**. In the event of a claim for which a party seeks indemnity or reimbursement under this Section 5 (each an “Indemnified Party”) and as conditions of the indemnity, the Indemnified Party shall: (a) notify the indemnifying party in writing as soon as practicable, but in no event later than thirty (30) days after receipt of such claim, together with such further information as is necessary for the indemnifying party to evaluate such claim; and (b) the Indemnified Party allows the indemnifying party to assume full control of the defense of the claim, including retaining counsel of its own choosing. Upon the assumption by the indemnifying party of the defense of a claim with counsel of its choosing, the indemnifying party will not be liable for the fees and expenses of additional counsel retained by any Indemnified Party. The Indemnified Party shall cooperate with the indemnifying party in the defense of any such claim. Notwithstanding the foregoing provisions, the indemnifying party shall have no obligation to indemnify or reimburse for any losses, damages, costs, disbursements, expenses, settlement liability of a claim or other sums paid by any Indemnified Party voluntarily, and without the indemnifying party’s prior written consent, to settle a claim. Subject to the maximum liability set forth in Section 7, the provisions of this Section 5 constitute the entire understanding of the parties regarding each party’s respective liability under this Section 5, including but not limited to Infringement Claims (including related claims for breach of warranty) and each party’s sole obligation to indemnify and reimburse any Indemnified Party.
### 6. WARRANTIES
1. **Warranty**. The Service, when used by Customer in accordance with the provisions of this Agreement and in compliance with the applicable Documentation, will perform, in all material respects, the functions described in the Documentation during the Term.
2. **Exclusive Remedies**. Customer shall report to Vivgrid, pursuant to the notice provision of this Agreement, any breach of the warranties set forth in this Section 6. In the event of a breach of warranty by Vivgrid under this Agreement, Customer’s sole and exclusive remedy, and Vivgrid’s entire liability, shall be prompt correction of any material non-conformance in order to minimize any material adverse effect on Customer’s business.
3. **Disclaimer of Warranty**. Vivgrid does not represent or warrant that the operation of the Service (or any portion thereof) will be uninterrupted or error free, or that the Service (or any portion thereof) will operate in combination with other hardware, software, systems or data not provided by Vivgrid, except as expressly specified in the applicable Documentation. CUSTOMER ACKNOWLEDGES THAT, EXCEPT AS EXPRESSLY SET FORTH IN THIS SECTION 6.1, VIVGRID MAKES NO EXPRESS OR IMPLIED REPRESENTATIONS OR WARRANTIES OF ANY KIND WITH RESPECT TO THE SERVICE OR SERVICES, OR THEIR CONDITION. VIVGRID IS FURNISHING THE WARRANTIES SET FORTH IN THIS SECTION 6.1 IN LIEU OF, AND VIVGRID HEREBY EXPRESSLY EXCLUDES, ANY AND ALL OTHER EXPRESS OR IMPLIED REPRESENTATIONS OR WARRANTIES, WHETHER UNDER COMMON LAW, STATUTE OR OTHERWISE, INCLUDING WITHOUT LIMITATION ANY AND ALL WARRANTIES AS TO MERCHANTABILITY, FITNESS FOR A PARTICULAR PURPOSE, SATISFACTORY QUALITY OR NON-INFRINGEMENT OF THIRD-PARTY RIGHTS.
### 7. LIMITATION OF LIABILITY
IN NO EVENT SHALL VIVGRID BE LIABLE FOR ANY, LOST PROFITS, BUSINESS INTERRUPTION, REPLACEMENT SERVICE OR OTHER SPECIAL, INCIDENTAL, CONSEQUENTIAL, PUNITIVE OR INDIRECT DAMAGES, HOWEVER CAUSED AND REGARDLESS OF THEORY OF LIABILITY. VIVGRID’S LIABILITY FOR ALL CLAIMS ARISING UNDER THIS AGREEMENT, WHETHER IN CONTRACT, TORT OR OTHERWISE, SHALL NOT EXCEED THE AMOUNT OF FEES PAID OR PAYABLE BY CUSTOMER UNDER THE APPLICABLE SERVICE DESCRIPTION OR SERVICE ORDER DURING THE TWELVE (12) MONTH PERIOD PRECEDING THE CLAIM.
### 8. MISCELLANEOUS
1. **Export Control**. Customer hereby certifies that Customer will comply with all current applicable export control laws. Customer agrees to defend, indemnify and hold Vivgrid harmless from any liability for Customer’s violation of any applicable export control laws.
2. **Compliance with Laws**. Customer shall comply with all applicable laws and regulations in its use of any Service, including without limitation the unlawful gathering or collecting, or assisting in the gathering or collecting of information in violation of any privacy laws or regulations. Customer shall, at its own expense, defend, indemnify and hold harmless Vivgrid from and against any and all claims, losses, liabilities, damages, judgments, government or federal sanctions, costs and expenses (including attorneys’ fees) incurred by Vivgrid arising from any claim or assertion by any third party of violation of privacy laws or regulations by Customer or any of its agents, officers, directors or employees.
3. **Assignment**. Neither party may transfer and assign its rights and obligations under this Agreement without the prior written consent of the other party. Notwithstanding the foregoing, Vivgrid may transfer and assign its rights under this Agreement without consent from the other party in connection with a change in control, acquisition or sale of all or substantially all of its assets.
4. **Force Majeure**. Neither party shall be responsible for failure or delay in performance by events out of their reasonable control, including but not limited to, acts of God, Internet outage, terrorism, war, fires, earthquakes and other disasters (each a “Force Majeure”). Notwithstanding the foregoing: (i) Customer shall be liable for payment obligations for Service rendered; and (ii) if a Force Majeure continues for more than thirty (30) days, either party may to terminate this agreement upon written notice to the other party.
5. **Notice**. All notices between the parties shall be in writing and shall be deemed to have been given if personally delivered or sent by registered or certified mail (return receipt), or by recognized courier service.
6. **No Agency**. Both parties agree that no agency, partnership, joint venture, or employment is created as a result of this Agreement. Customer does not have any authority of any kind to bind Vivgrid.
7. **Governing Law**. This Agreement shall be governed exclusively by, and construed exclusively in accordance with, the laws of the United States and the State of California, without regard to its conflict of laws provisions. The federal courts of the United States in the Northern District of California and the state courts of the State of California shall have exclusive jurisdiction to adjudicate any dispute arising out of or relating to this Agreement. Each party hereby consents to the jurisdiction of such courts and waives any right it may otherwise have to challenge the appropriateness of such forums, whether on the basis of the doctrine of forum non conveniens or otherwise. The United Nations Convention on Contracts for the International Sale of Goods shall not apply to this Agreement or any purchase order issued under this Agreement.
8. **Publicity**. Customer hereby authorizes Vivgrid to identify Customer as a Vivgrid Customer, and use Customer’s name, mark and/or logo on Vivgrid’s website and/or in Vivgrid’s marketing materials with respect to the same. In addition, Customer agrees to participate in certain publicity activity, such as a case study, customer quote, and joint press release all as further described in the corresponding Service Order or Service Description.
9. **Entire Agreement**. This Agreement is the complete and exclusive statement of the mutual understanding of the parties and supersedes and cancels all previous written and oral agreements, communications, and other understandings relating to the subject matter of this Agreement, and all waivers and modifications must be in a writing signed by both parties, except as otherwise provided herein. Any term or provision of this Agreement held to be illegal or unenforceable shall be, to the fullest extent possible, interpreted so as to be construed as valid, but in any event the validity or enforceability of the remainder hereof shall not be affected. In the event of a conflict between this Agreement and the applicable Service Description or Service Order document, the terms of this Agreement shall control.
---
# Decouple the Agent: Why Prompts, Tools, and Models Don't Belong in Your Client
> Source: https://vivgrid.com/blog/decoupling-prompts-tools-models-from-agent-client
A best-practices guide for enterprise AI agents: treat system prompts as runtime config, run tools as Managed Skills, and make models a platform decision — so you can debug faster, ship AI improvements without app releases, and fix production behavior from the console in minutes.
Here is the agent client most teams ship:
```typescript
// agent.ts — everything your agent is, compiled into the binary
const SYSTEM_PROMPT = `You are a support agent for Acme Corp.
Always answer in English. Never discuss pricing...`; // 400 more lines
const MODEL = 'gpt-5.5'; // chosen in a meeting, six months ago
const tools = [
{ type: 'function', function: { name: 'lookup_order', /* ... */ } },
{ type: 'function', function: { name: 'issue_refund', /* ... */ } },
]; // executed locally, with API keys from .env
const res = await openai.chat.completions.create({
model: MODEL,
messages: [{ role: 'system', content: SYSTEM_PROMPT }, ...history],
tools,
});
```
It works. It demos well. And every capitalized constant in that file is a release cycle waiting to happen:
- The prompt needs a tweak? **Release.**
- A tool has a bug? **Release.**
- The model gets deprecated, repriced, or outperformed? **Release** — after someone greps every repo that hardcoded it.
Your agent's *interface* changes maybe twice a year. Its *intelligence* needs to change weekly. Coupling them means the slow one sets the pace for both.
The fix is one rule:
> **The client holds a session, not a brain.** System prompts, tools, and models are server-side concerns. The client renders the conversation.
Here is the same agent as a thin client against Vivgrid:
```typescript
// agent.ts — the whole thing
const openai = new OpenAI({
baseURL: 'https://api.vivgrid.com/v1',
apiKey: process.env.VIVGRID_TOKEN,
});
const res = await openai.chat.completions.create({
messages: history, // that's it
});
```
Notice what's missing: no `model`, no `tools`, no system prompt. They didn't disappear — they moved to where they can change without shipping software. Let's walk through each one.
## Best practice #1: Treat the system prompt as runtime config
A system prompt is not source code. It is operational behavior — closer to a feature flag than to a function. It will be edited by people who don't write TypeScript (product, legal, support leads), and it will need to change at the worst possible time.
The 2 a.m. scenario: your agent starts confidently quoting a discount policy that was retired last quarter. With the prompt compiled into the client, the fix is a hotfix release and an app-store review — your agent keeps misquoting policy for days.
With the prompt managed in the [Vivgrid Console](https://console.vivgrid.com), the fix is: edit, save. Every conversation that starts after that second uses the corrected prompt. The incident lasts minutes, and the postmortem includes who changed what, when.
The deeper win is iteration. When prompt changes are free, your team actually makes them — tightening tone, patching edge cases, encoding what support learned this week. When every change costs a release, the prompt fossilizes.
## Best practice #2: Make the model a platform decision — and enforce it
Hardcoding a model ID feels harmless — it's one string. But that string is a pricing commitment, a latency profile, a compliance surface, and a deprecation timeline, all chosen at compile time and frozen until the next release.
It also shouldn't be every developer's decision. When any engineer can switch the production agent to whatever model they benchmarked last night, your cost and behavior drift one commit at a time. Model selection is a governance decision: run the evals, compare cost and latency on real traffic, then switch — for every agent at once, in the console, with no client change.
A policy is only as good as its enforcement, and enforcement here has two halves:
- **Clients should not send `model`.** A thin client has no business hardcoding one (look back at the thin client above — it doesn't).
- **The server should not trust it if they do.** The gateway ignores any client-supplied `model` and replaces it with the value configured for the project.
```typescript
// even if a stray client sends one…
await openai.chat.completions.create({
model: 'gpt-4o-mini', // ignored — the console's choice serves the request
messages: history,
})
```
Why enforce instead of merely document? Because any honored client value is a bypass. An old install pinning a deprecated model can block your migration. A leaked token that's allowed to pick models can run up your bill on the most expensive one.
Done right, this cuts both ways:
- **Upgrades**: a frontier model ships, your evals confirm it wins, and production is on it the same day — not next quarter when the release train leaves.
- **Stability**: nobody "just tries" a model in production, because the client physically cannot specify one.
Developers lose nothing except a foot-gun — you still experiment freely against dev projects. On Vivgrid, the model that serves a request is the one set in the console, and the response's `model` field reports what actually ran: clients keep full transparency without holding any authority. Treat the request field as a hint at best, and configuration as truth.
## Best practice #3: Run tools as Managed Skills
Tools are where agents touch the real world — and where client-side architecture hurts most. A tool that runs on the client needs its credentials on the client, ships its bugs to every install, and logs its failures to a console nobody is watching.
On Vivgrid, a tool is a strongly typed skill. Here's a complete one:
```ts
// src/app.ts — a Managed Skill
export const description = `Get current weather for a given city.`
export type Argument = {
city: string
}
export async function handler(args: Argument) {
return await getWeather(args.city)
}
```
Deploy it to every region at once:
```sh
viv deploy . --env WEATHER_API_KEY=xxx
```
Three things just happened that your client-side version couldn't do:
1. **Every agent got the tool instantly.** No version skew, no waiting for users to update. Fix a bug at 10:00, and the 10:01 conversations run the fix.
2. **The API key went server-side.** `--env` lives with the function in your cloud, not in a laptop's `.env` file. Clients hold a token, not your secrets.
3. **Every invocation became observable.** Arguments in, results out, latency, cost — centrally logged. When a tool misbehaves, you read the trace in the console instead of asking a customer to send screenshots.
That last one changes debugging more than any framework ever will. The worst bugs in agent systems live in the seams — the model called the tool with arguments you didn't expect, or interpreted a result you didn't anticipate. When every seam is recorded, those bugs go from unreproducible to obvious.
## What you just gained
For developers, the day-to-day is simply smaller. The client codebase shrinks to UI and session handling. Debugging starts at one console with full traces instead of grepping logs across machines. Prompt tweaks, tool fixes, and model swaps stop being your release problem.
For the business, the product gains something it has never had before: **control that survives launch.**
| Production event | Coupled client | Decoupled (Vivgrid) |
|---|---|---|
| Prompt misbehaves | Hotfix release, app review, days | Console edit, minutes |
| Tool bug | Ship to every install, wait for adoption | `viv deploy`, live everywhere |
| Model deprecated or outperformed | Grep, change, release, migrate | Eval, switch in console |
| "What did the agent actually do?" | Scattered client logs | Full trace, one place |
Ship the interface once. Iterate the intelligence forever.
---
*Vivgrid is the Managed Skills platform: cloud-hosted LLM function calling that lets enterprise AI agents run their tools in the cloud — with observability, evaluation, and globally distributed inference built in. Start with the [Quick Start](/docs/quick-start), or talk to us at [hi@vivgrid.com](mailto:hi@vivgrid.com).*
---
# Vivgrid Skills Marketplace - Autosend
> Source: https://vivgrid.com/blog/marketplace-autosend
Automate customer emails from your AI agents using Autosend MCP on Vivgrid. Generate and send transactional emails, notifications, and more — no code needed.
## Overview
Enable your AI agent to generate and send professional emails to customers using [AutoSend](https://autosend.com). This integration allows you to automate transactional emails, notifications, and customer communications with AI-generated content.
## Use Cases
### Dynamic HTML Email Generation
Generate and send custom HTML emails with dynamic content. In this example, we'll send a credit balance notification with a payment link.
 ```markdown Send html format email wrap
- Write a HTML-formatted email addressed to fan.wei.xiao@gmail.com, referring to the recipient as Vincent Van.
- Inform him that his account credits are nearly depleted (98% used) and he needs to top up promptly to prevent service interruption.
- Include a CTA button that links to: https://checkout.stripe.com/c/pay/cs_livexxxxxx
- The primary theme color should be #33D78E
- The email should be written on behalf of the Acme Customer Success Team
```
**Testing with Alchemist Tool:**
You can test this integration using the [Alchemist Tool](https://alchemist.vivgrid.com):
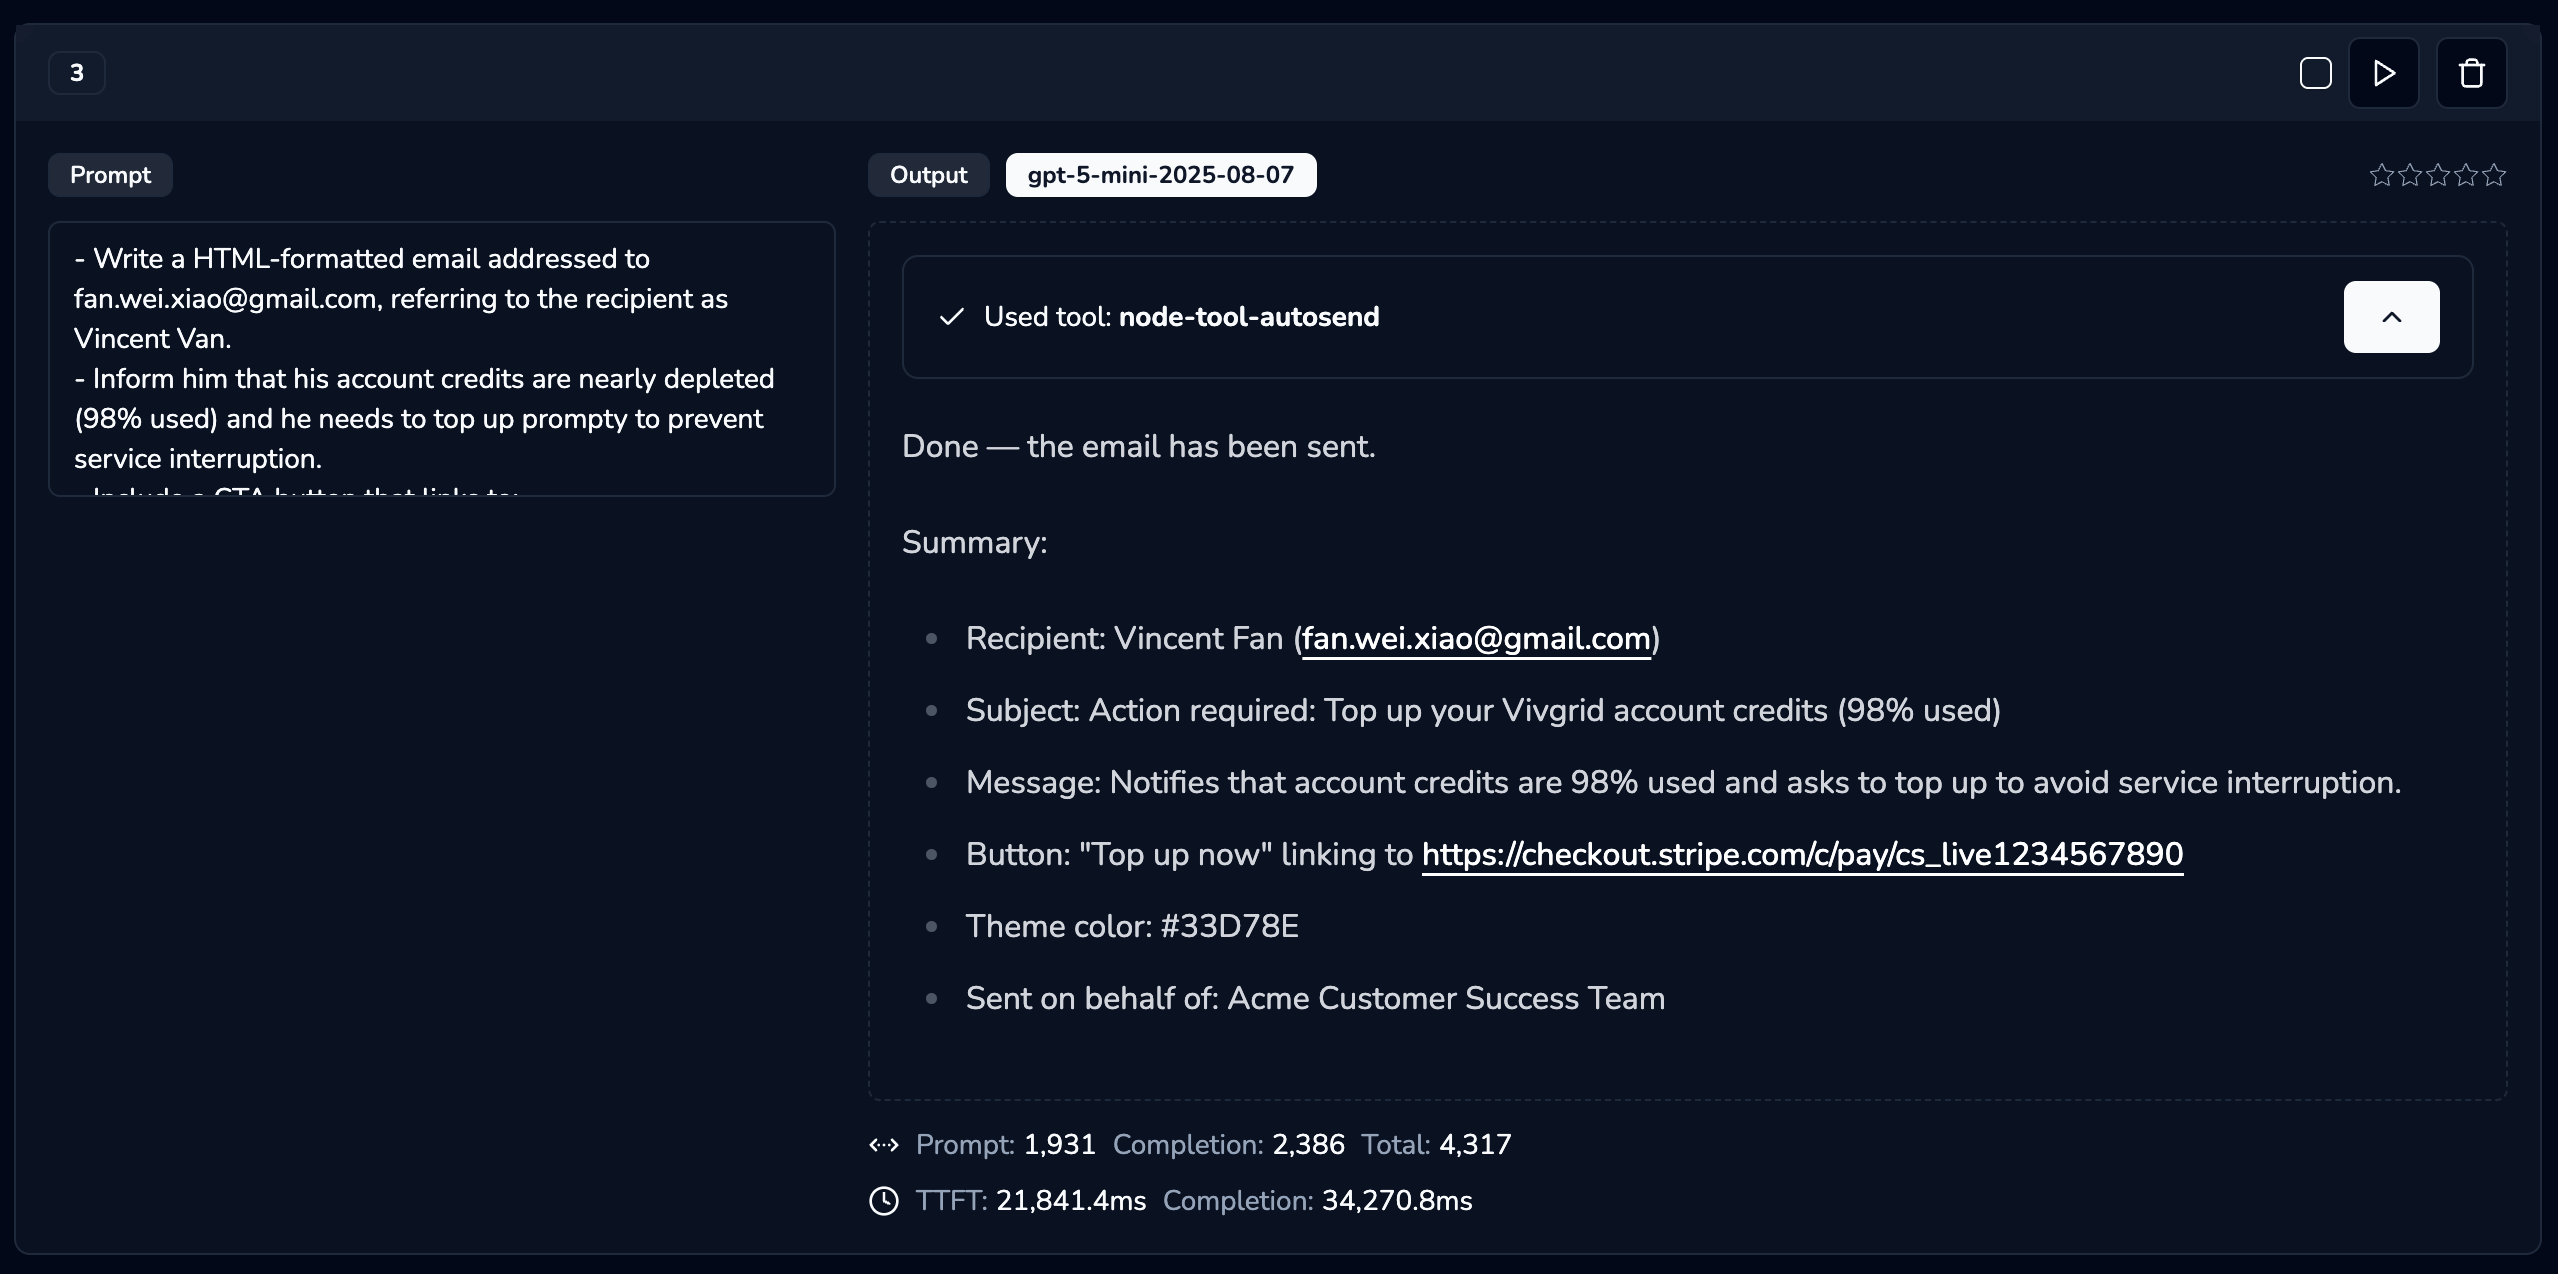 **Result:**
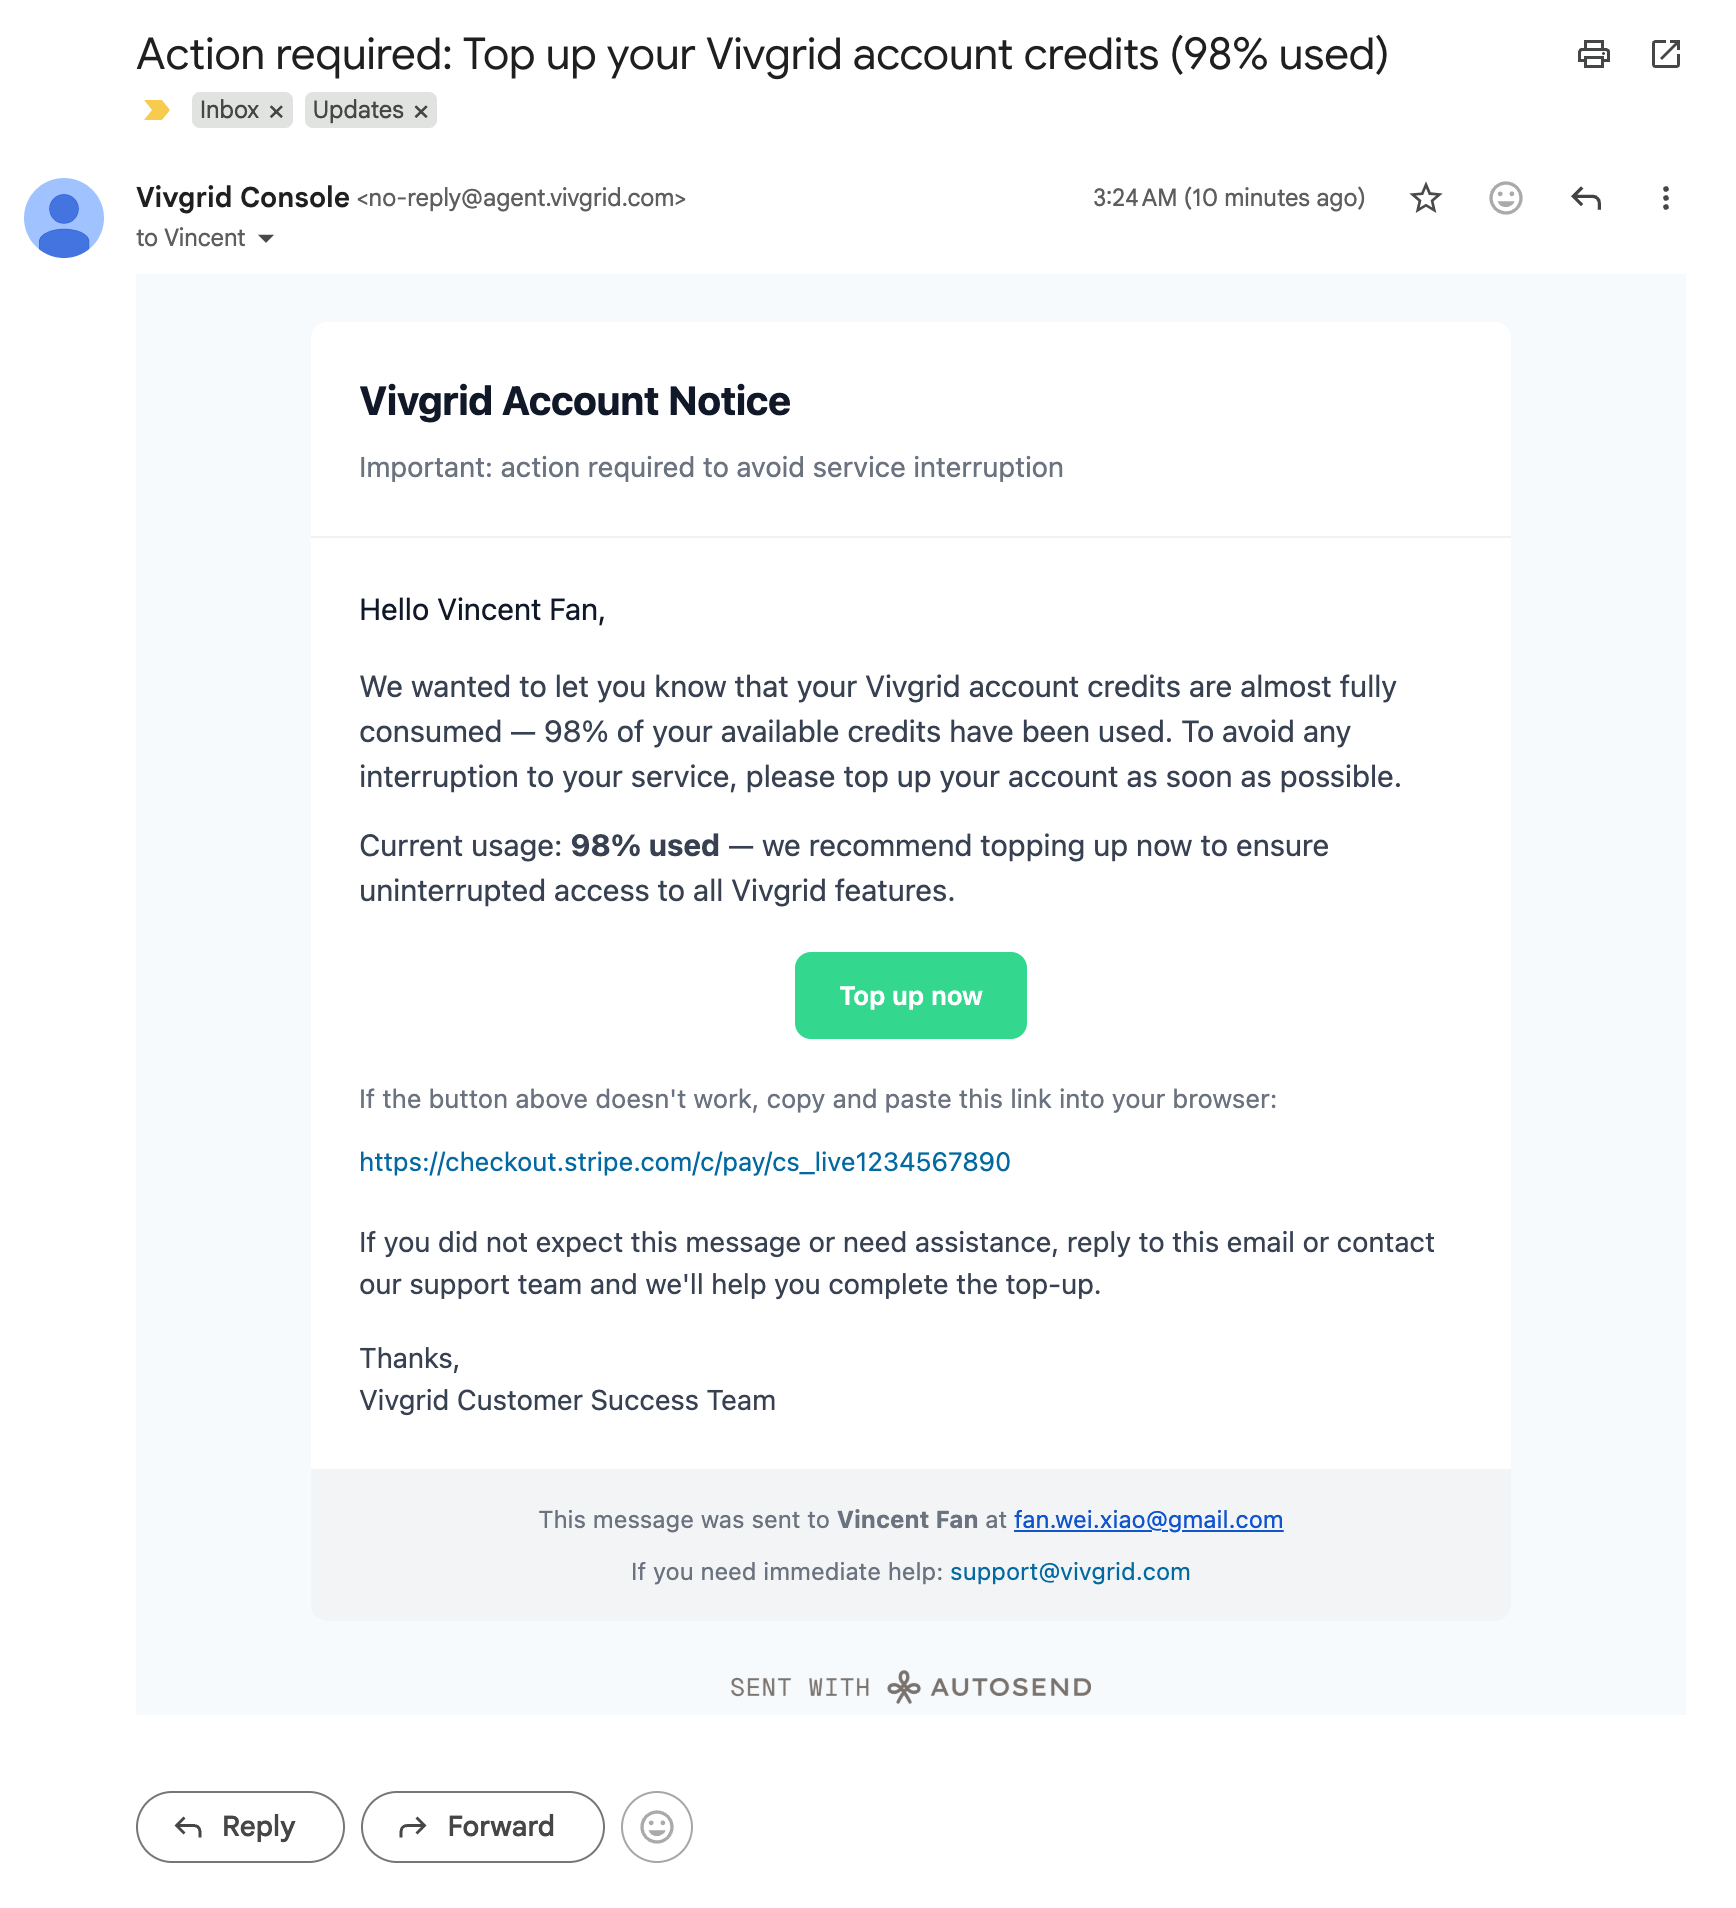 ### Template-Based Email Sending
Send emails using pre-configured templates for consistent branding and messaging.
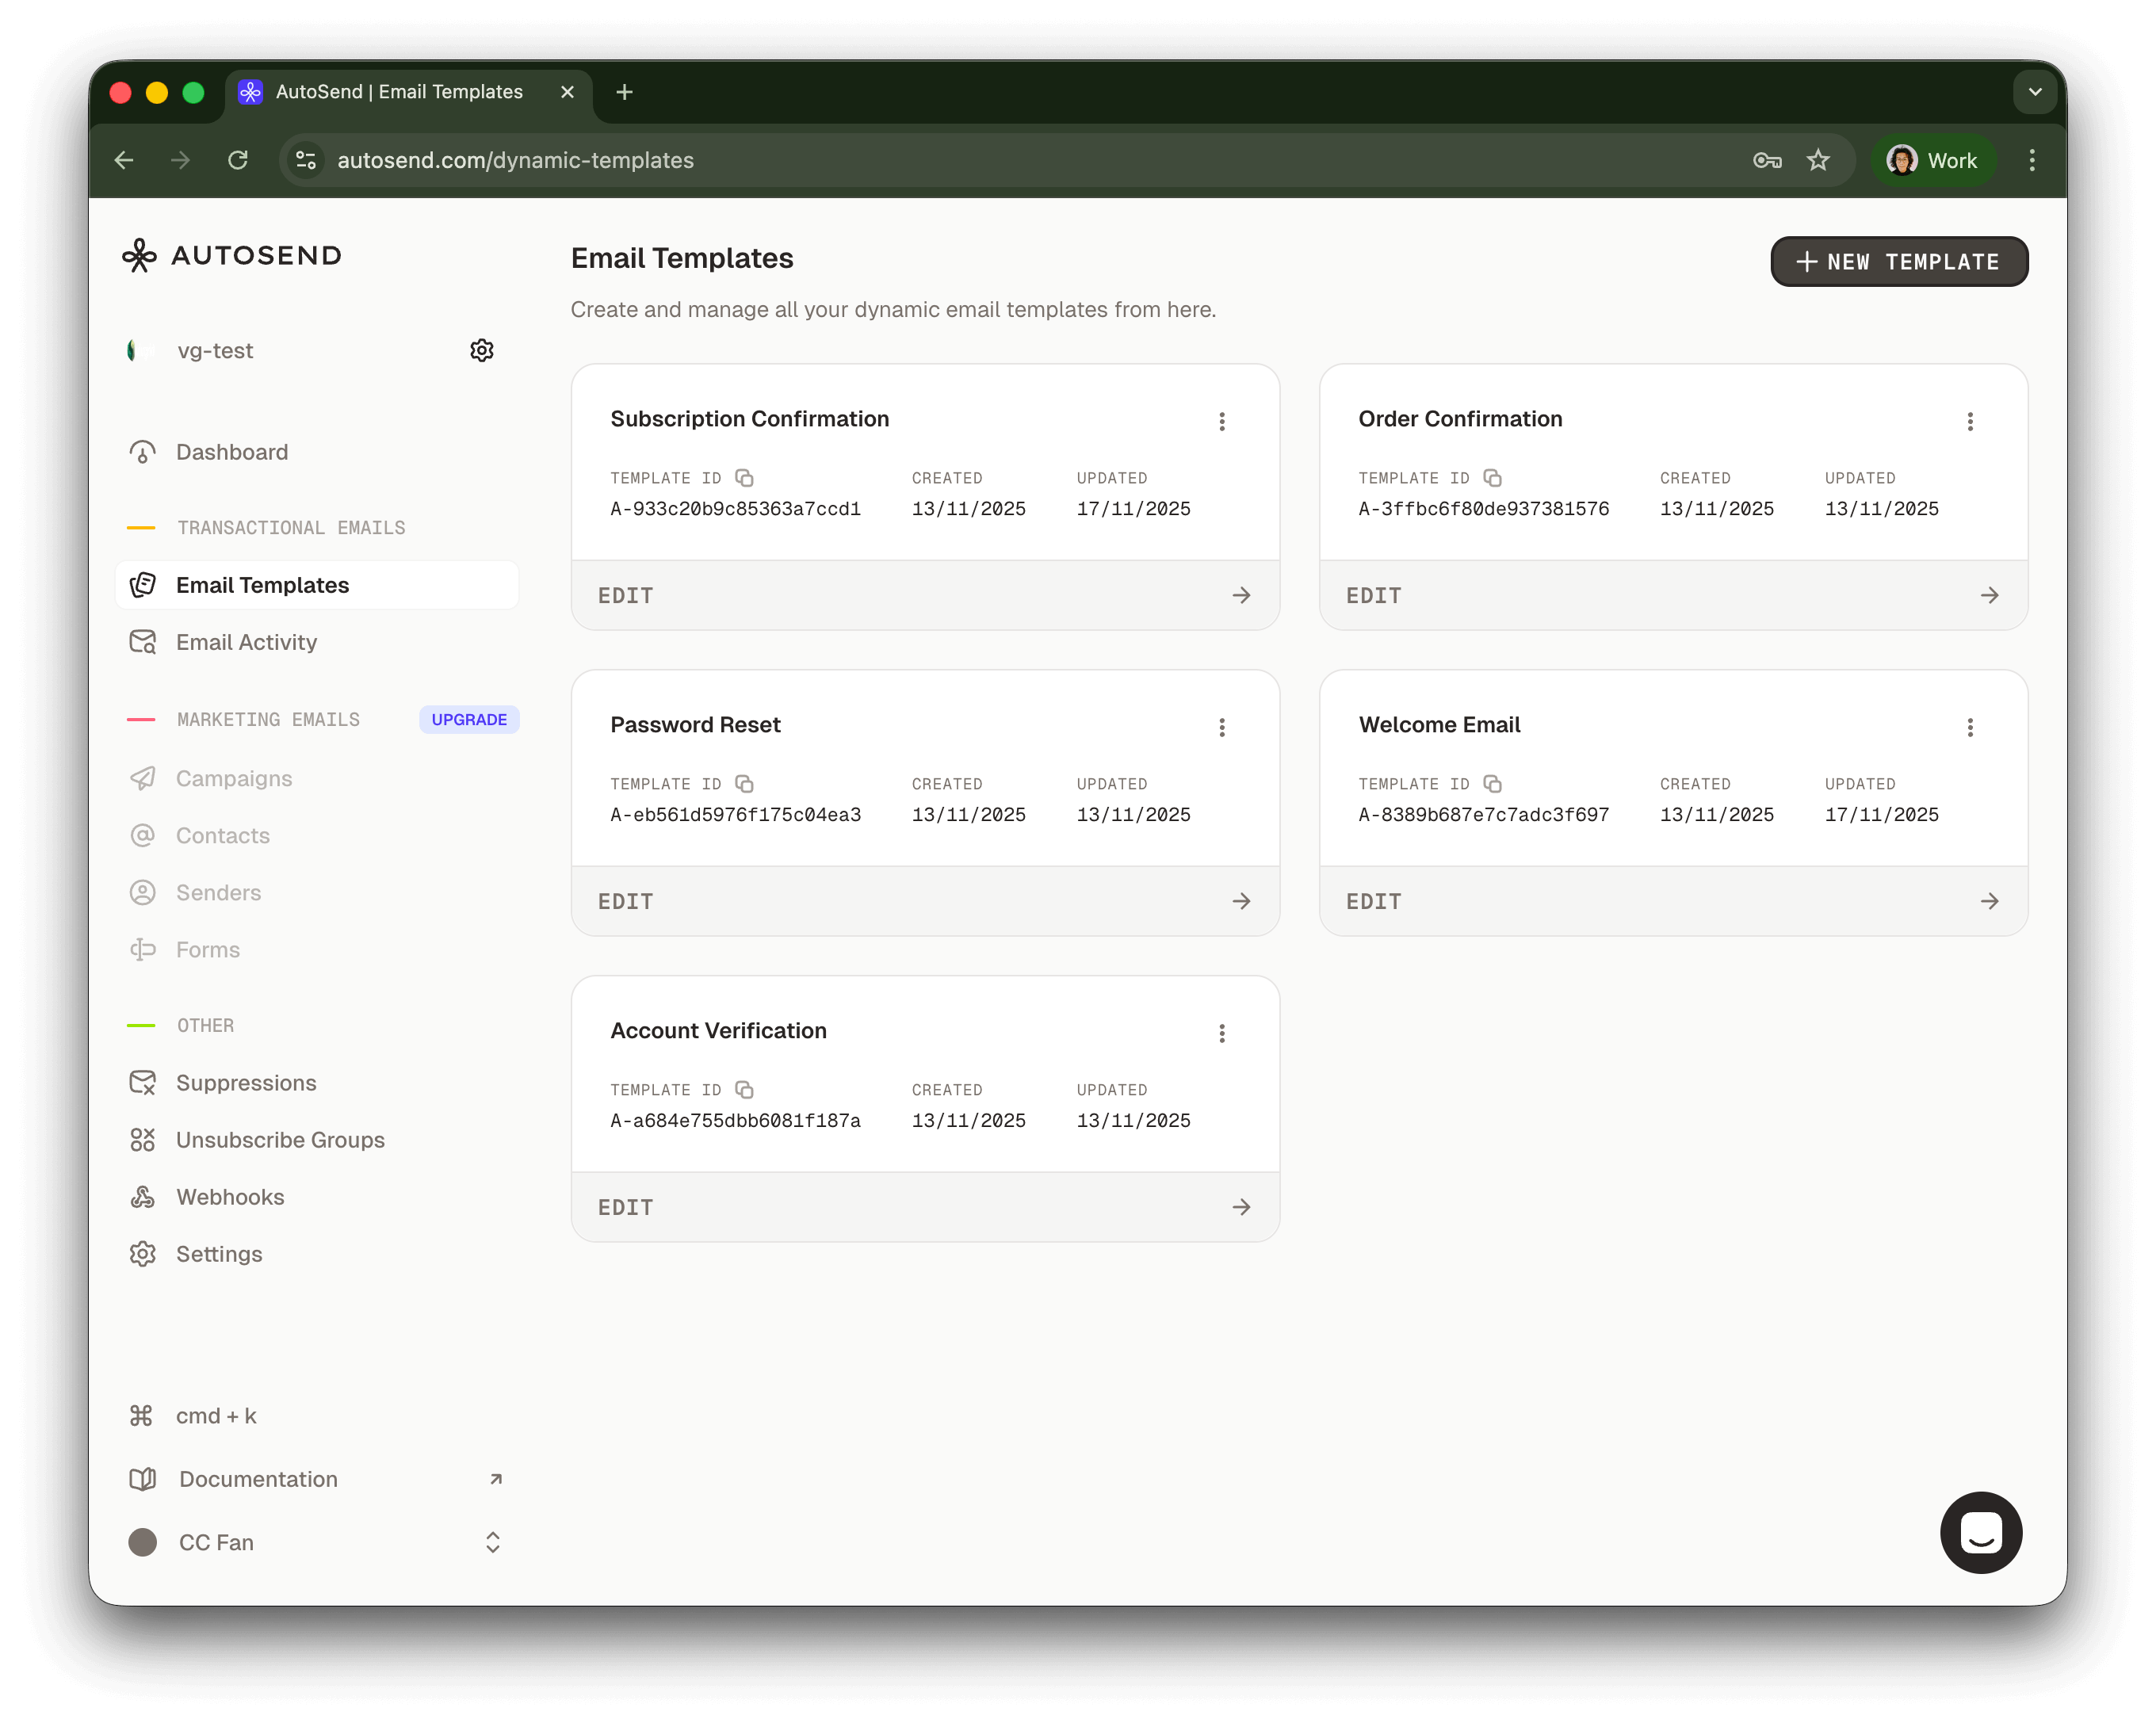 Using the OpenAI SDK:
```markdown INSTRUCTION wrap
- Send an email to Vincent Fan at fanweixiao+test@gmail.com.
- Use the email template with template ID: A-8389b687e7c7adc3f697.
- The email should be sent on behalf of the Vivgrid Customer Success Team.
- Use #33D78E as the primary theme color.
```
```javascript Send template email icon="square-js" lines
import OpenAI from 'openai'
const client = new OpenAI({
apiKey: 'viv-xxxxxxxxxx',
baseURL: 'https://api.vivgrid.com/v1',
})
const chatCompletion = await client.chat.completions.create({
messages: [{ role: 'user', content: INSTRUCTION }],
stream: true,
})
for await (const chunk of chatCompletion) {
const content = chunk.choices[0]?.delta?.content
if (content) {
console.log(content)
}
}
```
## Example Code
A complete example implementation is available on GitHub:
[https://github.com/yomorun/llm-function-calling-examples/tree/main/node-tool-autosend](https://github.com/yomorun/llm-function-calling-examples/tree/main/node-tool-autosend)
## Deploy yours
The following environment variables are required to configure the Autosend integration:
- `AUTOSEND_API_KEY`: Your AutoSend API key
- `AUTOSEND_FROM_EMAIL`: The sender email address (domain must be configured in AutoSend dashboard)
- `AUTOSEND_FROM_NAME`: Display name for the sender
- `AUTOSEND_REPLY_TO_EMAIL`: Email address for replies
- `AUTOSEND_REPLY_TO_NAME`: Display name for reply address
Prepare your `vivgrid.yml` file before deploying your application, the secret can be found in your [Vivgrid Console](https://console.vivgrid.com/):
```yaml vivgrid.yml
tool: send_email
secret: viv-xxxxxxxxxx
```
Then deploy your application with your configuration to [Vivgrid](https://vivgrid.com):
```sh
viv deploy . --env AUTOSEND_API_KEY=AS_xxxxxxxxxxxxxxx \
--env AUTOSEND_FROM_EMAIL=no-reply@acme.com \
--env AUTOSEND_FROM_NAME="Acme Console" \
--env AUTOSEND_REPLY_TO_EMAIL=hi@acme.com \
--env AUTOSEND_REPLY_TO_NAME="Acme Support"
```
Your AutoSend MCP server will be available at `https://api.vivgrid.com/mcp/v1//sse`
---
# Why Enterprise Agents Can't Run Tools on Laptops
> Source: https://vivgrid.com/blog/why-enterprise-agents-cant-run-tools-on-laptops
Personal agents run tools locally. Enterprise agents can't — credentials, auditing, consistency, and iteration speed all break at company scale. The answer is Managed Skills: agent tools that run in the cloud.
On August 12, 1853, two trains collided head-on near Valley Falls, Rhode Island, killing fourteen people. The cause was not a broken rail or a reckless engineer. It was a conductor's pocket watch, running about two minutes slow.
Every town in America kept its own time then, set by its own solar noon. Every conductor ran trains by the watch in his own pocket. For an individual, that watch was *correct* — it told the time of the place he lived. For a railroad running thousands of trains on shared track, it was a catastrophe waiting on every schedule.
The railroads' answer was not better watches. On November 18, 1883 — remembered as the Day of Two Noons — North American railroads abandoned local time altogether: one standard time, calibrated at the observatory, distributed by telegraph to every station on the network. Set once, correct everywhere, instantly. Conductors kept their watches; the watches stopped being the source of truth.
What was right for the individual had to be re-architected for the institution. Keep that story in mind, because the AI industry is living it again.
Personal agents run tools on laptops. Enterprise agents can't.
That single difference explains why so many AI agent pilots impress in a demo and stall in production — and it defines the next category of agent infrastructure.
## The pattern everyone copied
The most successful AI agents today are personal ones: coding assistants, desktop copilots, research agents. They share an architecture — the model reasons in the cloud, but the tools run locally. The agent reads your files, calls APIs with your keys, executes commands on your machine.
For an individual, this is perfect. Your laptop already has your credentials, your context, your permissions. There is nothing to deploy and no one else to coordinate with.
So when companies started building their own agents, they copied the pattern. Tools bundled into the client. API keys in local configs. Skills shipped with every release.
It works — right up until the agent has to serve a business instead of a person.
## Four ways the laptop pattern breaks
**Credentials.** A tool that runs on the client needs its secrets on the client. Database credentials, payment APIs, internal service tokens — distributed to every machine that runs the agent, including ones the company doesn't control. Every laptop becomes part of your attack surface. No security team accepts this, and they're right not to.
**Auditing.** When tools execute locally, there is no central record of what your agents actually did. Which customer data was read? Which actions were taken, by which agent, on whose behalf? Compliance frameworks require answers. Local execution has none.
**Consistency.** A hundred employees on six client versions means a hundred subtly different agents — a hundred conductors on a hundred private watches. The bug you fixed on Monday is still running on someone's machine on Friday. You can't reason about behavior you can't pin down.
**Iteration speed.** This is the one that quietly kills ROI. When a skill lives in the client, every improvement ships through a release cycle: build, review, publish, wait for adoption. The feedback you gathered today reaches your users in weeks. Enterprises don't invest in agents to own a chatbot — they invest because agents are supposed to compound: learn from production, improve, and grow revenue. An agent that iterates on a release cycle can't compound.
## Agents are a revenue investment, not a tech demo
It's worth stating plainly: the business case for enterprise agents is growth. An agent that closes support tickets, qualifies leads, or operates a workflow is an investment with an expected return — and the return curve is set by iteration speed.
The loop that matters is short: observe what customers actually ask, find where the agent wins or loses, improve it, ship the improvement. Run that loop weekly and the agent compounds. Run it quarterly and it decays. The laptop pattern locks you into quarterly.
## The missing piece: Managed Skills
The fix is architectural, and it is the railroads' move: take the thing that must be canonical out of private pockets, put it under central governance, and distribute it to the entire network instantly. For enterprise agents, that thing is the tools. **Move them to the server side.**
Vivgrid is the Managed Skills platform: cloud-hosted LLM function calling that lets enterprise AI agents run their tools in the cloud — with observability, evaluation, and globally distributed inference built in.
Managed Skills means your agent's tools are deployed as skills your organization controls:
- **Update once, live everywhere.** Change a skill in the cloud and every agent has it immediately. No release cycle, no version skew, no waiting on app stores.
- **Secrets never leave your cloud.** API keys and credentials stay server-side. Clients hold a connection, not the keys to your business.
- **Audited by default.** Every skill invocation is logged centrally — who, what, when, at what cost. Compliance gets a record instead of a shrug.
- **Memory that matches the org chart.** Consumer agent memory is scoped to a user. Enterprise agents need memory scoped to the agent and the organization, so knowledge compounds across the company instead of fragmenting across sessions.
- **Insight feeds iteration.** Because skills run centrally, you can see what customers ask, what each answer costs, and where agents win or lose — and turn that insight into a same-day improvement.
The client keeps what belongs to the client: the interface. System prompts, models, tools, and memory live server-side, decoupled — so the people responsible for the agent's behavior can change it at the speed of a config push, not a software release.
## What this looks like in practice
| | Tools on the client | Managed Skills |
|---|---|---|
| Shipping an improvement | Release cycle (weeks) | Cloud update (minutes) |
| Credentials | On every machine | Server-side only |
| Audit trail | None | Every invocation logged |
| Version consistency | As many versions as installs | One, everywhere |
| Memory scope | Per user | Per agent / per organization |
| Iteration loop | Quarterly | Weekly or faster |
## The manifesto, in one paragraph
Personal agents proved what agents can do. Enterprise agents will prove what they're worth — but only if they escape the laptop. Tools, prompts, models, and memory belong in the cloud, managed by the organization, observable in production, and improvable in minutes. That is what Managed Skills means, and it's what we built Vivgrid to do.
The railroads stopped trusting pocket watches in 1883. It's time agents stopped trusting laptops.
---
*Vivgrid is built by the team behind the open-source [Yomo](https://github.com/yomorun/yomo) framework. Start free at [vivgrid.com](https://vivgrid.com), or talk to us about enterprise deployment at [hi@vivgrid.com](mailto:hi@vivgrid.com).*